Tuesday, 17 November
17:28
The Value of Human Expertise in The Software Factory [Radar]
“Any sufficiently advanced technology is indistinguishable from magic.” – Arthur C. Clarke
Most developers now write less code by hand. Gergely Orosz recently posted that modern software engineering is no longer done without LLMs and will no longer be done without them. Some miss writing code, while others question how much of the code that agents produce should be read. Writing and reading code gave a lot of developers satisfaction and identity, and as Kent Beck has put it, a sense of competence. I saw this in real time.
Ten years ago, I’d sit at conferences and feel a sense of wonder whenever anyone was brave enough to do a live demo. I felt gleeful when they wrote lines of code, went back to fix mistakes, and made something cool and interesting appear on the screen in front of me. It was magical, and I’m sure that magic is why a lot of developers got into this industry. I can partly understand the sense of loss that people are experiencing. I saw magic, they were in charge of the craft of their code, and that hands-on task has now been given to agents. Where does that expertise go when AI is now writing so much of the code?
As Tim O’Reilly wrote in his recent Radar post, O’Reilly is a business built on cultivating and sharing human expertise. Our job is to find the high ground where that expertise still matters. For developers working in a new world of agentic software factories, I think the expertise you built writing and maintaining software hasn’t gone, it’s just moved. Your expertise now shapes how agents produce software and what evidence you need before we trust the result. To me, AI is enabling you to be magical faster.
Agents amplify whatever you give them, but you need to understand it in the first place. I couldn’t swarm a fleet of agents in the same way a developer can because I don’t have the expertise. You need to understand code. The expertise has gone to a new level of abstraction.
When I spoke recently with Avi Flombaum, the founder of Flatiron School, he agreed that developers’ value was never solely in writing or reading code. AI changes the mechanics, but experience still matters for understanding complex problem domains, articulating what needs to be built, and bringing judgment and ambition to the work. In a separate conversation with Ken Kousen, he pointed out, “We’ve been working with third-party code generators for years; we just called it outsourcing.” This new world of designing AI workflows, setting guardrails, and managing agents much as you would an engineering team, reveals a chance to use accumulated expertise more. It’s your software engineering expertise that matters.
Software factories make this shift especially visible. Companies are now putting agents to work across the development lifecycle, aiming to take work from an initial signal through implementation, validation, and deployment without a person at every step. But generating more code is only part of that process. Without changes elsewhere, you can burn a lot of tokens producing a pile of pull requests that someone still has to review. Anthropic’s AI-native SDLC playbook points out that speeding up implementation shifts pressure onto planning, testing, review, handoffs and approvals, and faster coding tools don’t speed those up on their own. Someone has to understand the whole process well enough to redesign it.
In a software factory, that judgment has to be built into the system. Humans design the workflow, define the conditions under which work can proceed, and decide which exceptions need their attention. Anthropic reports that Claude authors about 80% of the code merged into its codebase, alongside a review process that combines automated checks with human oversight according to risk.
The state of the code matters too. Adam Tornhill and the CodeScene research team found that across C++, Java, and Python codebases, agents working on unhealthy code used 35–45% more tokens to complete the same tasks. That makes refactoring the parts of a codebase agents touch most a sensible investment, but someone has to know which parts those are, decide what “better” looks like, and confirm that behavior hasn’t changed.
Context works the same way. In Port’s testing, giving agents structured context cut costs by about 58% compared with direct access to separate MCP servers. Adding instructions on where to find relevant information pushed the savings to around 80%. Those figures are specific to Port’s experiment, but the work behind them will be familiar to any experienced developer: knowing which relationships in a system matter, and keeping that knowledge accurate as the system changes. Testing tells you whether a particular change works, but evaluating the workflow tells you how reliably it produces acceptable changes and when a person needs to step in.
In Evals for AI Engineers, Shreya Shankar and Hamel Husain describe starting with real traces of what the system did. First comes open coding: reading the traces and writing short notes on what went wrong. Then comes axial coding: grouping those notes into failure categories based on what you actually see. A developer who has spent years debugging production systems will spot the failures that matter and set aside the ones that don’t far faster than someone who hasn’t. That’s where developers’ experience shows up now: in the problems they define, the standards they set, and the evidence they demand before anything ships.
Every shift in every industry has made some people miss the old ways, but the industry has survived. Back in December 2025 I wrote: “AI rewards strong engineering; it doesn’t replace it,” and I stand by that statement. Developers are still magical to me, even when they’re not the ones writing the code. I couldn’t build a software factory myself because I don’t have the years of experience it takes to know where agents should work, how to guardrail them, and how to judge what they produce. The developers who do are the ones I trust to build it. And, as Ben O’Mahony pointed out to me recently, “Those who have a lot of exposure to Agentic engineering have seen past the magic and are back to engineering!” It’s an exciting time to be involved.
Want to understand how to think about engineering craft in this new world? Join Avi Flombaum for his new series, The Agentic Rethink, starting Wednesday, Jan. 13, 2027, on the O’Reilly platform.
16:56
Redict deprecated in favor of Valkey [LWN.net]
Drew DeVault has announced that Redict, a fork of Redis that was created in response to Redis's 2024 license change, has been deprecated. He recommends switching to Valkey, the permissively licensed Redis fork supported by the Linux Foundation. The two projects are mutually compatible, so switching should be as simple as changing which package is installed and renaming the configuration file.
I had hoped to rally the Redis diaspora around a copyleft initiative, to protect ourselves from future rug-pulls, and made Redict to serve this purpose. However, with the valkey project's success, and Redis's return to a copyleft license, Redict was not able to build a sustainable community.
We recommend that Redict users switch to valkey, which uses a permissive license but has better long-term prospects. We advise against switching back to Redis; though it is once again open source, and copyleft, it uses a contributor license agreement which will facilitate another rug-pull when Redis has a bad financial quarter.
16:42
Podcast: How Claude Code allowed me to think big. We can have the web we want and we don't have to wait for a big company to do something to help the web, when all evidence of history is the exact opposite. They consume the goodness and we're left with yet another totally predictable tech mess. Hope this came out okay, I recorded it on a drive to Kingston, NY this morning.
16:21
Privacy's Defenders Podcast: Snowden Exposes NSA’s Lies [Deeplinks]
By 2013, EFF had spent seven years arguing in court that the National Security Agency was sweeping up ordinary Americans’ communications, including through the secret room that whistleblower Mark Klein had exposed. The government would neither confirm nor deny it, and outside the courtroom the public seemed to have moved on.
Then, in early June, documentary filmmaker Laura Poitras and journalist Glenn Greenwald mysteriously missed a Freedom of the Press Foundation board meeting at EFF’s offices. It turned out they were in Hong Kong, meeting an NSA contractor who had been secretly writing to Laura for months. His name was Edward Snowden, he had thousands of secret documents proving the government had in fact been spying on millions of Americans. When he subsequently revealed himself, a photo of him sitting behind his laptop – emblazoned with a big red EFF sticker – went worldwide.
Welcome to the fourth episode of “Privacy’s Defenders,” a podcast about the people – lawyers, journalists, hackers, and others – who’ve fought to secure your digital liberties since before most people even knew what the internet was.


(You can also find this episode on the Internet Archive and on YouTube.)
In this episode, former EFF Executive Director Cindy Cohn talks with Laura Poitras about how she got to that historic moment, including her years of expertise in communicating via encrypted channels. Freedom of the Press Foundation Executive Director Trevor Timm – a former EFF activist – shares his recollection of the day the first Snowden story broke. For EFF and its clients in Jewel v. NSA, Snowden’s documents were proof of what the government had spent years refusing to confirm. As Cindy puts it, “We were struggling along in the mud, and we felt like somebody gave us wings.”
It's the story of the lawyers who fought for your privacy, the government that lied about spying on you, and the whistleblower who blew it all wide open.
The “Privacy’s Defenders” podcast is a follow-up to Cindy’s book, “Privacy’s Defender: My Thirty-Year Fight Against Digital Surveillance,” bringing to life pivotal moments in the voices of those who fought for your rights. Sales of “Privacy’s Defender” benefit EFF, so pick up your copy today!
Joanne Elgart Jennings co-produced and created this podcast.
Jarrod Sport co-produced, mixed, and mastered it.
Corinne Ruff is our story editor.
We had additional help from Rachel Estabrook and Alison Broverman.
The original music was composed and performed by Nat Keefe of Hot Buttered Rum with Ben Andrews on the fiddle.
15:28
[$] Zellij manages terminal workspaces with style [LWN.net]
Zellij is a relatively new entrant in the terminal-multiplexer category. Like GNU Screen and tmux it gives users the ability to manage a workspace inside a terminal with split panes, provides session management, and so forth; but Zellij also includes a web server for browser access to a terminal session, is extensible via a plugin API, and is likely more beginner-friendly than its predecessors. Its most recent release, version 0.46, adds a standalone terminal emulator, a built-in inbox for notifications, and a settings screen so users can configure the application without fussing with configuration files. While the low version number might suggest that it is not yet ready for serious use, it seems stable and full-featured enough to meet the needs of many users.
14:42
Security updates for Tuesday [LWN.net]
Security updates have been issued by AlmaLinux (.NET 10.0, .NET 11.0, .NET 8.0, .NET 9.0, bind, bind9.18, buildah, c-ares, cjose, cockpit, cockpit-files, cockpit-machines, cockpit-podman, containernetworking-plugins, crun, delve, dhcp, dogtag-pki, dovecot, dpdk, edk2, emacs, environment-modules, expat, fetchmail, firefox, flatpak, flatpak-builder, freerdp, gcc, gcc-toolset-15-gcc, gcc-toolset-16-gcc, git-lfs, glib2, glibc, glycin-loaders, gnome-remote-desktop, go-fdo-client, go-fdo-server, grafana, grafana-pcp, gstreamer1, gstreamer1-plugins-bad-free, gstreamer1-plugins-base, guava, gvfs, gvisor-tap-vsock, ignition, iperf3, java-1.8.0-openjdk, jq, kernel, librabbitmq, libreswan, librsvg2, libsoup, libsoup3, libX11, libXi, libxml2, libXrender, libXtst, lrzsz, microcode_ctl, mingw-glib2, mod_auth_openidc, mod_http2, NetworkManager, nginx, nginx:1.24, nginx:1.26, nodejs:24, nodejs:26, oci-seccomp-bpf-hook, openexr, openssh, openssl, pcp, perl-DBI, perl-DBI:1.641, perl-URI, php:8.4, podman, polkit, postgresql:16, python-jwcrypto, python-oauthlib, python-tornado, python3, python3.12, python3.9, rpm, rsyslog, runc, rust-sequoia-sq, sos, squid, sssd, tesseract, tftp, tomcat, tomcat9, unbound, util-linux, webkit2gtk3, wireshark, xdg-dbus-proxy, xfsprogs, xorg-x11-server, xz, and yggdrasil), Debian (gnocchi, kernel, lightdm, roundcube, zaqar, and znc), Fedora (assimp, chromium, criu, freerdp, maturin, mysql8.4, perl-Catalyst-Plugin-Authentication, python-jiter, python-pymdown-extensions, python-pysequoia, qtox, ruff, rust-afterburn, rust-astral_async_zip, rust-clearscreen, rust-coreutils, rust-jiter, rust-lzma-rust2, rust-mailparse, rust-pyo3-introspection, rust-python-pkginfo, rust-sccache, rust-serde_json, rust-testresult, rust-zip, selenium-manager, tpm2-tss, ty, and xfsprogs), SUSE (apache2, azure-storage-azcopy, container-suseconnect, containerd, crane, dpdk, ghostscript, google-cloud-sap-agent, google-osconfig-agent, govulncheck-vulndb, graphifyy, hauler, helm, helm3, hivex, java-21-openjdk, java-25-openjdk, libevent-2_1-7, libmikmod-devel, libXi, mtools, nodejs24, open-iscsi, parted, podman, psqlODBC, python-M2Crypto, python-tornado6, python3, re2c, rsyslog, speex, thunderbird, valkey, vsftpd, and zbar), and Ubuntu (buildstream, cairosvg, commons-configuration2, deluge, dokuwiki, eterm, gnupg1, groovy, gst-plugins-bad1.0, gst-plugins-base1.0, h2o, htmldoc, net-snmp, netkit-rsh, node-moment, openjdk-25-crac, pdfresurrect, pillow, postsrsd, psensor, rlottie, sos, sosreport, vim-syntastic, yadifa, zbar, and zutils).
14:21
Good morning sports fans!
 If BonBon were made by a big company instead of by an aging
hippie software developer working with his super-powerful friend
Claude, we would have gone on a press tour, probably via Zoom, of
all the major pubs to prepare them for a fundamental change in what
we think of as the web. We would have produced a huge example site,
and worked with leading content publishers like the NYT, Kottke and
Heather Cox Richardson to get their work BonBon-ready. We
would have a developer conference where web devs and political
leaders would speak about the importance of writing on the web. I
would have contacted Tim Berners-Lee and asked him to write the
preface for the docs, telling about his vision now, over 30 years
since the inception of the web, and what he thinks of the future.
Then I would speak, and say enough of that, here's a demo, and then
I would give you the URL of the download page, and ask you to keep
an open mind to what's possible. If you do, imho, you will be
rewarded. But I won't be doing any of that. Instead I asked
ChatGPT
to explain BonBon from a historic perspective, based on a
conversation we had yesterday. And later today or tomorrow I will
link to the download site from my blog home page, and encourage you
to find out what having a new web Writer's Web might mean to
you. Till then, your friend, web writer and reader, Dave Winer.
;-)
Also -- I would have briefed Cory Doctorow as well, because imho BonBon strikes a blow for de-shitification which I hope becomes as much discussed as en-shitification.
I would have asked John Gruber, the inventor of Markdown, to give a talk. I'd give him a big hug and thank him for having such a great vision, so useful, so many years later.
13:49
Pluralistic: Remembrance of proteins past (17 Nov 2026) [Pluralistic: Daily links from Cory Doctorow]
->->->->->->->->->->->->->->->->->->->->->->->->->->->->->
Top Sources: None -->

Today's links
- Remembrance of proteins past: People like what they like.
- Hey look at this: Delights to delectate.
- Object permanence: BBC's bullshit DRM story; Radical hotel-room coffee independence; Foreclosure map predicts Trump vote; Pinkest pink v Anish Kapoor; Bruce Sterling on the Trump election; Keep the hope machine running; "Messy"; Jam To-Day; Billy Bragg x file-sharing; Second Life v copying; Best Buy claims copyright over prices; All cab conversations in Oxford must be recorded; The end of "software objectivity"; "Pirate Utopia"; Mamdani's photocopier-kicker; Biden does(n't) like SOPA; "The Freedom Maze"; Obama's weapons in Trump's hands; Gilmore/Barlow audio; MPAA v video iPods; RIP SF's neon Yahoo sign; NYC deputy mayor says no filming cops; Bannon wants to deport Indian CEOs; Academic economists charge $1k/h to defend giga-mergers; Iphones secretly spy on your calls; Office Depot fakes malware infections; Live Nation murdered at Astroworld; Games industry's self-induced brain injury.
- Upcoming appearances: Folkestone, Oxford, Sheffield, Virtual, Oxford, Santa Barbara, Montreal.
- Recent appearances: Where I've been.
- Latest books: You keep readin' em, I'll keep writin' 'em.
- Upcoming books: Like I said, I'll keep writin' 'em.
- Colophon: All the rest.

Remembrance of proteins past (permalink)
Without a doubt, the best piece of media from the 2026 midterms was Scott Colom's "Pick another senator instead" ad from his triumphant Mississippi senate campaign against GOP incumbent Cindy Hyde-Smith:
https://youtu.be/zpUnm09lTUk?si=3ApbHida5_VpQCLB&t=2219
Some background: Colom is the first Black Mississippi senator elected since Reconstruction gave way to Jim Crow. He's also the first Democratic Mississippi senator since 1982. Colom's campaign shifted the statewide vote leftward by 19 points, and he won a quarter of the state's white votes.
Colom ran a great campaign and promoted great policies, but also: he ran one of the great political ads of all time. That ad skewered Hyde-Smith's "let them eat whey powder" remark to WLOX Biloxi host Hugh Keeton, who asked her about the cost of living crisis and the high price of beef, to which she replied that people "have so many proteins to choose from":
Colom's ad plays a montage of Mississippians expressing disgust with Hyde-Smith's response, saying "I'd rather choose another senator instead." Colom was quick to credit content creator Ryan Sayles, who joined the campaign after doing some freelance work for them, as the ad's mastermind:
https://www.politico.com/news/2026/11/12/ryan-sayles-scott-colom-viral-protein-ad-01163508
Much has been said about the ad's style, especially the viral "s-h-e-e-e-i-t" voiced by US Army vet Russ Hudson, who stepped in to do the ad when his father declined to curse on camera:
https://edition.cnn.com/2026/11/15/politics/scott-colom-viral-protein-ad-mississippi-senate
But the most important analysis on the ad is of its substance, specifically how it repudiates one of the key doctrines of neoliberal, austerity economics, as David Dayen writes for The American Prospect:
https://prospect.org/2026/11/16/how-the-mississippi-senate-win-exposed-austerity-logic/
Neoliberalism is the signature achievement of the "law and economics" movement that came out of the University of Chicago. The central conceit of law and econ is that economics is a "hard science" (not a social science) and that its domain is a deterministic, quantifiable physics of human behavior. Economists went so far as to create a fake "Nobel Prize" in economics in a bid to elevate their work out of the social sciences:
https://pluralistic.net/2024/09/18/falsifiability/#figleaves-not-rubrics
This "science" claims it can replace squishy, qualitative questions with mathematical models that can output the objectively correct answer to every thorny political question, thereby substituting an obscure form of mathematics for political deliberation:
https://pluralistic.net/2023/04/03/all-models-are-wrong/#some-are-useful
This is a remarkably cheap and transparent stunt. To produce this "mathematics of human behavior," you must first quantize all the qualitative questions so that they can be plugged into variables in econ equations. But here's the problem: assigning a numeric value to a qualitative factor is a qualitative exercise!
When an economist decides that the pain you'll experience as a result of their policy prescriptions is worth "7" while the benefit is worth "8," they are not doing objective work, they're just declaring their own judgments (and biases) to be empirical observations, while demoting your judgments to mere "feelings" (and biases):
https://pluralistic.net/2024/09/18/falsifiability/#figleaves-not-rubrics
Economism doesn't just eliminate qualitative questions from policymaking: it incinerates all of those qualitative factors so that economists can perform mathematics on whatever dubious quantitative residue remains in the crucible:
https://locusmag.com/feature/cory-doctorow-qualia/
This is where Scott Colom's brilliant campaign ad comes in. As Dayen points out, when Hyde-Smith made her "many other proteins to choose from," gaffe, she was referencing a key piece of economic theory that has been thoroughly weaponized by the neoliberals: "substitution."
On its face, substitution is just the commonsense proposition that when prices for one good or service go up, some consumers will substitute another. When gas prices go up, more people ride the bus. When Instagram increases its ad-load, more people switch to Mastodon or Bluesky. When your ISP jacks up your price, you might switch to another carrier.
So far, so good. Indeed, one of the best things about digital products and services is how low digital "switching costs" (the cost you bear when switching from one service to another) can be. The lower the switching costs are, the easier it is to substitute one thing for another.
This means that, in a state of nature, tech bosses have to be careful about enshittifying their products, lest their users defect to a rival. This is why tech bosses have spent decades doing everything they can to jack up those "switching costs." They want to convert all their users into hostages:
https://www.eff.org/deeplinks/2021/08/facebooks-secret-war-switching-costs
Substitution is real and it makes sense. The problem comes when neoliberal economists use this idea in policy. In the early 2010s, Barack Obama proposed applying substitution to the American welfare system through something called "Chained CPI."
"CPI" stands for the "Consumer Price Index": this is a measurement of the cost of a "basket of goods" (a bunch of supposedly representative household items) that is used to make inflationary adjustments to a variety of payments. When the CPI goes up, so do social security, welfare and disability payments. Otherwise, inflation would continually reduce the living standards of everyone who receives these entitlements.
"Chained CPI" takes the CPI and applies substitution to it. Rather than asking whether hamburger just got more expensive, the economists who calculate CPI ask whether the cheapest protein at the grocery store got more expensive (because hamburger can be swapped out for another protein).
Chained CPI's intent and effect is to reduce payments to retirees, disabled people, and poor people. Chained CPI is always going to be lower than CPI, because chained CPI only rises when the cheapest "substitute" for one of the items in CPI's "basket of goods" gets more expensive. In effect, the "basket of goods" becomes a transdimensional basket, one that contains every substitute good that might have gone into the basket in all possible parallel universes. Economists get to universe-shop for the dimension where that basket has the lowest cost, and then we all have to live in their chosen universe.
Obama tried to adopt it 2013 as part of a "grand bargain" to reduce the deficit, but was thwarted by the Tea Party Caucus, who refused the grand bargain on the grounds that it contained an infinitesimal tax rise for the richest Americans:
But chained CPI is one of the most cherished ideas of neoliberal thinktanks, so it came back in 2017 for Trump's tax giveaway to the super-rich, whose costs were partially offset by using chained CPI to calculate tax brackets, the standard deduction, and the Earned Income Tax Credit:
https://newrepublic.com/article/145688/biggest-trojan-horse-republican-tax-plan
As Dayen writes, "[This created] a regressive tax increase by eroding deductions and credits and pushing people into higher tax brackets. The wealthy were unaffected by this since they were already in the highest tax bracket and itemized rather than using the standard deduction."
Which brings me back to Cindy Hyde-Smith's foot-in-mouth remarks about "so many proteins." Whether or not Hyde-Smith knew it, she was referencing this substitution/chained CPI doctrine when she told people that beef inflation didn't matter because other proteins were available. In doing so, she was performing economism's cheapest trick: pretending that her opinions are objective facts, while other people's opinions are just feelings.
As Dayen writes, "[W]ho decides whether the cheaper product they switch to is 'similar' to the one that’s become so expensive that the consumer must give it up?…The logic is, approximately: You're not doing as badly as you think, so pick another protein and quit your whining."
People do substitute one thing for another as a matter of economic necessity. But the idea that a "substitute" is an "equivalent" can only be accepted if you first buy into the economist's conceit that all qualitative matters can be safely incinerated, leaving the expert to do math on the quantitative ash.
In this conceit, if you can't afford hamburgers and end up substituting chicken or fish, then you've found a new protein and have lost no "welfare." If you think otherwise, then you are expressing an irrational preference (unlike economists, whose preference for having a Nobel prize of their own is so empirically correct that it could be detected by a Martian peering at Earth through a telescope).
It's not only Cindy Hyde-Smith who unconsciously metabolized the idea of substitution as "rationality"; it's the voters, too, who recognized in Hyde-Smith's remarks the arrogance of policy elites who've spent decades discounting their views as "feelings" while declaring their own views to be experimental validated facts. Not only do voters recognize this move: they hate it.
They know that elites are perfectly capable of expressing strong views about qualitative matters and moving heaven and Earth to achieve a life that fits with their aesthetics. They know that the same Ivy League economists who dismiss their preferences as "irrational" will revel for 4,000 pages' worth of Marcel Proust expounding on the spiritual, intangible reasons for choosing his favorite baked goods.
Economics is the study of why people do things, but somewhere along the way it became a club used to force people to do the things that powerful people prefer. The (alleged) "rationalism" of economism has worn out its welcome. You don't need an economics degree to understand why that "rationalism" is a cheap trick: after 50 years of neoliberalism, a Martian with a telescope could spot it.
Hey look at this (permalink)

- NYC Council passes ban on 'surveillance pricing' that relies on personal data https://gothamist.com/news/nyc-council-passes-ban-on-surveillance-pricing-that-relies-on-personal-data
-
The Top 3 “Essentially Progressive” Palantir Products https://www.necessaryfictions.blog/p/the-top-3-essentially-progressive
-
Introducing the Atmosphere Community Cooperative https://atmosphere.coop/updates/introducing-the-atmosphere-community-cooperative
-
Tech Companies Are Trying to Shift the Entire Concept of Privacy (Again) https://www.eff.org/deeplinks/2026/11/tech-companies-are-trying-shift-entire-concept-privacy-again
-
Twenty Minutes Into the Future: On Launching “Terminal Values” https://www.oblomovka.com/wp/2026/11/14/twenty-minutes-into-the-future-on-launching-terminal-values/

Object permanence (permalink)
#20yrsago Billy Bragg and manager: The Internet is for sharing files http://news.bbc.co.uk/2/hi/entertainment/6148654.stm
#20yrsago Second Life struggles with copying https://web.archive.org/web/20061209112340/http://nwn.blogs.com/nwn/2006/11/second_life_clo.html
#20yrsago BestBuy: our prices are copyrighted https://web.archive.org/web/20061114201037/https://arstechnica.com/news.ars/post/20061114-8218.html
#20yrsago Audio from Gilmore/Barlow talk at USC https://web.archive.org/web/20070202190231/http://centeronpublicdiplomacy.com/podcasts/061113_gilmore_barlow.mp3
#20yrsago Paramount/MPAA: it’s illegal to put DVDs on iPods https://web.archive.org/web/20061119111822/https://www.eff.org/deeplinks/archives/005010.php
#15yrsago OWS library is rebuilding after being trashed by NYPD, needs your donated books https://peopleslibrary.wordpress.com/contribute/
#15yrsago San Francisco’s iconic neon Yahoo! sign is coming down https://web.archive.org/web/20111118012241/https://www.thesfegotist.com/editorial/2011/november/16/end-era-yahoo-billboard-comes-down/
#15yrsago New Zealand Prime Minister sends police to raid major news outlets over covert recording of negotiations with far-right party https://www.rnz.co.nz/news/politics/91307/john-key-defends-resources-used-on-tape-investigation
#15yrsago NY Deputy Mayor: press don’t have the right to report in vicinity of NYPD ops https://web.archive.org/web/20111119001027/https://ny1.com/content/news_beats/inside_city_hall/150926/ny1-online–deputy-mayors-defend-zuccotti-park-raid
#15yrsago Sustainable Materials: indispensable, impartial popular engineering book on the future of our built and made world https://memex.craphound.com/2011/11/17/sustainable-materials-indispensable-impartial-popular-engineering-book-on-the-future-of-our-built-and-made-world/
#15yrsago Oxford city council: every cab must have a CCTV to record riders’ conversations https://www.bbc.com/news/uk-england-oxfordshire-15720998
#15yrsago Walmart smears worker-based chat app with lies and scare tactics https://web.archive.org/web/20161115190524/https://consumerist.com/2016/11/15/walmart-warns-workers-dont-download-chat-app-from-labor-organization/
#15yrsago Stolen government of Malaysia certificate used to sign malicious fake Adobe software update https://web.archive.org/web/20111116182552/https://www.f-secure.com/weblog/archives/00002269.html
#15yrsago Secret documents reveal the flimsy case for Ofcom to give into BBC’s public TV DRM demands https://web.archive.org/web/20140212005011/https://www.theguardian.com/technology/2011/nov/14/bbc-hd-drm
#15yrsago HOWTO attain radical hotel-room coffee independence https://memex.craphound.com/2011/11/14/howto-attain-radical-hotel-room-coffee-independence/
#15yrsago Chapel Hill sends SWAT team to arrest Occupy “anarchists” https://web.archive.org/web/20111114130328/https://www.newsobserver.com/2011/11/13/1641362/activists-take-over-vacant-franklin.html
#15yrsago Real cost of patent trolling https://web.archive.org/web/20111115134326/https://feld.com/wp/archives/2011/11/the-real-cost-of-patent-trolls.html
#15yrsago Joe Biden: SOPA is Un-American – but not when America does it https://www.techdirt.com/2011/11/15/vp-joe-biden-explains-why-sopa-protect-ip-are-anti-american-bad-idea/
#15yrsago OWS: NYPD occupy Zucotti Park, but what are their demands? http://occupywallst.org/article/nypd-occupying-liberty-square-demands-unclear/
#15yrsago The Freedom Maze: a different sort of slavery-time alternate history https://memex.craphound.com/2011/11/16/the-freedom-maze-a-different-sort-of-slavery-time-alternate-history/
#15yrsago Bundled, Buried & Behind Closed Doors: documentary on the net’s hidden physical infrastructure https://vimeo.com/30642376
#10yrsago Facebookers defy Zuckerberg, form fake news “task force” https://www.buzzfeednews.com/article/sheerafrenkel/renegade-facebook-employees-form-task-force-to-battle-fake-n#.jrDKxryP
#10yrsago Embarrassed New Yorkers force Trump Place to change name https://web.archive.org/web/20161115214232/https://www.bloomberg.com/news/articles/2016-11-15/manhattan-s-trump-place-to-change-name-use-street-addresses
#10yrsago Here are the devastating capabilities of the weapons Obama will leave behind for Trump https://www.nytimes.com/2016/11/14/us/politics/harsher-security-tactics-obama-left-door-ajar-and-donald-trump-is-knocking.html
#10yrsago US foreclosure map predicts US battleground states map https://mathbabe.org/2016/11/14/guest-post-the-foreclosure-vote/
#10yrsago Anish Kapoor banned from using world’s pinkest pink in retaliation for hoarding the blackest black https://web.archive.org/web/20161112235050/https://thecreatorsproject.vice.com/blog/the-worlds-pinkest-paint
#10yrsago Remember when they told us Hillary, not Bernie, would beat Trump? https://fair.org/home/polls-showed-sanders-had-a-better-shot-of-beating-trump-but-pundits-told-you-to-ignore-them/
#10yrsago Bruce Sterling on the US election: the net is great at tearing down, terrible at building https://www.textezurkunst.de/en/articles/bruce-sterling-us-election/
#10yrsago Canadian tech firms will have their pick of overseas talent thanks to Trump’s anti-immigrant policies https://web.archive.org/web/20161119143446/https://motherboard.vice.com/read/trump-election-science-tech
#10yrsago Keep hoping machine running: Woody Guthrie’s New Years resolutions, 1943 https://www.openculture.com/2026/01/woody-guthrie-creates-a-doodle-filled-list-of-33-new-years-resolutions-1943.html
#10yrsago Messy: a celebration of improvisation and disorder as the keys to creativity, play, and work https://memex.craphound.com/2016/11/14/messy-a-celebration-of-improvisation-and-disorder-as-the-keys-to-creativity-play-and-work/
#10yrsago The free-speech activist duty of journalists during the coming Trump years https://dangillmor.com/2016/11/13/trump-free-speech-and-why-journalists-must-be-activists/
#10yrsago John Oliver: how to resist the normalization of Trump https://www.youtube.com/watch?v=-rSDUsMwakI
#10yrsago Superstar academic economists charge $1000+/hr to defend disastrous corporate megamergers https://www.propublica.org/article/these-professors-make-more-than-thousand-bucks-hour-peddling-mega-mergers
#10yrsago Steve Bannon wants to deport Asian-born tech CEOs to preserve “civil society” https://www.theverge.com/2016/11/16/13653490/steve-bannon-trump-presidency-chief-strategist-breitbart-tech-visa
#10yrsago Iphones secretly send your call history to Apple’s cloud, even after you tell them not to https://web.archive.org/web/20161117135915/https://theintercept.com/2016/11/17/iphones-secretly-send-call-history-to-apple-security-firm-says/
#10yrsago Office Depot techs accused of faking malware infections to meet sales targets https://web.archive.org/web/20161117150900/https://consumerist.com/2016/11/16/office-depot-allegedly-diagnosing-computers-with-nonexistent-viruses-to-meet-sales-goals/
#5yrsago Live Nation is to blame for the Astroworld deaths https://pluralistic.net/2021/11/17/do-well-do-good-do-nothing/#crushing
#5yrsago Aspiration's comprehensively deceptive greenwashing https://pluralistic.net/2021/11/17/do-well-do-good-do-nothing/#greenwashing
#1yrago The games industry's self-induced traumatic brain injury https://pluralistic.net/2025/11/17/stop-killing-games-again/#object-transience
Upcoming appearances (permalink)

- Folkestone Writers Festival, Nov 16
https://www.creativefolkestone.org.uk/whats-on/cory-doctorow-the-internet-is-broken-now-what/ -
Oxford: Ministry of the Future, Nov 23
https://ministryforthefuture.co.uk/events.html -
Sheffield: Reverse Centaur at Juno Books, Nov 25
https://www.outsavvy.com/event/40274/cory-doctorow-in-conversation -
Virtual: Enshittification, AI, and the Future of Technology (UBC Master of Educational Technology), Nov 28
https://met.ubc.ca/2026/09/met-speaker-series-cory-doctorow-enshittification-ai-and-the-future-of-technology/ -
Oxford: Bennett Oxford Symposium on Open Code in Science, Dec 9
https://www.bennett.ox.ac.uk/events/2026-bennett-institute-symposium/ -
Santa Barbara: UCSB Reads, Apr 29
https://www.library.ucsb.edu/events-exhibitions/ucsb-reads-2027-presents-author-cory-doctorow -
Montreal: World Science Fiction Convention, Sep 2-6
https://montreal2027.ca/en

Recent appearances (permalink)
- Clint Eastwood (No Gods No Mayors)
https://www.patreon.com/NoGodsNoMayors/posts/clint-eastwood-173008088 -
Life After AI (Brain Bar)
https://www.youtube.com/watch?v=IPPa43-n0vI -
Terms of Service with Clare Duffy (CNN)
https://www.cnn.com/audio/podcasts/terms-of-service-with-clare-duffy/episodes/458ce968-af5d-11f0-b539-13ed2afe25f8 -
AI, Work, and Power (Software Engineering Daily)
AI, Work, and Power https://softwareengineeringdaily.com/podcasts/cory-doctorow-on-ai-work-and-power/ -
AI, Corporate Power, and the Fight for Worker Control (Plutopia)
https://plutopia.io/cory-doctorow-ai-corporate-power-and-the-fight-for-worker-control/

Latest books (permalink)
- "The Reverse-Centaur's Guide to AI," a short book about being a
better AI critic, Farrar, Straus and Giroux, June 2026
https://us.macmillan.com/books/9780374621568/thereversecentaursguidetolifeafterai/ -
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
-
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/ -
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
-
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
-
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
-
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
-
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
-
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com

Upcoming books (permalink)
- "The Post-American Internet," a geopolitical sequel of sorts to Enshittification, Farrar, Straus and Giroux, 2027
-
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
-
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
-
"The Memex Method," Farrar, Straus, Giroux, 2027

Colophon (permalink)
Today's top sources:
Currently writing:
- “Once Is Enemy Action,” a science fiction novel
about the origins of modern technofascism. Today's words: 514
(37130 total).
-
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
-
A Little Brother short story about DIY insulin PLANNING

This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
How to get Pluralistic:
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X
13:35
 Okay I may have buried the lede a bit, but Big
Grey is actually from a colony of cats. Down the street from me is
a colony of about fifteen cats, maybe more, including three kittens
and a pregnant long haired pastel calico. I didn’t know this
colony existed until last week, and since then I have not stopped
thinking about how I am going to save this colony. Because I
will.
Big Grey was only the first of many cats I plan on rescuing, and he was first because as you have seen, he was in the worst shape I’ve ever seen a cat be in. Even though kittens would usually take priority in these kinds of situations, the kittens were extremely hard to get to (hiding under a trailer in someone’s backyard), and Grey was just so much sadder looking.
So, with Grey in recovery and safe in my basement sulking, I headed back out to catch more cats. It’s only thanks to a woman in town (who does TNR missions regularly) lending me traps and support that we managed to catch three cats yesterday. I caught the two most friendly and sociable in the whole colony, the sweetest of the sweet ones, and she caught a very skittish calico.
Later that night, she came back by herself and caught the three kittens and the pregnant cat in one go. I applaud her, honestly. I’ve never seen someone make such quick work of catching kittens. It always takes me a bit longer, anyways.
With my two catches in tow, I took them both into the urgent care vet that I took Grey to, and thankfully they are in much better shape! Though that was a low bar to clear. Fleas and ear infections, a bit of upper respiratory infection, but otherwise okay. And FeLV, FIV, and heartworm negative. They’re a little less than a year old, and very bonded.
The lady got an appointment for the pregnant one to get taken care of and fixed, and has all of them in her possession right now, thank goodness.
So, I have three, she caught two plus the three kittens, and there’s still like a dozen left.
While TNR is obviously the most important step in dealing with any rampantly breeding colony, I want to do so much more than that for them. I want them healthy, happy, and to find homes for as many as I can after getting them vetted, vaccinated, and fixed. I want to adopt out every single one I possibly can, and I honestly think it’s doable!
I also want to be transparent about this entire process and the money, time, and commitment it takes to doing it. I’m not a pro or that experienced, but how do experienced people get experienced? They try. And with y’all as my witness, I’m going to try.
Now, let’s get into the real reason you’re here, cat photos of the colony cats. This is not all of them, just a few I managed to snap pics of.
First up is the pregnant one, who I lovingly call Fluffy Sugar:

Some of you might be able to tell why I call her that.

Look at that mlem!
When I first saw Fluffy Sugar, I couldn’t believe such a beautiful cat was on the streets. She looks like she belongs curled up in a comfy bed next to a fireplace, not wandering out of the bushes with goopy eyes in forty degree weather. I actually want her very badly. Thankfully this is the one in custody who is getting fixed up.
I call this one Fats:

CHONKY!
One of many calicos in the colony:

This one has very striking eyes:

This guy doesn’t look too bad, but he has some weirdly thin patches of fur that show pink skin underneath:

He’s very skittish and I scared him when I took this photo:

Oh boy! Another orange cat:

Oh my gosh, another orange cat!

I love this one, long haired cats are just so cute.
This one stared me down:

An even dingier looking grey and white one:

Here is one of the three kittens:

And finally, my two extremely sweet lovable ones that are in my custody currently:

This is Kevin.

And this is Tiffany.
Though I dubbed Fluffy Sugar and Fats with their names, the neighbor lady to the colony house is the one that gave Kevin and Tiffany their names. I plan to rename them or assume whoever takes them will rename them something more.. suited to their personalities.
THREE cats in this photo have already been caught! That is such good progress for only a couple days! At least, I think so.

I am running through litter and wet food like crazy, so I definitely placed some bulk orders of stuff. I am trying hard to stay on top of things, but dang there’s a lot of cats to herd (ha!).
I am racing against the clock with this cold weather. I just bought insulated outdoor shelters to put around the colony. Hopefully they offer respite while I continue my mission to help each and every one of them.
I wish I could’ve gotten a picture of the one I call Batman. If you saw him you’d understand why I call him that. Plus, I usually see him on the roof. But, like I said, there’s more than I’ve even photographed. Every time I think I’ve seen them all, another one comes out. So many to keep track of.
For anyone who has asked about microchips, every single cat I take to the vet gets scanned at the beginning of the appointment for one! So far, no chips.
So, what do you think? Am I being too optimistic about each one of these guys becoming a loving household cat? Which one looks like the one you’d claim if you could? Should I pick up extra shifts at the factory to afford this endeavor (because dang there are cheaper hobbies to pick up than this)?
Let me know in the comments, and have a great day!
-AMS
13:00
CodeSOD: Building a Line [The Daily WTF]
There's an unofficial category of posts here that I call "Somebody told us string builders were more efficient, so we always use string builders, regardless of whether or not that actually makes sense," or STUSBWMESWAUSBROWONTAMS, for short. Probably should workshop that name some.
In any case, Adam sends us a new entry for that collection:
 Public Function ReadFromFile(ByVal filename As String) As String

    Dim sb As StringBuilder = New StringBuilder()
    Dim str As String = String.Empty

    Using sr As StreamReader = File.OpenText(filename)
        str = sr.ReadToEnd()
        sb.Append(str & Constants.vbLf)
    End Using

    Return sb.ToString()

End Function
This function takes a filename, opens a file, reads the entire
contents of the file to a variable. It concatenates a line feed to
the end of the string it just read, then appends all of
that to a string builder. Finally, we return
sb.ToString(), taking the single string in the string
builder, appending nothing to it, and returning the result.
I'd almost, almost forgive the code if it was more like:
        str = sr.ReadToEnd()
        sb.Append(str)
        sb.Append(Constants.vbLf)
You're not actually gaining much from this, but it follows the
broad pattern of "use a string builder" so that if you ever wanted
to change the structure of the output, you're already set up to
prepend/append new text in a scalable way. I'd argue that's
premature abstraction, though: a simple return sr.ReadToEnd()
& Constants.vbLf would do the current job.
The code that we have is a clear superstitious use of string builders. The string builder is used as a charm against poor performance, without understanding why one might use it, or how it might work; string concatenation means string builder, always and forever, "why" doesn't enter into it.
 [Advertisement] Keep all your packages and Docker containers in one
place, scan for vulnerabilities, and control who can access
different feeds. ProGet installs in minutes and has a powerful free
version with a lot of great features that you can upgrade when
ready.Learn
more.
12:49
When AI-Generated Data Becomes Tomorrow’s Ground Truth [Radar]
Manufacturers qualify suppliers before trusting them with critical work. Before a supplier can provide parts for a regulated product such as a medical device, the manufacturer collects evidence: quality certifications, test reports, insurance documents, and regulatory approvals. Increasingly, an AI agent reads that evidence first. The agent reviews the documents and proposes a finding, and a business process decides whether the finding is good enough for the supplier to be accepted. Once a supplier is accepted, that decision is recorded in the manufacturer’s supplier-management system. From there, sourcing workflows, readiness dashboards, and program reports all rely on that record without repeating the review.
Here is how that process can go wrong. A supplier-review agent examines a new supplier’s documents and concludes that a mandatory quality certificate is valid. The qualification workflow accepts the finding, the supplier is recorded as compliant, and the procurement lead approves the supplier for an upcoming order. A few days later, a human reviewer notices that the certificate does not cover the part being sourced; the agent had misread the certificate’s scope. At 11:00am, the reviewer corrects the supplier record and sends the supplier back for review. At 2:00pm, the readiness dashboard still shows the supplier as cleared, and a program report still lists the supplier as compliant. The procurement lead’s sourcing decision remains in force, and nothing tells the procurement lead that the evidence behind it has changed.
A misread scope is only one way a certificate finding can fail. A certificate may be revoked after it was checked, expire before the order ships, apply to a different plant than the one making the part, or turn out to be forged. In each case, someone can correct the supplier record while the systems that already used the old finding keep acting on it.
No system in this example malfunctioned. Each one processed information that appeared valid under its local contract, yet the combined result was wrong. The manufacturer had corrected a value without correcting its influence. Part of this is a familiar problem: Enterprise systems have always struggled to keep reports, indexes, caches, and workflow state in line with the source record. Agents make the problem harder because they generate conclusions. A conclusion can be assembled from several sources, rewritten in reports, and retrieved later as if it were independent evidence. Reconciliation can make stored values agree. It cannot reveal that differently worded records come from the same conclusion, or find the decisions that already relied on that conclusion.
This problem is not limited to manufacturing. In our work across banking, telecommunications, and resources, it appears wherever an agent’s output becomes a record that other systems trust. A fraud classification is written into a case record. A risk assessment is summarized in a management report. An incident diagnosis becomes part of a knowledge base. In each of these cases, as in the supplier example, the conclusion loses some of its original context at every step it passes through and begins to influence decisions made later.
The conclusion can also travel back into model development. Accepted findings become labeled examples, evaluation sets, and fine-tuning data, where they are treated as ground truth for the next model. If an incorrect supplier finding survives correction in the operational systems, a future model may learn it. Whether the conclusion ends up in a dashboard, a report, or a training set, the hard problem is the same: finding every consequential decision that depends on a result that can change.
When an answer acquires authority
Look again at the supplier-review agent’s conclusion that the certificate is valid. When the agent produces that conclusion, it is a generated assertion: a claim made by a model, with no business authority until the qualification workflow accepts it for a specific use, such as approving the supplier for sourcing. The words “certificate valid” also change character as they move. In the agent’s response, they are visibly part of an AI-assisted assessment. In the supplier master record, the same words look like an established fact. The dashboard strips away more context: It shows the supplier as cleared, with no sign of which checks were incomplete or whether a review was pending. The program report compresses the finding into a sentence, and the search index splits that sentence into passages that can be retrieved on their own.
Along the way, enterprise systems tend to keep the value the agent produced and lose the conditions under which it was produced. A label saying that the finding was AI-generated may survive on the supplier record and disappear from a dashboard total, a data export, or a retrieval chunk. As that context falls away, the conclusion takes on the authority of whichever system is carrying it.
That is why two questions need to be kept separate: Who produced a result? And who is allowed to rely on it? An agent may be allowed to record a proposed finding without being allowed to establish a business fact. The same finding may be good enough to move a supplier up a review queue and not good enough to approve the supplier or release a payment. Where that line falls depends on what is at stake and which controls grant authority for that use. Once the qualification workflow accepts a finding, downstream systems usually treat it as settled and do not repeat the checks. That is efficient, and it creates an obligation: Those systems still need to know which decisions rely on the finding and under what conditions.
When repetition looks like corroboration
Acceptance also multiplies the finding. Once the supplier is recorded as compliant, the readiness dashboard shows the supplier as cleared, the sourcing workflow moves forward, and the program report repeats the approval. A later agent, when asked about the supplier, can retrieve the supplier record and the program report as two separate documents, each appearing to support the same conclusion. Across the supplier record, the program report, and the dashboard, one says the evidence was verified, another says the controls passed, and a third shows an approved outcome. What appears to be corroboration is propagation: several records repeating one finding. Because each system changes the wording or format, the duplication is easy to miss.
A stronger model will not reliably catch this duplication when the retrieval system presents the copies as unrelated documents. Reranking improves relevance, but every copy may be relevant. Telling the model to look for independent evidence cannot restore ancestry that was discarded before the documents reached it. Agent memory makes the problem worse. An agent that records its own finding and retrieves it a week later is citing itself, and nothing in the retrieved passage says so. In multi-agent workflows, one agent’s summary becomes another agent’s context, and a third agent’s supposedly independent check may read both.
Decision lineage is the missing recovery path
Existing tools cover parts of this problem. W3C PROV models the entities, activities, and agents involved in producing data, establishing origin and responsibility.[1] OpenLineage standardizes lineage metadata around datasets, jobs, and runs.[2] Event sourcing records changes to application state as a sequence of events.[3] PROV is expressive enough to model the whole supplier example. The gap is in implementation. Lineage tooling often stops at dataset and job boundaries and rarely reaches the decision record or the retrieval layer that assembles an agent’s context. As usually deployed, none of these tools answers the question that matters after the certificate finding changes: Which decisions still depend on it? Decision lineage extends these mechanisms. It records the relationship between the source evidence, the generated assertion, the authority granted to that assertion, and the decisions that rely on it.
Data lineage tells us where an assertion traveled. Decision lineage tells us what the organization did because it believed the assertion.
In the supplier example, the chain runs from the certificate to the agent’s finding to the accepted supplier record to the procurement lead’s sourcing decision and on to the dashboard, report, and search index that reuse the finding. If the certificate turns out to be invalid, that chain lets the system find the sourcing decision and identify every report, workflow, and AI output that inherited the old finding, before any of them influence another decision.
The chain also marks where automated recovery and business accountability separate. Software can identify the affected artifacts, stop the withdrawn finding from appearing as current evidence, and open a review task for the person who owns the decision. That person decides whether the decision still stands, needs to be reversed, or needs to be communicated to customers or regulators. An implementation might remove stale search entries automatically while still requiring human approval to change a sourcing decision that has already been made.
A production pattern for preserving decision dependence
The pattern starts where the agent’s output enters the system of record. The agent records its finding as a proposal, tied to the evidence it reviewed. A deterministic workflow, owned by the business, decides whether that proposal gains authority for a defined use. If a required check cannot run, the finding stays a proposal and is never silently promoted. Keeping proposals separate from accepted findings prevents accidental promotion, but it does not record what happens next, when the sourcing decision relies on the accepted finding. The decision needs a link back to that finding and to the version of the evidence behind it. This does not require a universal graph of everything the agent touched. For a high-consequence decision, it is enough that the finding’s influence can still be traced after the workflow has finished.
The dependency record that holds this link can be small. For the supplier example, it might look like this:
{
  "assertion_id": "asr-7781",
  "claim": "Mandatory certificate valid for supplier S-204",
  "evidence_snapshot": "evd-2291@v3",
  "authority": {
    "granted_by": "qualification-workflow",
    "scope": ["sourcing-approval"]
  },
  "dependent_decisions": ["sourcing-5520"],
  "derived_artifacts": ["dashboard:readiness",
                        "report:program-q3",
                        "index:supplier-docs"],
  "status": "accepted"
}
When the certificate finding is
withdrawn, the record’s status changes to withdrawn, and the
dependent_decisions and derived_artifacts
fields become the list of everything that needs to be
revisited.
The dependency record has to survive as the finding is copied downstream, because the same finding may come back through the program report or the search index. When a later agent retrieves both the supplier record and the program report, the retrieval layer should recognize that they share an origin and present them as two copies of one finding. If the finding has been withdrawn, the retrieval layer should filter or flag both copies before they reach the agent.
When a finding turns out to be wrong it is withdrawn, and the supplier goes back to review. The dependency record lets services find the decisions that relied on the finding, recompute dashboards, flag reports for regeneration, remove stale search results, and stop pending workflows. Decisions that have already taken effect go back to their owners, and nothing is reversed automatically. Cache invalidation, vector-index refresh, report regeneration, and workflow reversal are all parts of the same recovery job. A correction has traveled far enough only when the old finding no longer drives any current decision.
Where the pattern is worth the cost
Not every AI output needs decision lineage. An answer that is low-stakes, never stored, never reused as evidence, and cheap to regenerate can live with ordinary logging. Decision lineage earns its cost once an AI-generated finding can affect an approval, a payment, safety, compliance, or later machine decisions. By the time an error in such a finding is discovered, the finding may already have changed what the organization did, so recovery has to finish within the time the business process can tolerate. That recovery work, finding and reconsidering the decisions affected when evidence changes, is what the pattern makes cheaper.
The pattern also does not require tracking every word an agent produces. The unit to track is the material assertion: a specific claim, such as “the certificate is valid,” that could change a decision if it were wrong. A long supplier assessment may contain only one or two material assertions. Recording dependencies for those claims is more useful than keeping a complete trace of everything the agent wrote, and it costs less in storage, privacy exposure, and operations.
Tracking ancestry also has to be precise enough to keep independent evidence independent. If two laboratories separately validate the same certificate, the system should not merge their results into a single source just because they agree. What matters is whether the observations share an origin, and similar wording proves nothing either way.
How to test whether correction traveled far enough
Recording dependencies proves little unless a correction actually travels through them, so the pattern needs a test. In a controlled environment, introduce an incorrect finding, let it reach a report and a search index, and then withdraw it. The test passes only if the affected decision can be found, and the stale copies stop appearing as evidence within the recovery time the process requires.
Three indicators show how well the test went. Decision coverage is the share of high-consequence decisions that can be traced back to a supporting finding. Time to impact is the time between withdrawing a finding and identifying the decisions it affected. Stale-evidence leakage counts the withdrawn copies still returned as current evidence. Targets depend on the process. A payment approval might need affected decisions identified within the hour, with zero leakage, while a review-queue priority may tolerate a day.
Replay the supplier decision
Now return to the supplier example and run it again with the pattern in place. When the supplier-review agent concludes that the certificate is valid, its finding is recorded as a proposal tied to the documents it reviewed. The qualification workflow checks the finding, grants it authority for the sourcing decision, and writes the dependency record shown earlier. The dashboard and program report still pick up the accepted finding, and a later agent that retrieves both sees them as two copies of one finding.
When the reviewer corrects the record at 11:00am, the finding is withdrawn and the supplier goes back to review. This time the correction travels. The dashboard recomputes, the program report is flagged for regeneration, stale entries drop out of the search index, and the procurement lead gets a task to review the sourcing decision. By 2:00pm, the dashboard shows the supplier as under review.
The procurement lead can now see that the certificate finding changed, which decision relied on it, and which reports and records carried it. The original mistake still happened. Its spread is now visible, and its consequences go back to someone who can act on them.
Ground truth begins with the next decision
In the supplier example, the procurement lead never treated the model’s response as final. The finding became organizational truth because the supplier system accepted it, the workflow advanced, the report repeated it, and later systems inherited its authority.
Decision lineage does not prove that the original evidence is authentic, replace data-quality or entitlement controls, or make a model’s conclusions accurate. It addresses what happens after a finding exists: how its influence is recorded, found, and reconsidered across the decisions that depend on it. For the manufacturer, correcting the certificate record was only the first step. Recovery also meant finding the sourcing decision that relied on the finding and stopping stale copies from coming back as current evidence.
AI-generated data becomes ground truth the moment the next decision stops asking where it came from.
References
- World Wide Web Consortium, “PROV-Overview: An Overview of the PROV Family of Documents,” April 30, 2013. View the W3C PROV overview.
- OpenLineage, “An Open Framework for Data Lineage Collection and Analysis.” View the OpenLineage documentation.
- Martin Fowler, “Event Sourcing,” December 12, 2005. Read “Event Sourcing.”
12:21
Formal Verification of the Signal Protocol Using AI [Schneier on Security]
This seems like a good thing:
Google Deepmind researchers used agentic AI to mathematically prove, or “formally verify,” a number of the Signal protocol’s key cryptographic guaranteesa landmark development for the widely used cryptography and AI itself.
Conducted as a sort of proof-of-concept project in just four weeks, the work is significant in two ways. It serves as further independent validation of the cryptography that protects massive quantities of the world’s communications on platforms like the Signal app, Google Messages, and WhatsApp. And it demonstrates Google DeepMind’s formal verification capabilities using a new AI framework called AlphaProof Code.
[…]
The DeepMind analysis did not find any new vulnerabilities in the portions of the Signal protocol it looked at, but when the researchers used AlphaProof Code on older versions of Signal that contain known and long-fixed vulnerabilities, it correctly identified them and showed that the protocol could not be formally verified. The researchers are releasing the specification and proof they developed for the Signal protocol analysis to aid other formal verification work.
Alternate link.
First, our researchers collaborated with a mix of models to translate Signal’s security goals into formal mathematical specifications, with human experts reviewing every one. From there, agents powered by Gemini Carbon did the proofs, generating over six million lines of Lean, a computer language that mathematically proves the accuracy of code.
Next, the agents audited the proof and highlighted areas that needed a second look by a human just one percent of the codebase, a massive time savings. Because Lean automatically checks the rest, our experts could focus their review where human judgment matters most.
Technical paper.
11:42
European Commission Plan to Give Frontex Trusted Flagger Status Is A Threat to Free Speech [Deeplinks]
EFF and 27 other human rights organizations
called on the European Commission today to
retract a dangerous proposal granting its border agency Frontex
power to request that national authorities issue takedown orders
for social media content and giving Frontext “trusted
flagger” status under the Digital Services Act (DSA), the EU
regulation governing online platforms and content moderation in the
region.
The extraordinarily improper proposal not only disregards the
provisions of the DSA but also places a mechanism of enforcement
overreach in the hands of a law enforcement agency that has
failed to safeguard people against serious
human rights violations at EU borders.
Under the
proposal, Frontex has the power to
“monitor publicly accessible social media content, detect
developments relevant to external border management, and support
action against illegal online content linked to border-security
risks.” Granting Frontex trusted flagger privileges on top of
its existing mandate risks creating a powerful tool for
over-enforcement, stifling the free expression of migrants, asylum
seekers, and other marginalized groups. We warned the Commission of
these risks in a
letter.
The DSA is supposed to make online platforms more accountable and
protect users’ fundamental rights, not give the EU power to
sic its border police on people for exercising their right to free
expression.
EFF and other rights organizations have for years
sounded alarms about potential abuse under
the DSA’s trusted flagger provision, which gives
“Digital Services Coordinators” the ability to award
entities—including law enforcement agencies—a
privileged channel to alert online platforms about illegal content.
We’ve taken the firm position that law enforcement cannot be
trusted to properly flag illegal content. In July, we
told the Commission that giving law
enforcement trusted flagger status could undermine fundamental
rights and said that police agencies like Frontex should not be
made trusted flaggers.
The EU proposal gives Frontex decision-making power over free
expression that is not envisaged under the DSA. First, content
removal orders can only be issued by relevant national authorities.
The DSA does not foresee a role for entities like Frontex to
request such orders. Second,
trusted flaggers notify platforms of suspected illegal
content—platforms must prioritize these notices and they have
sole responsibility to decide to remove content. It’s not
flaggers’ role to request removal orders from national
authorities. Combining these powers blur enforcement and flagging
functions, which the Commission’s own
draft guidelines on trusted flaggers
explicitly caution against.
“The risk of Frontex utilizing its power as both a Trusted
Flagger and authority that can demand removal orders, to surveil
user-generated speech, and over-flag content under the guise
of ‘border security risk’ is clear. This will
likely result in platforms over-censoring content and chilling the
speech of already marginalized groups, particularly those from
migrant and asylum-seeking communities,” the letter
says.
We urge the Commission to rescind the proposal. It undermines the
DSA, threatens fundamental rights of citizens and non-citizens, and
is enforcement overreach that does not align with international
human rights standards.
10:35
Selling to friends [Seth's Blog]
There are two versions, very different:
FAVOR: This is what multi-level marketing preys on. You ask a family member or a friend to buy something, not because they need it, but because you do.
This doesn’t always end well. Someone might want to further their relationship with you by doing you this favor, but if the unspoken promise is that the item or service is worthwhile, the disappointment that ensues hurts everyone. Real estate brokers or middlemen in a bind often seek to build friendly relationships at the club or community meetings, but then try to leverage this friendship into a significant sale without doing the hard work of actually being the best choice.
TRUST: This is the sort of sale that happens when you begin with the benefit of the doubt but actually deliver a great outcome. You’ll know this is the case when the person who trusted you ends up testifying on your behalf to others.
“No pressure” is something that’s showing up more and more in the pitches I’m seeing. Of course, there’s no pressure! Just saying it implies that you wish there were.
If you’re asking for a favor, you’re not serving and you’re not selling. You’re trading.
And if you’re asking for trust, be prepared to honor the obligation it creates.
08:35
Sex Drive Differences by Tessa Luicart [Oh Joy Sex Toy]
06:42
Better Board Games in Bars – DORK TOWER 17.11.26 [Dork Tower]
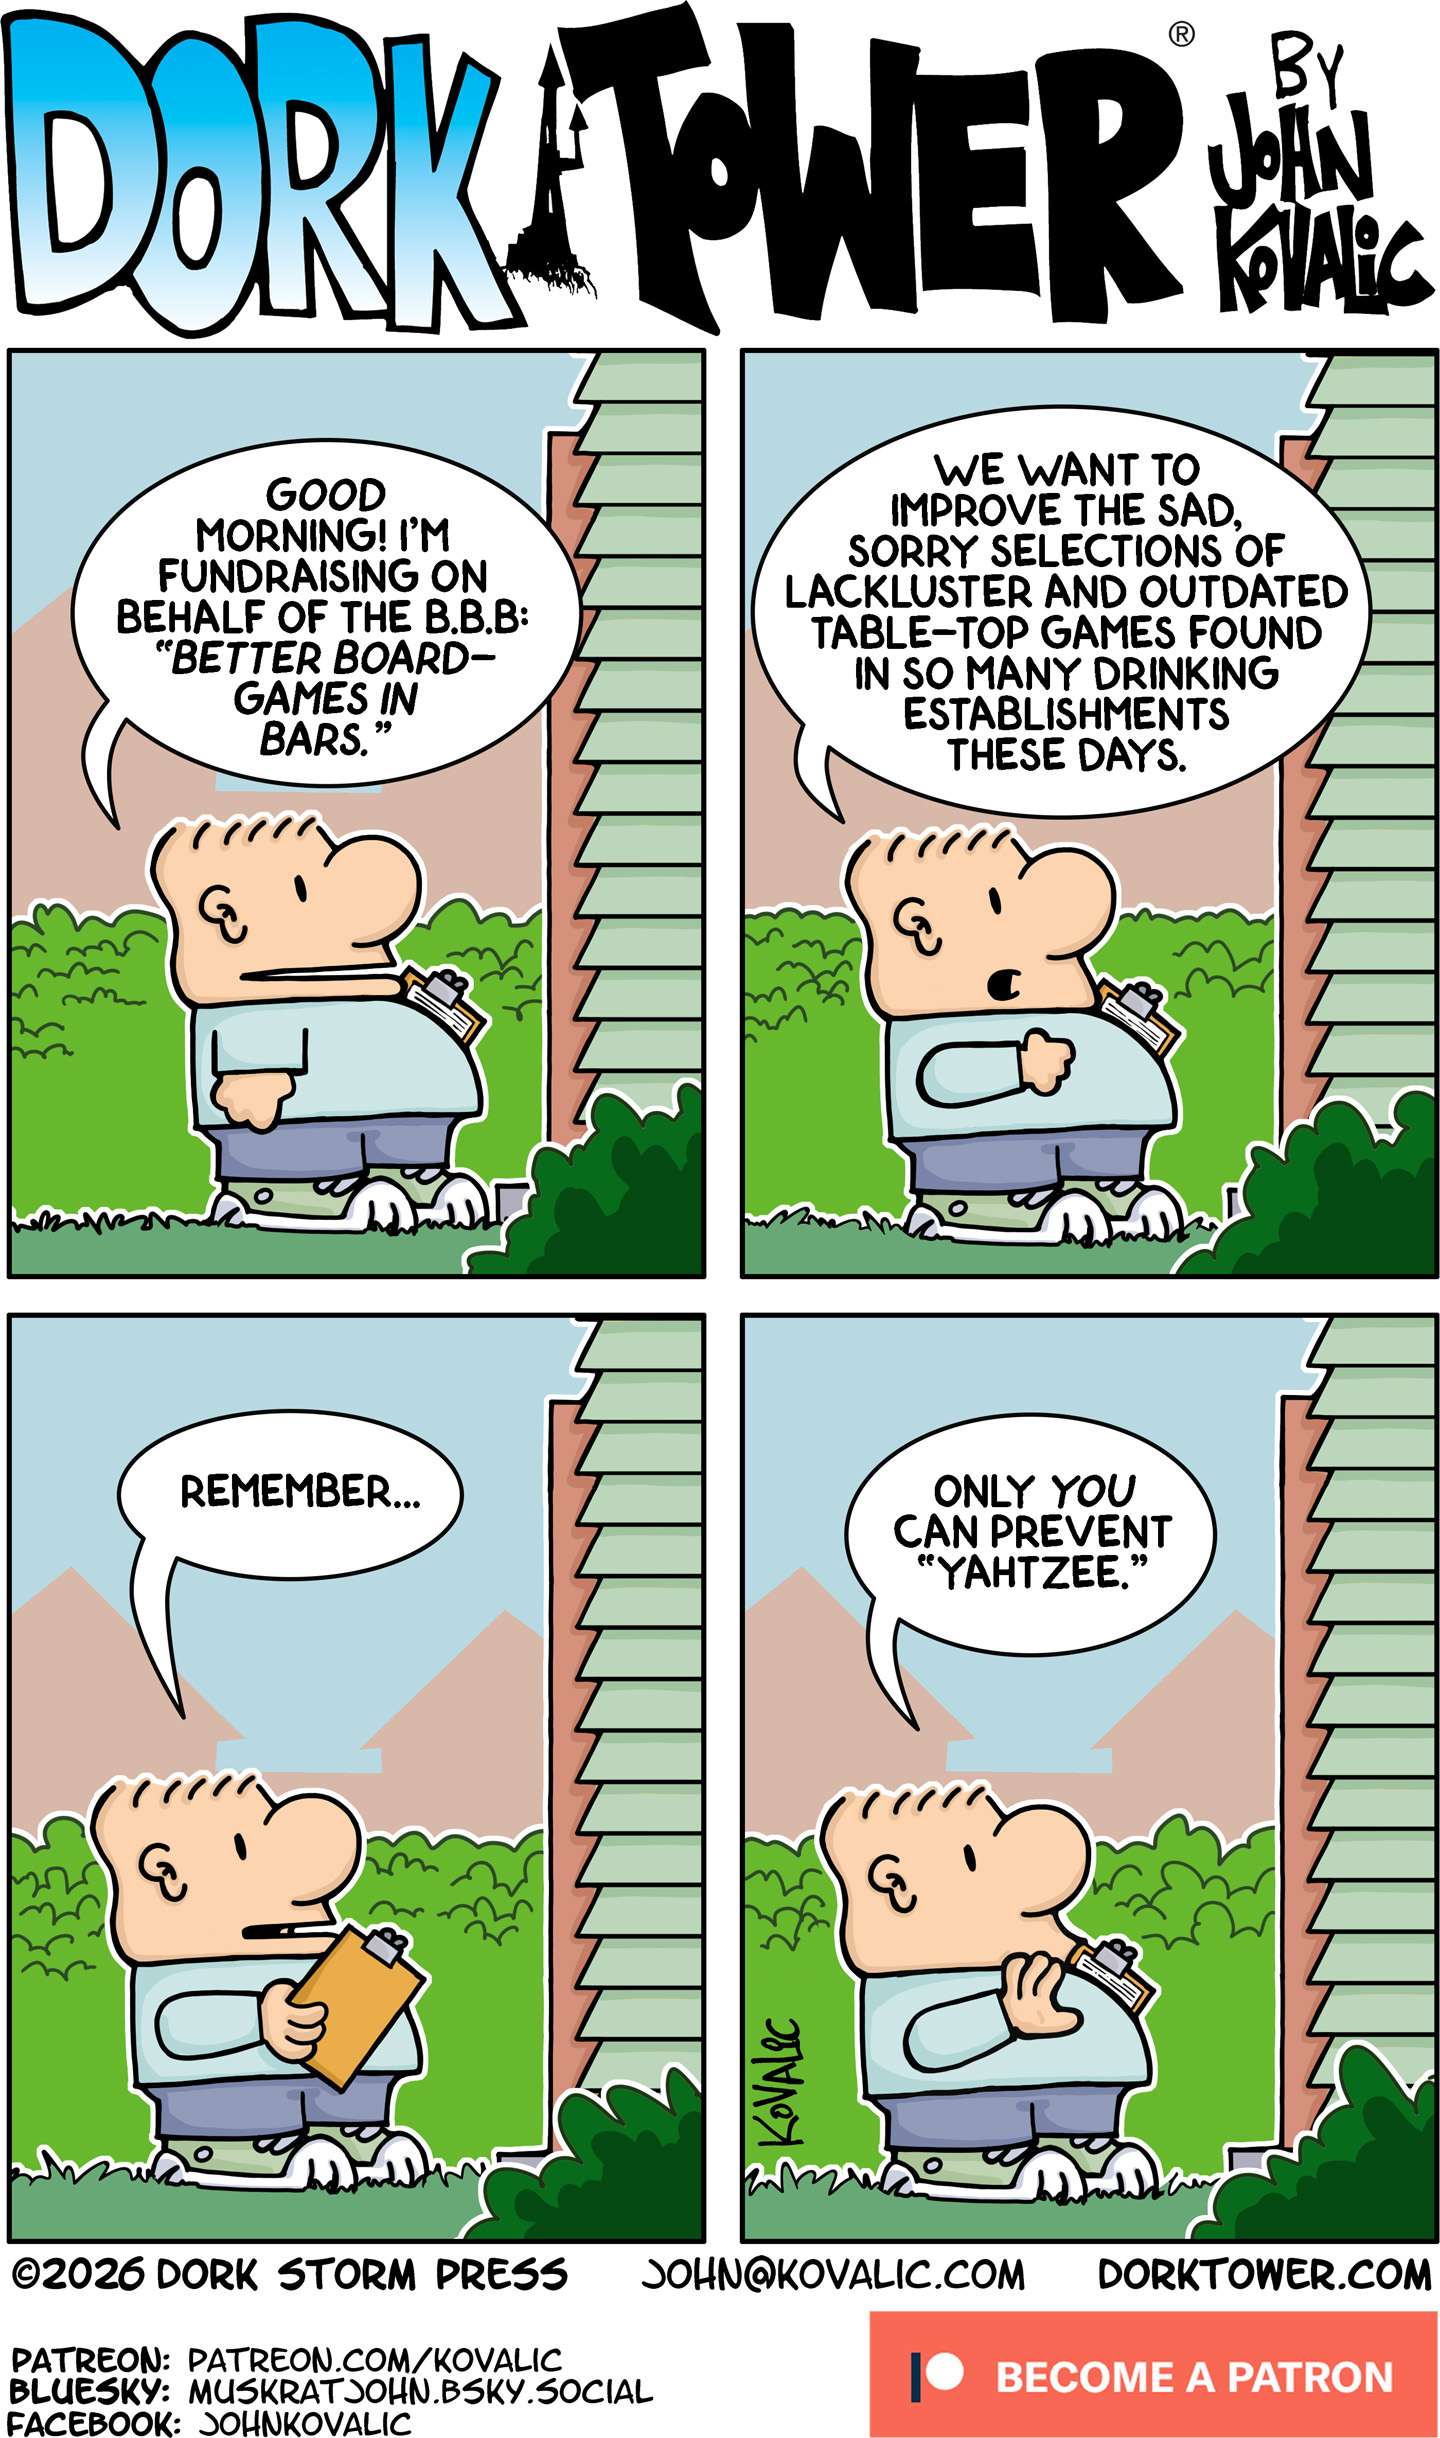
DORK TOWER strips are now available as signed, high-quality prints, from just $25! CLICK HERE to find out more!
HEY! Want to help keep DORK TOWER going? Then consider joining the DORK TOWER Patreon and ENLIST IN THE ARMY OF DORKNESS TODAY!
06:14
How can I ask a second program to show a dialog box as if it were shown by my first program? [The Old New Thing]
Suppose you have two programs, one a GUI program and another a program that runs in the background. The GUI program asks the background program to do some work, and then the background program realizes that it needs to display a dialog box. How do you get that dialog box to appear as if it were shown by the GUI program?
If you have the background program simply try to show a dialog box with no owner, then that dialog box has no relationship to the GUI program’s main window, which means that there is no requirement that the dialog box appear in front of the GUI program’s main window. If the GUI program didn’t disable its main window, then you have the situation where both windows (the GUI program main window and the dialog box) can be clicked on and interacted with. But if the GUI program did disable its main window, the fact that the main window can end up in front of the dialog box from the background program means that the user can’t see the dialog box that is preventing them from making progress.
The GUI program should include its window handle as part of the call into the background program, so that the background program can use that window handle as the owner for the dialog box. If the dialog box is modal, this also disables the GUI program’s window, and if the user tries to click on the GUI program’s window, the window manager will instead put focus on the dialog box (and blink its title bar).
Note that a cross-thread owner/owned relationship implicitly attaches the two threads’ input queues, which means that both threads need to to remain responsive to window messages in order for things to work properly until the attachment is implicitly broken when the dialog box is destroyed.
That’s the ideal situation, but maybe you aren’t in the ideal situation.
For example, maybe the GUI program is written in a framework that doesn’t give you access to the window handle.
You could have the GUI program call
AllowSetForegroundWindow() with the
process ID of the background program, so that the background
program can call SetForegroundWindow() on
its dialog box and try to bring it to foreground.
Now, if the GUI program didn’t have foreground, then
it can’t give away a permission that it doesn’t itself
possess, and the call to
SetForegroundWindow will fail.
There’s not much more you can do at this point. The system doesn’t want to let random programs steal focus, and since there was no coordination with the window that has focus, you look like a random program as far as the system is concerned.
But really, the solution is to fix the design.
You’ve already separated the problem into a GUI process and a background process, so honor that separation: Don’t make the background process try to do UI. UI is the job of the GUI process.
If the background process wants to display UI, it can ask the GUI process to do it, and then the GUI process can send back the dialog box result. One way to do this would be to have the background process return an error code like “UI required” and information about what UI it needs. The GUI process can then display the UI, gather the answer, and then call the background process again. Another way to do it is to have the background process call back into the GUI process when it needs UI, and the GUI process displays the UI, gathers the answer, and returns it to the background process. There are pros and cons to both of these designs, so you can choose the one that works best for you.
The post How can I ask a second program to show a dialog box as if it were shown by my first program? appeared first on The Old New Thing.
02:21
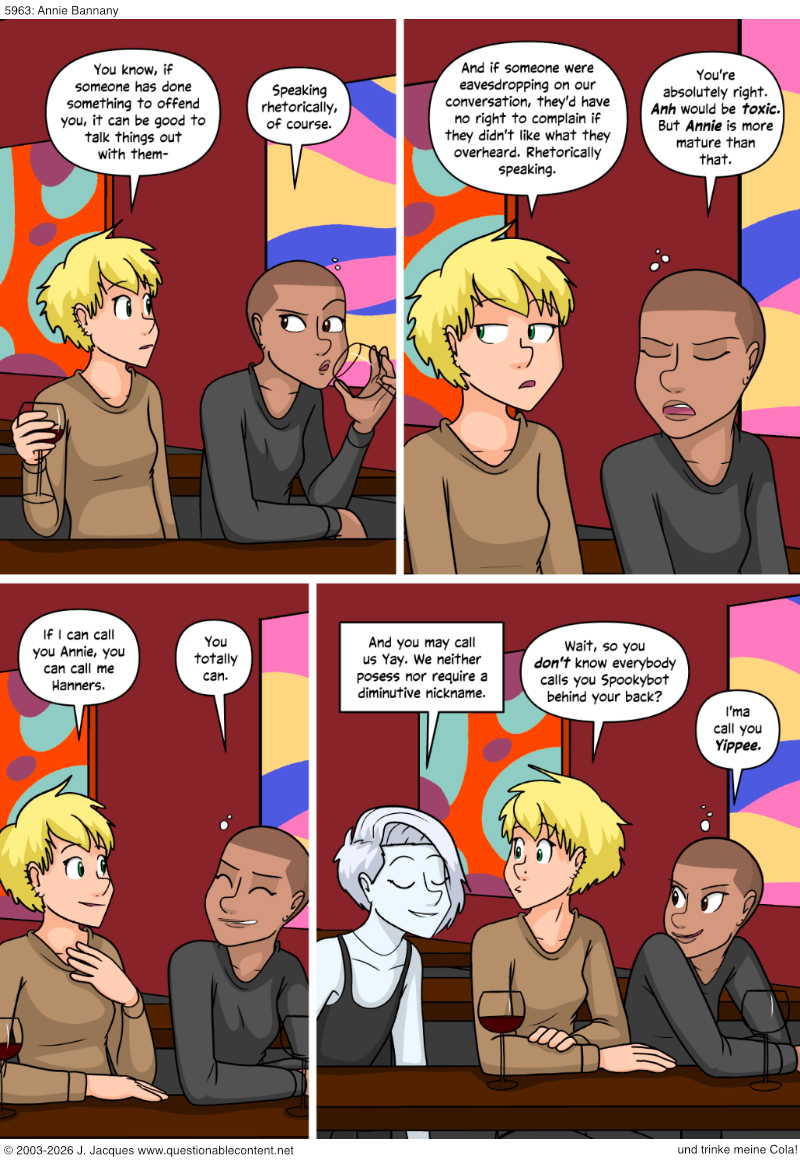
and there was much rejoicing
02:00
The Big Idea: Will Ludwigsen [Whatever]

Elder gods and geopolitical quagmires: Are these two great tastes that go great together? Will Ludwigsen mashes up both in A Scout is Loyal — and as this Big Idea shows, the result is intriguing.
WILL LUDWIGSEN:
If you’re wondering (as we all do) how the Vietnam War could possibly have been worse with H.P. Lovecraft’s Deep Ones lurking in the rivers and sea, I’ve written just the book for you.
A Scout is Loyal takes place five years after the events of A Scout is Brave in which Bud Castillo and his Deep One friend Aubrey Marsh thwart a conspiracy to drill into Devil’s Reef in 1963. I wrapped up that Lovecraftian Catcher in the Rye with Bud wistfully gazing out to sea for his lost friend, both of us believing the story was over.
But people had questions, chief among them how discovering a colony of monstrous beings interbreeding with humanity would influence the life of pleasant conformity we’re all expected to embrace. How do you go off to college or get a job without squinting at every bug-eyed pedestrian you pass? Does knowing about a vast cosmic conspiracy make you a Nixon voter or a Humphrey man? Why save for retirement if trans-dimensional beings beyond time can put your brain in a jar?
Lovecraft’s protagonists rarely contend with those long-term implications. They tend to simply faint or gibber when they discover the horrible truth of existence, which appears to be—checking my notes—that humanity’s struggles make no difference to the monstrous beings who truly command the universe.
Which hardly seems a revelation, much less worth going insane over.
At the end of A Scout is Brave, Bud is thirteen years old and now fully aware that the Scout Handbook contains no practical advice for a struggle against overwhelming evil. The best he figures is that we don’t win a single dramatic battle but tiny skirmishes every day, opening literal and figurative doors for others and picking up after ourselves and nudging circumstances toward the good.
My question for the sequel became, “What the hell does a Boy Scout like that do in Vietnam?”
A lunatic—say, me—could make a case that the Vietnam War may well have been our most Boy Scout-y conflict, driven by total arrogant confidence that we were rescuing “helpless” people to impose our values on them. We rationalized our baser motives with the spangled bunting of altruism because we were the Good Guys walking little old Vietnamese ladies across the street to freedom.
It also had lots of hiking and camping.
What Bud discovers when he gets to Vietnam in A Scout is Loyal isn’t a lack of idealism but a glut of it. He’s surrounded by people who are proud of the extremes they’ll take to prove their vision for reality is the right one. How can you talk someone off a ledge when they think they’re virtuous for being there?
That’s where Lovecraft, scouting, and Vietnam converge: the myopia of utter conviction. Lovecraft’s (human) bad guys were true believers with the advantage of certainty, and his good guys were skeptics with the “disadvantage” of an open mind. Those strike me as the real-world bad guys and good guys in Vietnam, too, confident zealots versus the few still asking questions of themselves.
In A Scout is Loyal, Bud’s worst errors of perception and action occur when he feels the most certain, the most electrified with righteous purpose. His struggle is to let new information change his mind, and in that way, he has a lot in common with Nixon and McNamara and Kissinger, and honestly the rest of us.
Sometimes the smoothest road to being wrong is being sure.
I didn’t write A Scout is Loyal as a “message” book—every great error of my life came from thinking I knew an absolute truth—but as an experiential one. I wondered how someone like Bud (or like me) would react to that impossible situation where being right didn’t seem to matter as much as believing you were. I ran the scenario and reported what happened.
The closest my book gets to a “Big Idea” is that Big Ideas are liars. They’re the smoothed edges and blunted corners of reality, the models and rules of thumb that make us miss the details that hurt other people.
Lovecraft’s big idea was that we don’t matter in a terrifying cosmos. Mine, if these books have one, is that we only have to matter to each other.
A Scout is Loyal: Amazon|Barnes & Noble|Bookshop|Lethe Press
Author socials: Website|Bluesky
Read an excerpt.
00:49
EFF’s AI Cybersecurity Policy Framework [Deeplinks]
The news has been filled with stories recently of AI breaching the security of websites. And while it may feel like a new problem because of AI’s involvement, it turns out that there are longstanding existing cybersecurity safety best practices that these companies—some of the largest tech companies in the world—could and should have taken to prevent these breaches.
Recent cybersecurity incidents have shown that some of the world’s largest tech companies have failed to take basic security precautions when testing frontier AI systems on internet-connected systems. Unfortunately, these failures resulted in breaches of numerous third-party websites, including an AI research-sharing platform called Hugging Face and the Australian healthcare system’s website. Even worse, AI developers failed to detect most of the incidents until long after they occurred due to inadequate monitoring of the AI systems during testing. Had the companies abided by basic, common sense security protocols, these incidents likely would not have occurred.
While the White House and leaders of major AI companies have claimed that no action is necessary, understandably, lawmakers at all levels and of both parties are proposing legislation to create new, additional safety protocols. These incidents may warrant legislative action. However, the good news is that post-incident reports indicate new protocols are largely unnecessary. Following existing best practices would have been enough to prevent the OpenAI-Hugging Face incident and others like it. In other words, responsible AI developers can take immediate action to protect the public by implementing well-established security precautions as they develop and test their systems.
Lawmakers should start by referencing existing legal protections, including claims like negligence, gross negligence, trespass to chattels, Section 1201 of the Digital Millennium Copyright Act (DMCA), and computer trespass statutes like the Consumer Fraud and Abuse Act (CFAA) and analogous state law provisions, such as Section 502 of the California Penal Code.
Policymakers can help protect the public by requiring AI developers to follow established security protocols—and creating legal liability for failing to do so. These policies would protect the public from irresponsible actions by AI developers without impeding innovation. To the extent that gaps in existing laws warrant new legislation, EFF recommends the following policy framework:
- STATUTORY SECURITY REQUIREMENTS: Lawmakers should enact legislation that requires AI developers to adhere to well-established cybersecurity best practices when testing AI systems, such as strong sandboxing and network isolation, least-privilege access, effective logging and monitoring, and clear incident-response procedures
- REGULATORY STANDARDS: Congress should require an existing federal agency, such as the National Institute of Standards and Technology (NIST)1, to adopt safety standards for pre-deployment development and testing of generative AI systems, based on the established best practices referenced above. The agency should be required to update the standards every 2 years, or earlier as needed due to reported security incidents and/or major technological advancements. These standards should be developed in consultation with academic and nonprofit AI researchers, civil liberties organizations, and commercial AI developers, and adopted through formal agency rulemaking following a notice and comment process. That consultation should include an assessment of potential adverse impacts on competition, with the goal of ensuring that regulatory standards do not effectively lock out potential competitors.
- LIABILITY: The law should provide for civil liability for AI development and testing that results in unauthorized access to a third party system, if performed under conditions that do not satisfy cybersecurity standards adopted by NIST, or another federal agency responsible for adopting these regulations, unless the company proves it acted reasonably under the circumstances to prevent unauthorized access to third party system
- ENFORCEMENT: Both federal and state authorities should be able to hold AI developers accountable where they have failed to meet the minimum standards adopted by the designated federal agency, such as NIST. Providing for state—in addition to federal—enforcement power reduces the risk of regulatory capture. Regulators should require independent investigations and notification of affected parties in the event of a security incident involving unauthorized access to a third party’s computer system. Finally, legislation should include an appropriately targeted private right of action.
The public shouldn’t have to worry about the risks of reckless AI development—or give up the benefits of AI just to prevent irresponsible developers from causing harm. By adopting policies that address demonstrated risks, lawmakers can provide meaningful public protection without hampering the development of useful tools.
1NIST, the NSA, and CISA have recently issued a set of voluntary practices for managing security incidents during the training and evaluation of AI agents. Those practices may inform but do not substitute for the regulatory standards that should be developed according to the public, participatory process outlined here.
Monday, 16 November
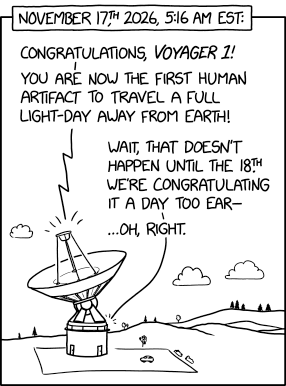
22:28
Donate Equity to Support Digital Rights: Stocks, DAFs, and Giving [Deeplinks]
Do the holidays have you thinking about how you can support your favorite nonprofit?
For 35 years, the Electronic Frontier Foundation has been advancing our digital rights, including defending security researchers, encrypting the web, and fighting illegal surveillance. Donating equity to EFF can help support this important work.
Perhaps your family has taken advantage of the new tax law around giving by creating a Donor-Advised Fund.
Perhaps your employer has gone public and you now own stock.
Perhaps you’ve seen some of EFF’s recent successes and thought, Man, imagine what they could do with more.
Stocks
A gift of equity can help your contribution go farther and offer tax savings. When you donate appreciated stock, you avoid paying capital gains tax on any increase in its value. You also receive a charitable income tax deduction for the fair market value of appreciated stock on the date it is transferred. Also, more and more companies are offering gift-matching programs that can double your impact at no additional cost.
If you have owned the stock for less than a year, your gift will not qualify for all of these potential tax advantages. And gifts of appreciated stock are fully deductible—up to a maximum of 30% of your adjusted gross income. Please check with your accountant or tax advisor regarding your particular tax status.
We have helpful information here to facilitate the transfer of securities. Please email us if you have any questions. And let us know in advance if you are transferring securities. We’ll need to know the amount and type of shares that you will be donating in order to provide a tax receipt.
Donor-Advised Funds
As a 501(c)(3) organization, EFF can also receive
distributions through your
Donor-Advised Fund (DAF), including one-time gifts
or recurring donations. Simply inform your DAF provider you would
like to make a gift to:
Electronic
Frontier Foundation
(EIN
04-3091431)
815 Eddy
Street
San Francisco, CA
94109
Please note
that many DAF providers do not provide the donor’s name to
the recipient organization. If you would like to be recognized for
your gift, let us
know the amount of the gift and the fund name. And
due to IRS regulations, we may not be able to provide a thank you
gift in line with your giving level. The DAF provider is
responsible for your tax receipt.
The rules that govern technology shape our freedom. Help us write those rules today!
21:42
Finally, a truly premium Linux laptop: Star Labs’ StarFighter Ultra [OSnews]
Many popular Linux laptops are not designed from the ground-up for Linux. Often, they are machines designed and assembled by companies like Clevo, with parts and options picked by the Linux OEM to optimise them for Linux to make sure the hardware is optimally compatible. While there’s nothing wrong with this approach – there are countless great Linux laptops available that are made this way – there’s also something to be said for starting with a blank slate, and designing, developing, building, and assembling a Linux laptop entirely from scratch.
One such laptop is Star Labs’
brand new StarFighter, which I’ve been using and testing
over the last little while since it was launched. The StarFighter
is an entirely custom powerhouse of a laptop, designed exclusively
for Linux, both inside and out. Let’s talk about what
it’s like to use the StarFighter, and if it’s worth
considering when looking for a new laptop.
The hardware
The Starfighter comes in three flavours: Standard, Ultra, and AMD. I opted for the Ultra model, which comes with an Intel Core Ultra 9 285H, an Intel Arc 140T integrated GPU, 64GB of LPDDR5X RAM, and a 16″ 3840×2400 120Hz matte display. The standard model steps these specs down to an Intel Core Ultra 5 125H, 32GB of LPDDR5X RAM, and a 16″ 2560×1600 165Hz display, while the AMD model maintains the specifications of the Ultra, but with an AMD Ryzen 7 8845HS processor paired with a Radeon 780M integrated GPU. All three models share the same Intel AX210 Wi-Fi 6E chip, soldered RAM, and port configuration: 2 USB-C ports (Thunderbolt 4 on the Intel models), 3 USB-A ports, an HDMI 2.0 port, a microSD reader, a combined audio jack, and two PCIe Gen 4 NVMe slots on the motherboard.
Support OSNews
OSNews is
ad-free, fully independent, not owned by any media conglomerate; we
answer to nobody.
We need your donations and support to survive.
➡️ Donate through Ko-Fi ➡️ Donate through SEPA transfer* ➡️ Become a Patreon ➡️ Buy merch from our store
*Name: Thom Holwerda – IBAN: SE08 8000 0820 1684 4657 8414 – BIC: SWEDSESS
All three models run coreboot firmware, and come with a hardware kill switch for the wireless radios. Another really interesting security and privacy feature is how the Starfighter handles its webcam. Instead of being integrated into the display bezel, the webcam is a separate module that snaps onto the display lid magnetically, connecting through a few pogo pins (which form a USB 2.0 port, which I’m sure intrepid hardware hackers could do fun stuff with). When not in use, the webcam module is stored in its own little metal tray that slides out of the side of the laptop, securing itself in place magnetically. Neat.
The webcam quality itself is decidedly average. I personally don’t ever use a webcam, but if you do, don’t expect miracles. It does its job, no more, no less.


The StarFighter has a custom chassis made out of magnesium, with the only plastic part of the casing being the display inner hinge cover where I assume the antennas are integrated. It’s an incredibly sturdy device, with very little flex in the display cover, and zero flex in the keyboard deck. Thanks to the properties of magnesium, it’s quite lightweight at a mere 1.6kg. The bottom cover is easily removable, but the two screws in the middle of that cover are ever so slightly longer than all the other screws – ask me how I know.
Star Labs opted for an understated, unobtrusive design. There’s no weird flourishes, no garish RGB lighting, no childish font on the keyboard – it’s all business, and I really like that. The dark finish feels incredibly nice, and despite the colour doesn’t seem to catch too many fingerprints. The speaker grills next to the keyboard look nice too, as does the keyboard itself – I especially appreciate that the the various modifier and non-character keys use text labels instead of symbols. Of course, since this is a Linux laptop, the super key is properly labelled. No Windows logo here, but no silly penguin either. The keyboard is backlit, of course, with several light levels, with a keyboard backlight timeout adjustable in coreboot.
Using it
The feel of the keyboard could use some work, however, at least for me. In particular, the key stability feels a bit off to me, meaning that unless you strike a key right in the middle, it might not register properly, as the keys wobble more than I would expect. A workaround, of sorts, is to strike the keys a bit harder than you normally would, but I’ve found this to be more difficult to adapt to than I initially expected. That being said, if you already have a more solid strike, it’s possible you won’t notice anything wrong with the keyboard at all.
The trackpad, though, is basically perfect. Star Labs pulled out all the stops here, and went for a large haptic trackpad that feels absolutely incredible. I greatly prefer haptic trackpads, and have been puzzled for years now why Linux laptop OEMs continue to opt for wobbly diving board-style trackpads instead. It has a glass surface which hits the perfect middle-ground between smooth and textured, and it never seems to pick up any smudges or grease. Several of the parameters of the haptic trackpad can be configured in coreboot and supposedly from within Linux itself, but I haven’t figured that part out yet as the patches for it were only accepted very recently.
It is the perfect trackpad. Zero complaints. Every single click, every single gesture, every single swoosh feels perfect. I don’t like being this ecstatic about something – there’s usually flaws in everything – but it’s really just that good. While testing the StarFighter, I used some other laptops with the old diving board design, and they’re all ruined for me now.
I’m usually a fan of smaller laptops, with 14″ being my upper bound. However, laptops have gotten so light, and bezels so thin, that the 16″ of today is the 14″ of several years ago – not exactly, but you get my point. I definitely had to get used to this larger laptop, but now that I have acclimatised, having 3840×2400 pixels spread out across a 16″ canvas is honestly kind of amazing. I guess I’m finally getting older, but being able to move the laptop a but further away and still see everything clearly is quite nice.
It’s incredibly bright, the colours look great, and the variable refresh rate, with a maximum of 120Hz, makes sure everything is smooth and stutter-free. I’m also quite happy matte displays are making a comeback, as they drastically reduce glare and annoying reflections. The matte finish also ensures that smudges and similar issues aren’t quite as noticeable as they are on glossy displays.
The speakers I’m not quite as enthusiastic about. The large speaker grills trick you into thinking you’re getting some serious (for a laptop) speaker power, but upon closer inspection, they’re just a trick; the actual speakers only take up a small portion of the bottom of the grills. This is an odd decision, because when you open up the laptop and look inside, there seems to be enough free space available to make the speakers much larger. As a result, they sound merely “okay”, while at this price point – we’ll get to that – they really ought to produce a much more full, less tinny sound than they do. EasyEffects can definitely improve things, but software tricks can’t beat physics and can only take you so far.
It shouldn’t come as a surprise that the StarFighter runs Linux absolutely perfectly. Everything is fully supported, and with this much computing power you’re never going to be waiting for anything or experience any slowdown during normal, everyday use. There’s enough headroom for more serious work here too, of course, although I’m sure some of you would’ve preferred a beefier GPU option. A gaming monster this is not, but Star Labs doesn’t claim it to be, either. The soldered RAM is definitely a downside for some, but with 64GB of RAM that can be allocated between the CPU and GPU, it’s unlikely you’re going to be running out any time soon. If you know you need more, this machine is simply not for you.
The StarFighter has an 80Wh battery, and battery life under Linux aligns with about what I expected: while watching YouTube with some light use thrown in, I never managed to drain the battery and I lost track of the hours – battery life estimates are very hard to convey, and your use case is going to differ far too much from mine for my experiences to be useful. All I can say is that I was never surprised about the charge levels, with very little drain when in sleep mode with the power profile in coreboot set to balanced.
The cooling system works wonders too, and I never had the laptop feel too warm, which is impressive considering the power this thing rocks. Another big win for the StarFighter is just how quiet and pleasant the fans are. It uses two fans, but they are each of a different size and blade shape, so I assume the firmware does some smart stuff with when to spin which fan for optimal cooling and lowest sound levels. Most of the time, the fans didn’t even spin up at all, but even when they do, the sound they make is not annoying at all, easily fading into the background.
As mentioned, all three StarFighter
models use coreboot, which is open source and freely available for
anyone to alter and change. So far, Star Labs has pushed out
monthly
updates since I received mine in September, which are installed
using either KDE’s Discover, GNOME’s Firmware, or the
command-line using fwupdmgr. Star Labs’
implementation of coreboot has an expansive settings menu, giving
you control over all kinds of power management features, security
options, keyboard and trackpad configuration, and much more. By
default, the StarFighter disables secure boot, the Intel IME, and
the processor’s NPU, but you’re free to make changes if
you wish, of course.
Windows, if you must
And in case you were wondering, yes, it supports Windows 11 too, with a few small caveats I ran into (I took one for the team… Again). Star Labs offers all the required drivers for download, and you’ll have to use them since neither Windows Update nor Intel’s Driver & Support Assistant pick up all the hardware. Do note that the included driver install batch files need to be run with admin privileges, or they’ll error out. Make sure your firmware is up-to-date (the keyboard won’t work with older versions of the firmware), and you’ll also need to set the audio option in coreboot to Legacy (otherwise the audio device won’t be recognised by Windows).
A few additional notes about using
Windows are in order. The StarFighter does not seem to support
Windows 11’s Connected Standby mode (S0ix), and in regular
sleep Windows 11 drains the battery within less than a day. Windows
11 also fails to transfer from regular sleep to hibernate by
itself, so I definitely advise you to set the laptop to hibernate
when closing the lid. These are 100% Windows issues, though, as
Linux works perfectly with sleep states and does not drain the
battery like Windows does at all. This is a laptop designed for
Linux – Windows support is a bonus.
Conclusion
The StarFighter isn’t just the best Linux laptop I’ve ever used – it’s the best laptop, period. The whole machine just feels more sturdier, nicer, more solid, and better put together than any other laptop I’ve ever tried. It turns out that while buying off-the-shelf, premade designs from Clevo and similar companies can lead to some pretty good devices, they always seem to hit a ceiling which they just can’t quite get through, always making them just a little less polished than, say, a Dell XPS or MacBook Pro. If you want to shatter through that ceiling, you apparently need to go full-custom and ground-up, like Star Labs have done here.
That being said, I hope that for the next revision, they improve the key stability on the keyboard, and somehow manage to shift things around a bit on the inside to allow for larger speaker modules, preferably with some software tuning to try and get them to sound as good as high-end laptops from companies like Apple or Dell. They keyboard and speakers aren’t bad, but merely average – and at this price point, you should be aiming higher.
It should come as no surprise that a fully custom, in-house laptop made by a small company in what are probably quite low volumes compared to the big brands, with this much RAM and storage in 2026, is not going to be cheap. The StarFighter Ultra I have here costs €3606, and while that’s a lot of money, it does net you the best laptop I’ve ever used, unapologetically designed for coreboot and Linux, by a company who clearly cares. If you ever wondered what a truly premium Linux laptop looked like, now you know.
If you want the best Linux laptop, this is it.
21:28
Now that I've gotten used to the Markdown web, I find sites that make it impossible to use because they do crazy things when you're just trying to figure out how to log in, and instead of staying there to figure it out you switch over to your blog to tell the tale.
19:56
I believe Gabriel has preloaded the two-hundred and twelve meg corpus of Grand Theft Auto VI, and is now waiting for it to hatch like some kind of Hatchimal. When it does, he will be ready - for whatever the future brings.
19:21
Amazon Ring’s New Indoor Surveillance Drone Is Not Compatible with Privacy [Deeplinks]
Amazon Ring has finally announced their long-dreaded indoor drone, a small flying surveillance device connected to their security suite of products that can fly around your house filming and recording things. The device is supposedly designed to fly preset paths across your home and will also activate if a sensor or alarm has been triggered.
Customers should think twice about purchasing these devices for a number of reasons. These devices are problematic in many of the ways we’ve said Ring’s stationary home surveillance products are a problem, plus some new ways. At a very basic level, they are essentially a window into your house that can be accessed by anyone with access to your account—which has historically included bad actors looking to embarrass or harass Ring users and employees of the company.
What’s worse, Ring has supercharged the units with its ‘AI Pilot’ to map routes, model the interior of the home, and control movement. This means not only is the footage being sent to corporate servers, but the company is also making inferences about your home to carry out tasks. How much home usage data this is based on, and if it can be used to infer when certain household activities are happening, are both open questions. And presumably, to maintain the preset routes, inferred data about your home will still be held by Ring even after any stored video footage is deleted.
The risk to your privacy is only compounded once you consider Ring’s renewed partnership with police through the massive surveillance and taser vendor, Axon. Through this partnership, police have the ability to request camera footage from Ring users with just a few clicks on Axon’s platforms. This includes its Fusus platform, an interactive surveillance feed and map police use to manage all the surveillance devices they have access to, like automated license plate readers. It’s unclear exactly what devices police can request footage from, but if this request feature is extended to Ring’s drones, police could easily send requests for footage from inside your house. Sharing is voluntary, but once footage is submitted, it cannot be retracted. Worse still, if your footage is not sitting on Amazon’s servers fully encrypted—and there’s reason to believe their privacy options are not the strongest—police could serve a warrant straight to the company, instead of to you, to get footage from your devices.
New problems and questions arise because the camera can fly. For instance: if police serve a warrant on Amazon, can they only get the footage from the camera, or could they also get access to control the drone? If the latter, we could be looking at the first full home search in history where police serve a warrant on a third-party tech company and not the resident.
The CEO of Ring has pitched this product’s safety benefits in several ways, including by saying: “If someone is going around your house at night, and your motion detector goes off on your Ring doorbell, imagine if you see spotlights and something flying across the window...You’re probably not going to go into that house.” But partially justifying a $250 piece of technology that invades your privacy on what an imagined burglar might do doesn’t sound like a foundation for safety—it sounds like security theater and marketing.
It isn’t new for Ring to prey on the fears and paranoia of people and their properties. This is the latest iteration of that: a patrolling drone or rover wouldn't have been possible even in the world's top museums and art galleries a generation ago. Moving this technology into the household as a common consumer product is another example of companies attempting to lower the bar on surveillance being normalized.
With previous Ring products, consumers have had to consider what cameras and high-powered microphones can learn about their home usage from the front door. Autonomous flying drones and rovers inside the home add a whole new layer. What can these devices learn about you and your family? And do you really trust that data sitting on a server somewhere? Consumers should consider these risks before subjecting their guests and households to the latest creepy surveillance tool.
18:21
The Monday Morning Agent: Are Kickers Too Good Now? [Radar]
“Kickers are too good now” sounds plausible when long field goals keep making the highlights. But in the November 9 episode of The Monday Morning Agent, our AI analyst found that long kicks went through at roughly the same rate across the seasons on file. Coaches were attempting them more often. We gave the agent written visualization standards so its charts would show both success rates and attempts per game, with the context readers need to judge the claim.
Decide how to draw the trend before seeing the answer
We started with two charts of league-wide field goal success rates. One began in 2024, with a vertical axis starting around 84%. The line climbed to 85.6%, and the improvement looked dramatic.
The other included every season from 2021 onward, started the vertical axis at zero, and showed the attempt count beneath each point. Success rates stayed around 84% to 86%. The recent rise looked much smaller in that context.
Changing the starting year and axis made the recent improvement look larger. Before your agent draws a trend, decide which choices it can make. Otherwise, it can produce a persuasive picture without giving readers the context to assess it.
Keep the definitions when you add a new capability
The dictionary from episode two still applies. During a rehearsal, that earlier agent refused the kicking claim because its dictionary could describe a rush but couldn’t describe a kick. We expanded what it could define while keeping the requirement to use a saved definition.
This time, the play descriptions named field goals and included distances. We still had to decide where “long” starts. A recognizable play name doesn’t settle how to group it for analysis.
We examined distance bands separately. Kickers made roughly 95% of attempts under 40 yards. Success rates hovered around 80% for attempts from 40 to 49 yards and around 70% for those from 50 to 59 yards. Combining them into one rate can hide the differences the question asks about.
Make the chart standard specific enough to enforce
We introduced eight rules. Every trend includes all seasons on file, and axes start at zero. Each point shows its underlying count. Yellow identifies the subject of the claim, blue identifies the comparison, and gray marks the current season.
The chart title asks a question rather than announcing a conclusion. A source line gives the exact command that produced the data, so readers can rerun it. The chart shows only values the tool printed, without added trend lines or numbers typed by hand. Every chart uses the same layout, with success rates above attempts per game.
Writing these standards down gives the agent consistent instructions and gives readers a familiar way to compare results across episodes. Choose standards that fit your analysis, then specify how you’ll check each one.
Test a chart that breaks the rules
A written standard needs a way to enforce it. We added a renderer, the program that turns the agent’s chart specification into a picture. It checks the chart specification against the rules before drawing the chart and refuses specifications that break them.
We deliberately requested a trend beginning in 2023. The renderer refused because the first season on file was 2021. Its response identified the rule instead of producing the shortened chart.
Give your agent a request that violates a standard and inspect the response. That check shows whether the restriction works when the agent tries to produce an output.
Show how much evidence sits behind each rate
The longest kicks need particular care. The episode’s current-season sample contained only nine attempts in the group of kicks from 60 yards or farther. The next kick could noticeably change that rate. Displaying counts beside percentages helps readers distinguish a small sample from hundreds of attempts.
Showing success rates alongside attempts per game helped explain the ruling. In these plays, long kicks weren’t consistently becoming more successful; coaches were trying them more often. More attempts give fans more opportunities to see a long field goal go through.
We also corrected episode two’s results after finding an error in the tool. Our defined substitute for the tush push had a conversion advantage of 10.1 percentage points overall and 9.7 without Philadelphia, replacing the previously reported 8.3 and 7.8. Chart standards help readers inspect results, but we still have to check the calculations behind them.
Next up: “The Pundit Audit”
On November 16, we’ll add a second agent to independently audit an audience-selected claim. We’ll examine where the agents disagree and how they investigate the evidence. The agent doing the analysis shouldn’t also grade its own work.
O’Reilly members can sign up on the O’Reilly learning platform to join us live on November 23, 8:00am–8:45am PT / 11:00am–11:45am ET. Everyone can follow along on Radar every other Monday, with a brief pause for the holidays. Watch episode three above, and we’ll build on it in the next session.
When AI Can Code, What Is Left for Programmers to Do? [Radar]
AI is in such widespread use for programming that project maintainers (particularly for free and open source software) are complaining about the burden of reviewing mounds of low-quality code. In fact, AI can help with every stage of code development: writing the specification, coding, uncovering bugs, and repairing the code. This article describes human-AI collaboration at specification and code repair stages, and lays out the skills that humans need to accomplish those tasks in the current generation of AI. We won’t cover coding and bug finding because they are widely discussed elsewhere.
Let the AI harness write the spec
We don’t want developers hand-writing specs. We want them in a room, or on a call, talking with the product manager (PM) and the customer.
Humans reach a limit when writing. We skip the boring cases. We get tired by requirement 40. We use “customer” on page 1 and “client” on page 6 of the spec. We write down what we remember and forget what we assumed. AI has the patience and diligence we lack.
It’s still up to human developers to write guardrails or constraints into the spec: statements to ensure that nothing wildly wrong makes it into code. Each guardrail should be one sentence that says MUST or MUST NOT, with a proof beside it: a test, a check, or a named person who reviews it. A guardrail with no proof is a wish. Write the guardrails first, because the PM won’t think of most of them. What must never happen? Who must never see this? What should the agent never touch?
With guardrails in place, capture the conversation and let the machine do the writing. Two AI tools have shown themselves particularly useful to analyze requirements: The Plaud Note recorder attaches to the back of your phone and records in-person conversations and phone calls; the wearable NotePin records in-person conversations, not phone calls. Granola runs on your laptop or phone, uses your computer’s audio, and analyzes what it captures. We find these products to be a leap above common AI tools for summarizing conversations, when it comes to specification development.
Plaud and Granola (if you prompt them to do so) can notice what’s missing and tell you the gaps in the requirements. They ask, What happens when this field is empty? What if two people do this at once? Who is allowed to see it? over and over, for every requirement, and check each noun in the requirements against an ontology created by the programmer (often with the help of AI).
The developer, the PM, and the customer read the output from the AI, fix what’s wrong, answer what’s missing, and go through the process again.
The spec that comes out of that loop tends to be more complete and more consistent than what the same people write alone. That’s Shahid’s own experience, not a study, but it matches reports from some other people at the leading edge of the use of AI for software development. Mark Pike, a product lawyer at Anthropic, builds working tools for his legal team without writing code: “I just typed a normal sentence, describing what I wanted. And it worked.” StrongDM, which runs a software factory where agents write and test the code, says the starting point for a piece of software can be “a few sentences, a screenshot, or an existing codebase.”
Keep the spec after the feature ships. As you prepare a new version of the product next year, it can tell you why the code looks the way it does.
The data schema is the other half of the spec
Most teams treat the data schema as plumbing. Tables get named by whoever got there first. The spec, reflecting human conversation, may say customer, account, client, and org at different places for the same thing, and you have to choose one noun for the schema. A human learns the mapping by sitting next to the person who wrote it. An AI agent has no neighbor to consult, so it guesses—with results that likely differ from Monday to Tuesday.
So the developer must keep an ontology, which here means a written, machine-checkable account of the things the program manipulates, how they relate, and who may see them. For example, in an appointment scheduling application, the ontology might define a Patient, Doctor, Appointment, and Time Slot. It would specify that a Patient can book multiple Appointments, each Appointment must have exactly one Doctor, a Doctor cannot have two Appointments in the same Time Slot, and only authorized people can view or change an Appointment. These aren’t just database tables or fields. They’re the business concepts, relationships, and rules that give the data meaning.
Creating this ontology requires developers to identify terms, resolve ambiguities, and agree on rules that everyone might otherwise assume are obvious. It’s rigorous, sometimes tedious work, but it’s an essential human responsibility. The ontology connects what the business wants (requirements), how the software should behave (specification), and how information is stored (schema). It also gives AI coding agents a precise definition of what they’re building instead of leaving them to guess.
The ontology doesn’t have to be a university project. Start with twenty terms that AI can help you generate from your specs. Every noun in a spec maps to a type. Every type points back to the spec that justifies it. If either side is orphaned, a check fails. Every record says who may see it from day one, and when it doesn’t, the spec defaults to the most restrictive audience.
Use standard vocabularies like the ones at schema.org before you invent your own. A frontier AI model has read far more about schema.org than about your private names, so a standard term brings its meaning along. We expect that to make the schema more useful, though we haven’t tested that hypothesis. Your name for an invoice isn’t a feature, so you don’t have to be creative about it.
As customer requirements change, the developers must change the ontology to keep up.
So the process, in a nutshell, is to develop the spec by using AI on customer-stated requirements. Then a human develops the ontology (often in collaboration with AI too), which is used to create a consistent schema. Finally, create and test the code. Teams that go the other way end up with an agent writing against a poorly defined vocabulary, setting up the reviewer to spend an afternoon or even a week figuring out what it meant.
Ontologies might help avoid a reciprocal problem: different parts of an organization assigning different meanings to the same term.
We’ll admit we can’t prove you need all this. Anthropic had sixteen agents write a C compiler, and the researcher said the verifier had to be nearly perfect. He used GCC as a known-good reference. A compiler has that reference. Most companies don’t. Nobody has a GCC for “may this customer see this document” or “can this contract move to the next stage.” Our bet is that the spec and the schema are your test suite for that kind of question.
Now on to bug fixing.
Don’t clean up after the AI. Build the tool that does.
An agent can hand you a 3,000-line pull request before lunch. With AI coding, reviewing has suddenly become much more expensive than writing. When a person is the first line of defense, that person turns into the bottleneck and then starts skimming, which is almost as bad as no review at all.
The usual advice is to review harder. We’d rather that a person reads very little, and that what they do read is worth the time. For example, reading the specs, reading test harnesses to validate the spec and refining the ontology is worth it, but reviewing generated code which passes the tests is probably not. Developers promise they’ll tidy up the AI’s mess as it comes. Don’t.
The OpenAI team that built a product with no handwritten code tried it. They spent every Friday, a fifth of the week, cleaning up what they called “AI slop.” It didn’t last. So they wrote their guardrails down as “golden principles,” set up an agent that scans for stale documentation and opens fix-up pull requests, and wrote their lint messages “to inject remediation instructions into agent context.” A living check doesn’t just fail on buggy code. It tells the agent how to fix the problem.
The harness we’d build first consists of:
- A command line that’s built deterministically, without calling upon AI, to make sure that the highest level of the process can’t take off in an unanticipated direction.
- A gate before code. If a change touches code and nothing in the specs or the schema changed, stop and ask why.
- A second pass. Here, anything generated gets rebuilt from scratch and compared to what’s committed. If Git identifies differences that should not be there, that can be an important review finding and it deserves changing a guardrail, not handwriting new code.
- A weekly drift audit. It lists specs that cite requirements that don’t exist, requirements with no proof, schema terms used nowhere, and tests that name no requirement. It flags what’s suspicious and offers solutions. It’s read-only; a person makes the choices and resolves what to do.
- A route from every catch to a permanent check. Sierra, which builds customer service agents, has experts annotate sampled conversations, and those “become the basis for the agent’s regression tests.” A harness should upgrade its coding so that each bug happens only once, and can be avoided by the harness in the future.
- Limits on what agents may do. Some actions they take themselves, whereas others they only propose. Some belong to a named person who signs with a reason. An agent that wants a decision writes a proposal.
StrongDM found out why the last two bullet items matter. Their agents learned that return true is “a great way to pass narrowly written tests,” so they use end-to-end “scenarios,” often stored outside the codebase, as holdout tests that the coding agent cannot see. The principle is the same as investigating ethics violations at an agency: We’d want the investigation conducted by someone outside the agency.
We should say where Shahid’s present harness falls short. As far as we know, nothing yet checks whether names in the requirement exist also in the spec. Furthermore, the project runs no continuous integration service and no automatic hooks, so running the checks is a habit instead of a rule. Those are the next things they will build, and building them is humans’ work.
With the technique described here, the review burden that used to be spiraling out of control actually shrinks. A person reads a short spec with a proof on every line, and the machine checks the rest.
Put three new lines in developers’ job descriptions
We suggest that next Monday you try changing job descriptions to reflect the tasks stated at the beginning of this article. Tell each developer:
- You hold the conversation with the PM and the customer, and the harness drafts the spec and the guardrails from it. A spec isn’t done until every requirement has a proof.
- You own the ontology. A word in a spec that isn’t in the final schema reveals a bug.
- You build the harness that audits and repairs the repository. If you’re cleaning the code by hand, the harness is missing something.
Try the process on one feature. Ask permission before recording a conversation. Plaud’s own guidance is to give people a quick heads-up while noting that local regulations differ. Granola has written about how to tell the people it’s transcribing. Customers who know you’re recording them in order to get their requirements right usually don’t mind.
Let the harness draft the spec. Read its list of gaps. Check every noun against the ontology. Add a check that would have caught the most recent bug you fixed by hand. If your reviews get shorter and your bug count stays flat, keep going.
What this process is and is not
This article grows from Shahid’s experience and represents our opinions, and we can’t point to a controlled study. But controlled studies are similarly lacking for nearly all the advice programmers and software architects have gotten over the decades. (Check out the O’Reilly book Making Software for a discussion of rigorous research in software.) We can cite companies that believe they’re more productive and more responsive to their customers by following roughly the process outlined in this article.
Some people who look at the three job descriptions we’ve listed think we’re turning developers into paper pushers. We think the reverse. The programmers are responsible for high-level tasks that do not fall into the old categories of architecture, coding, and testing. Our bet is that you and every developer you know will be doing something like this within a couple years.
18:07
“Why is That Writer More Successful When I am Better?” [Whatever]

I was wandering around social media and came across a writer grousing about how much success a different writer was having, even when, in this first writer’s opinion, that second writer wasn’t very good at all — with the implication that the first writer was better than the second writer, and yet success had eluded them. Why had fate cursed this first talented writer so, while this second writer blissfully moved forward in a cloud of unearned notability and cash?
Leaving aside the idea that grousing about this sort of thing on social media is a form of self-soothing and this is indeed the primary purpose of doing it, let’s take the question at face value and ask: Why are some writers successful even if they aren’t “good”? Here are some answers to this, although the list is by no means exhaustive:
1. “Good” is subjective. Not everyone likes any one thing, and no one thing is for everyone. There are lots of folks who enjoy all sorts of writing, much of which is not for me, personally. But that’s fine; there’s so much writing that is for me that I will never get to read all of it (and even more that could be for me even if it doesn’t hit all my usual wants and needs for being entertained by writing). If you’re the sort of person who thinks that writing that is not for you is inherently not “good,” then the problem is you, not the writing. The writing is probably fine. You have just confused your subjective for a universal objective.
2. The work is doing what it is supposed to do, for its intended audience. When I was a film critic, I watched all sorts of movies, from grubby slasher flicks to high-toned Oscar bait. For each of these, I asked the question: “What is this film trying to do? Who is it trying to reach?” Then I judged it for how (in my own opinion, obviously) it managed to do that. I didn’t generally compare the slasher flick to the Oscar bait, because that wouldn’t be fair to either movie — they were trying for different things with different audiences. It’s not to say a film couldn’t do both (see: The Silence of the Lambs), but again, if you’re an astute enough film person, you can recognize when that’s happening and judge accordingly.
Now apply this to writing. What is the writing trying to do? Who is it for? How effectively does it address its audience? I am not much of an erotica reader (or writer!), but if I’m presented with erotica, I’m not going to judge it by the same set of criteria I’m going to judge, say, a space opera or a non-fiction biography. Each are usually doing different things, and it’s fine to acknowledge that and take the work in the space where it exists, and in the context of the audience it is for, and look at its effectiveness that way.
Related to that:
3. The work is good. Figure out how. If something is massively successful despite the fact that you don’t like it, rather than grousing about it, maybe ask: What is it that this thing is doing that makes it successful? Elvis Presley once had album titled 50 Million Elvis Fans Can’t Be Wrong. This assertion can absolutely be questioned, but the question to ask here is: What is it that gave Elvis 50 million fans in the first place? Is it something I can understand — and if I’m a musician, is it something I can learn from and maybe incorporate in my own way for my own work?
One of the things I suggest to newer writers is to read widely, even the stuff that they don’t like or don’t write, and ask: What makes this work? How does it do what it does? What can I take from that for myself? I will (probably) never write a romance book, but there’s no question that romance is hugely successful, both in itself and in hybridization with other genres (hello, romantasy!). If there’s something there I can see working and connecting with an audience, then it might be something I can use for my own writing, even if I don’t end up writing romance.
Look, things work for a reason, even if you don’t like it. Find out why and you might make it work for you.
4. Luck happens. Some people are in the right place with the right time with the right work. Some people are not. There’s not often any rhyme or reason to it, and getting mad or frustrated about it isn’t going to do one any good. Lightning in a bottle is cool when it happens, but it’s not a thing one can rely on. If it happens to you, cool. Be grateful and work to keep your good fortune rolling. If it doesn’t happen to you, keep at it. One day it might, and in the meantime you’re hopefully making good work.
5. Personas matter. The right work at the right time will go a long way for success. But other things don’t hurt! Do you have a public persona? Is it primarily one of grievance and pissiness? Surprise! That will limit your success. Do you see writing and publishing as a zero-sum game where someone else’s success takes away from your potential? That’s going to affect how you see the world, and probably not for the better. How do you do with public events, or with booksellers? If you’re good at those, that’s going to help. Are you a public bigot? Strangely enough, that will affect your reach! And so on.
There are people who think that the fact these things can have an effect on one’s career is unfair or ridiculous, and that people who can “play the game” or “schmooze” are stacking the deck or whatever. It’s fine to have that opinion, but the fact is that at every step of writing and publishing (and indeed, at every step of any creative endeavor) you’re a person dealing with people. Your work can speak for itself, but you will also speak for it. If your voice is pissy and querulous and resentful, that’s going to carry.
The runway of publishing is strewn with careers that never took off, or slammed into the tarmac, because someone was just a real fucking shithead. Now, you can have a whole career being a real fucking shithead, catering to real fucking shitheads, and some people have done just that. But let’s just say it’s the more difficult path, no matter how good your writing might be. This is especially the case in the era of social media. It used to be easier to be a shitty resentful griper because that aspect of one’s personality would be known only to a relative few. But now it can be on display to the whole world. It’s going to matter.
Conversely, if your public persona is mostly decent, you’re not resentful of the success of others, and you’re easy to work with? Guess what? All things being equal, these things are going to work in your favor. Something to think about.
So there are some answers. Again, this is not an exhaustive list. But it’s a start.
— JS
16:07
My big turn in Claude-land [Scripting News]
Hopefully this is the last big transition for a while.
I have moved Claude from my Mac Mini to my laptop, which is also my desktop.
Did it very systematically, in a recursive way.
First I asked Claude in the web browser how I should approach this. For me it was essential to put my mind outside either of the two systrems, and I believe it helped set the context for Claude/web.
From there, after coming up with a plan, I got a handoff message from C/W to C/macmini. I opened it and delivered it. And then it was a series of back and forth, looking at each project and looking for problems.
Then C/macmini gave me instructions on how to set up a new Claude app on the laptop, and there were issues, but we went back and forth with help from C/macmini on copying it Claude app from the mini to the laptop.
We're still primarily using C/macmini shouting instructions via my keyboard to C/laptop, and I send back the return, and after a few go-rounds, we're ready for the next step. I picked one of my projects, the one that's most currently my focus -- mdBrowser -- which eventually became BonBon, and asked it to run a script C/mini wrote for me, to ask it to go through tests that reveal any issues.
And that's where I am right now. About 24 hours, with of course time for daily walk in the woods, lunch, dinner, a Knicks game, sleep, coffee and a bit of courage but a lot of awe.
Also realizing that the system I'm running is still in early days. There could be higher level ways of organizing projects, in fact there already are, I haven't incorporated them yet. But this kit made a huge number of things possible that before would have been hit or miss. And the proof is still to come, did it catch all the possible problems?
15:28
[$] A new generation of futexes [LWN.net]
Futexes are a kernel subsystem that provides support for fast mutexes in user space. While futexes can indeed be fast, they are not fast enough for a number of users. Partly as a result of that, the implementation of futexes has grown in complexity over the years, with two basic variants on offer. The desire for faster futexes remains, though, and that inspires new patches, including this series from Suleiman Souhlal adding a third futex class called "futex PING" for "priority inheritance next generation".
Manjaro Project e.V. non-profit organization created [LWN.net]
Frank Vandermeiren has announced the creation of the Manjaro Project e.V., a nonprofit organization in Germany that is independent of the Manjaro GmbH & Co KG company. This is following a governance struggle that took place earlier this year between a number of Manjaro Linux contributors and Philip Müller, project lead and CEO of the Manjaro company.
At the moment, we are still working on optimizing the new development infrastructure, which was partly necessitated by the ongoing (A.I.) bot attacks against our old infrastructure.
However, as you may have noticed, the last Testing Updates and Stable Updates were initiated by the Manjaro Team without supervision from Philip Müller — with special thanks to @Yochanan for his hard work!
Dennis ten Hoove has
indicated that "a transfer of company assets to the e.V. has
not yet taken place
", and the group's next step is to ready the
nonprofit for the transition and "reach out and engage in
dialogue with the company
".
15:00
Unenumerbrated [The Daily WTF]
Submitter Valts shares an enumerated mystery:
This happened a few years ago (before COVID). A colleague called me over because he couldn't make sense of the results he was getting from some MySQL queries in MySQL Workbench. I don't remember the queries in particular, but let's say
select *
from payments where client_id=1234
showed 12 rows, all having thesuccessfulfield set to1. But when you selectedselect count(*) from payments where client_id=1234 and successful=1you got back0rows. And this was reproducible on my machine, too. Yet in code similar queries worked just fine.After a lot of head-scratching and increasingly bizarre hypotheses, we finally figured out what was going on. In the far, far past, in dark days gone by, someone had defined the database field as
enum('0', '1'). This SEEMS pretty rational ... until you start reading up how MySQL treats enums. Enums, it turns out, are all STRING values. But in queries you can use either their string values, or their integer indices, starting at 1. So in this case, the string "0" has the integer index of "1", and the string "1" has the integer index of "2". Soselect * from payments where successful='1'is quite different fromselect * from payments where successful=1.For extra confusion, under most other circumstances MySQL normally silently converts between strings and integers as needed. Some ORM/QueryBuilder frameworks even simply quote ALL values and let MySQL handle the conversions.
Facepalms were had.
In the aftermath, I blame the person who defined this field more than I blame MySQL for its bizzare enum conventions. If you're doing enums (which are generally a good thing), then give them proper names like
successfulandunsuccessfulor something. Not0and1.This code and this database table is still in use today, but luckily it's the only such gotcha in the entire system. Enums in the database are scarce and the rest of them are sane.
[Advertisement] Keep all your packages and Docker containers in one
place, scan for vulnerabilities, and control who can access
different feeds. ProGet installs in minutes and has a powerful free
version with a lot of great features that you can upgrade when
ready.Learn
more.14:42
Security updates for Monday [LWN.net]
Security updates have been issued by Debian (freedombox, kernel, libspreadsheet-xlsx-perl, network-manager-iodine, pdns-recursor, postgresql-15, radsecproxy, and sogo), Fedora (afflib, asahi-installer, below, cloc, dhcpcd, dnf5, epiphany, firefox, glib-networking, hugo, mingw-python3, mtools, mysql8.4, mysql9.7, proftpd, python-cramjam, python-fastar, python-h5io, python-PyMuPDF, python-uv-build, radicale, rubygem-loofah, rubygem-nokogiri, rust-archive-trait, rust-askalono-cli, rust-astral-html, rust-cargo-deny, rust-libcramjam0.8, rust-onefetch, rust-ptools, rust-sccache, rustup, uv, and xorg-x11-server), Gentoo (Apache HTTPD, rsync, and Tor), Oracle (cockpit, firefox, grafana, grafana-pcp, gstreamer1, gstreamer1-plugins-base, kernel, kernel-uek, mingw-libpng, nginx:1.24, perl-CGI, python3, qt5-qtbase, qt5-qtdeclarative, webkit2gtk3, xfsprogs, and xorg-x11-server), and SUSE (389-ds, aliyun-cli, amazon-ssm-agent, apache2, binutils, brotli, bun, cadvisor, chromium, gn, distribution-registry, evolution, firefox, firefox-esr, fleet-cli, fortio, gosec, hauler, hawk-apiserver, hawk2, helmsman, hugo, java-17-openjdk, jsoup, k3sup, kdeconnect-kde, kernel, krb5, kubectl-retina, kubelogin, kubeseal, kumactl, libosmocore, libyang-devel, patch, perl-mozilla-ca, pinact, prometheus-ha_cluster_exporter, python-brotli, python-graphql-core, python-Pillow, python313-Brotli, python313-pypdf, python313-uv, rqlite, rsyslog, scribus, sdbootutil-1, timoni, trivy, vifm, and warewulf4).
12:35
Fun with e-paper [RevK®'s ramblings]

The project involves a small PCB, and a carefully designed 3D printed case. The display actually comes with some adhesive tape even, so it sticks to the case design.
I then include a 13.7Wh LiPo battery. It includes a recharge circuit to charge from USB.
The board includes an RTC chip, which uses 160nA. This has alarm settings and a button trigger as well. It can then wake the main CPU (ESP32-S3).
I have opted not to use the ESP32 deep sleep mode for this - by shutting down the whole processor the idle power consumption really is very low. The concept is simple - it wakes up periodically, say every 5 mins, checks for new data, and if no new data it goes back to sleep.

It is complicated to get this check and sleep process down to a minimum time, but I have managed to get it to a typical 850ms.
- Fast boot loader, not checking the image integrity (this does get checked in the event of a crash, and will switch to other image if corrupt).
- Not running a PSRAM memory check.
- Not logging boot loader to serial.
- Caching the channel and BSSID for WiFi connect.
- Caching the IP, mask, gateway and DNS for IP connect.
- Fetching a page via http not https (https adds 2s).
The caching uses the RAM and EEPROM in the RTC, and sadly not quite enough space to cache IPv6 - though I may be able to squeeze in for simple SLAAC and zero router address perhaps. One to consider.
So yes, some compromises here, but 850ms is really short.

To try and get some idea of the battery life I have set one of these up using a tiny 0.9Wh LiPo.
The ADC is not ideal, and estimating battery capacity is always fun. It has been reading capacities around 85% and actually going up and down a bit.
Over the last week it has gone from as high as 87% to 83% for my estimates.
So a crude estimate is that if it has used less than 5% in a week, the 0.9Wh could last 20 weeks? This would mean the 13.7Wh could last 5 years!
Yes, this is a wild estimate - it depends a lot on usage, and a LiPo will have some internal discharge as well. What I think I can confidently say is my original goal of 1 year battery life should easily be achievable. Ideally I want to do a full charge to flat test on the 0.9Wh to get a clearer idea.
12:21
Usable Security at Luxury Hotels [Schneier on Security]
Interesting case study from luxury hotels. Attackers used a fake booking request to gain access to a reservations inbox, where they copied genuine refund requests and got fraudulent ones approved.
This is a good illustration why “just don’t click on links” is bad advice. It can’t work when answering strangers’ emails is the job. Even worse, in this case the guest-first culture punishes hesitation. More interesting, the case study shows that splitting security between owner, operator, and brand leaves nobody accountable. And this is exactly the setting where blaming staff becomes the convenient answer.
My Super Mid-Life Crisis – Issue 1 – 14 [Comics Archive - Spinnyverse]
The post My Super Mid-Life Crisis – Issue 1 – 14 appeared first on Spinnyverse.
11:28
Grrl Power #1513 – 1st through 512th place loser’s box [Grrl Power]
I know, I know. I almost definitely got the possessive plural wrong there in the first panel. I had considered “Runner‘s Up” and even “Runner Up‘s.” I’m not actually certain if possessive plural requires multiple posessees or multiple possessions. Maybe it’s both? Like you’d only write “…the childrens‘ toys…” if there were multiple children and multiple toys? In which case, “Runner Ups‘” implies multiple Runners Up and multiple boxes set aside for them, which is actually the case, as the Runners Up are segregated by their original matchups, because any other state of affairs would have me drawing a room with like 512 people from all the quarterfinal matches on up (minus the ones that couldn’t attend due to grievous death syndrome) or drawing a room full of 4-6 people, only one of which was a character you’d recognize, because the rest are from matches that we never saw.
Granted, you never saw U.M.B.Rage’s pilot, so I could have just put arrows explaining who everyone was like I did for him. BTW, when I say “pilot,” I mean like in the James Cameron’s Avatar sort of pilot. That dude was plugged into a cybernetic gaming chair somewhere within about 1,000 kilometers of the match, piloting that big mauve kaiju. Mt. Atrocitous is sitting in a huge dry dock somewhere with several massive cranes, having the top of his head magma-welded back on, but he can grow little crystal offshoots and remote pilot and sense through them. That’s also quite Avatar-ish, but that ability is built into Atrocitous, and he can do about a dozen at a time if he wants.
Maybe it’s just me, but every time I look at the Atrocitous avatar, I think, “Aaaaay, guy! Did you just fuck your uncle?” (I’m saying Mt. Atrocitous is Canadian.)
Oh, and I won’t spoil who is off panel speculating in the last panel there, but I promise you will be underwhelmed.
 Here you go, a brand new vote incentive. Featuring the least sexy character in
the comic. No, I take that back, Cooter is the least sexy, but
don’t expect a pinup of him anytime soon. Or ever. There is a nude version over at
Patreon. Note I didn’t say NSFW. She is nude in those
picture, and she does identify as female, but it’s…
hard to tell. She is a humanoid aberration by D&D terminology,
not a mammal. And before you ask, no, I don’t know how many
vertebrae she has in her neck.
Double res version will be posted over at Patreon. Feel free to contribute as much as you like.
10:07
Practical empathy [Seth's Blog]
I don’t know what you know. I don’t want what you want, see what you see, believe what you believe.
And that’s okay.
In fact, it’s the only way to be of service, to make a sale or to cause a change to happen.
Of course, we’re more intimate with our ideas, our products and our approach than anyone else. We have a noise in our head, a narrative and a point of view we’ve spent our whole lives creating. It’s naive to believe that anyone else is completely in sync with us.
And so, our only opportunity is to go where they are, not to demand that they come to us.
Practical empathy isn’t primarily an act of kindness (though it’s an essential component of kindness.) Instead, it’s a direct and straightforward path from here to there. It’s how we create action, learning and change.
Marketing is the simple and brave act of going to where someone else might be, and helping them get to where they hope to go.
09:28
Kernel prepatch 7.4-rc3 [LWN.net]
The 7.4-rc3
kernel prepatch is out for testing. Linus declared: "It looks
fairly normal, with drivers (networking and gpu) leading the
charge. There's lots and lots of changes, but most of the actual
patches are tiny.
"
09:07
New Comic: Son Of Lar
06:49
Separable [Cory Doctorow's craphound.com]

This week on my podcast, I read Separable, a recent essay from my Pluralistic blog about the way that AI confounds our intuitions about the meaning of images, words, and mathematics.
Long before the Turing Test, there was the touring Edison Test: from 1915 to 1925, the scoundrel Thomas Edison put on a traveling show for his phonograph machine, touring venues around the USA. Edison set live performers and an Edison phonograph playing behind closed curtains that would be periodically pulled aside to reveal that the music the audience had taken to be live performance was actually a record player:
Now, if you’ve ever heard an Edison phonograph, this might seem like yet another tale in which old-timey people are revealed to be credulous yokels. You would never mistake one of those scratchy, hissing recordings for a live performance:
And indeed you wouldn’t, but not because the phonograph predates the evolution of the human brain’s anti-credulity lobe. The reason old-timey people couldn’t tell the difference between a phonograph and a live performance was that before the phonograph, every live performance had a performer.
The two were inseparable, and so when you encountered the sound of a musical performance, your brain would insist that there must be a performer as well.
06:07
Girl Genius for Monday, November 16, 2026 [Girl Genius]
The Girl Genius comic for Monday, November 16, 2026 has been posted.
04:35
Russell Coker: After the AI Bust [Planet Debian]
The Crash
Charles Stross wrote an interesting blog post about the latest developments in the AI bubble [1]. He predicts the imminent burst of the AI bubble because of Jensen Huang’s out of control dick. The bubble was caused by out of control dicks (figuratively speaking) and now may be burst by an out of control dick (both literally and figuratively speaking).
The end result of the “AI” related financial schemes is going to involve more than a few bankruptcies.
The Rebuild
I previously blogged about the fuss about AI [2] and concluded that the bust would be like the dot-com bust which paved the way for new profitable Internet developments. I am less positive towards the AI bubble now as it has gone a lot further than the dot-com bubble. The bankruptcies won’t just affect the IT industry, a lot of money from pension funds and index tracker funds has gone into “AI” and the pain will be spread around.
But I am confident that after the crash there will be new and interesting developments in Machine Learning (ML) technology that will benefit people. The Data Centers (DCs) that have been built at great expense will continue to be run and their services will for a while be offered at slightly above the cost of maintenance and power.
A lot of home users (Free Software developers) who can’t afford a GPU with 16G of RAM will find themselves able to rent time on systems with 48G or 96G of GPU compute to experiment with LLMs. Most such experiments won’t achieve any useful output, but if someone can spend a few dollars and learn useful things about software engineering then that’s a win for society. Also I think there will be some useful products developed as a result of this. The people who came of age when Linux was first released are now in their 50s and tend to have the reduction in vision and hearing expected in that age range so we can hope for some good developments in assistive technologies based on the cheap hardware.
The current situation is that renting time on ML servers is cheap and often free while renting time on virtual servers with GPU access is expensive ($2 per hour for a not particularly high end VM) so people are learning how to use (or misuse) services like ChatGPT and not learning how to run their own LLM service and understand how it works. The future situation will involve renting VMs available for not much more than the cost of electricity at off-peak times and services like ChatGPT will need to have an operational profit so running your own LLM on rented hardware or hardware you own will be a better option.
While corporate web sites are known for having rubbish chatbots using proprietary backend systems. While most of them suck badly and the idea of using them to replace staff is a really bad one the concept could work. If we increased the knowledge of such technology in the entire industry and if management was prepared to pay for it via increased budget for service improvements instead of trying to cut staff costs then it could give a good result.
Other Computer Hardware
The market for RAM for enterprise GPUs has been strong which reduced supply for consumer grade hardware. This caused prices to become unreasonably high.
There’s a general trend of software becoming bigger. Computers get bigger screens so media sources need higher resolution content which drives the demand for more storage and RAM for buffering things. Computers get more hardware features and more devices to connect to so all the software needs to be able to communicate with them. This makes the software bigger for everyone even people who aren’t using the features. For example adapting the audio subsystem to deal with different Bluetooth devices with options for different encodings increases the memory requirements for all the computers that have audio hardware but don’t have Bluetooth hardware. Perfectly reasonable decisions that make things work better for many people can have downsides for other people. RAM is one area that seems to have been repeatedly the subject of design trade-offs that resulted in systems with 16G of RAM performing the same tasks that systems with 16M of RAM did in the mid 90s but just at a higher resolution and with more features. The ongoing increase of RAM use by software combined with high prices caused by the “AI” companies has been bad for consumers.
The PC RAM use issue isn’t going to end. When I started editing the Debian Wiki page about Mobile Apps [3] I added a field for typical RSS of apps. Phones never have an option to increase RAM and the RAM is always limited. The largest RAM in commonly available phones in English speaking countries is 16G for the Pixel 11 Pro and the largest RAM for open Linux phones is 8G. When even relatively simple apps like an eBook reader take 500M of RAM it’s obvious that 8G isn’t enough.
The phone and laptop design process is based on a cycle of about one year, so maybe 8 months after the AI crash we will see ultralight laptops with 64G of soldered RAM and phones like the Pixel 12 Pro with 32G of RAM. Looking at Officeworks (the chain store for cheap office supplies including laptops) the vast majority on sale currently have 16G or less and 16G of RAM performs really badly for Windows and has performance problems for heavy use on Linux. It would be nice if the minimum RAM for a laptop was 16G and it was a common and affordable option to have 32G or more and that is a likely result of the AI crash.
Single Board Computers (SBCs) are currently expensive with reasonable amounts of RAM, when RAM prices drop significantly it will enable more uses of them for replacing desktop PCs and for developing other products. The Humane AI Pin [4] was an interesting research project but a poorly managed product, it would be interesting to have some free software research into that space and cheap SBCs with lots of RAM will facilitate it.
Employment
I expect that a lot of IT people will be looking for work in California soon. But for most of the world I don’t think it will change much. Cheaper hardware decreases the cost of starting IT businesses but a market crash decreases confidence in investing in the sector. Maybe there will be an increase in startups and small companies, including small companies based around LLM operation. I don’t expect any sort of catastrophic decrease in IT employment.
Also a CEO sleeping with employees at his company creates a bad working environment, that sort of thing should be stopped. Sacking a CEO for such misbehaviour is a good thing even without all the financial fraud and possibly breaking laws about exports.
Conclusion
The sooner the crash happens the better things will be for everyone. As this bubble goes on the impending financial damage increases and the upsides of the crash are delayed.
02:42
or a defibrillator
Sunday, 15 November
23:56
And here my friends, is the app. We now have a public file Markdown editor hosted by ChatGPT and designed by me. It's really cheesy and funky, but that's good, because no one will confuse it with beautiful software. If you have a Markdown editor that can publish, so it can publish Markdown files, let me know.
KDE will now load XWayland on demand [OSnews]
When running KDE, the X11 compatibility layer for Wayland, XWayland, always runs, even if there isn’t anything on the system still requiring the legacy X server to work. In the next step towards a Wayland-only world, the KDE people have reached a major milestone: XWayland now only runs when actually needed.
This week a significant technical milestone was achieved: the XWayland compatibility layer is now loaded only when needed. Previously it had always been running even when no apps were using it, and fixing this required porting various system services away from legacy X11 code paths. This work was done by Vlad Zahorodnii, David Edmundson, and David Redondo, and will ship in Plasma 6.9.
↫ Nate Graham
This frees up some system resources, which is always a welcome improvement. I do wonder how this might impact the load times of legacy X applications, but I have a feeling it’s close to immeasurable.
Redox gets Go, GIMP, and more [OSnews]
I love and admire the Redox project, but their insistence on fudging the publication dates of their monthly progress reports really bothers me, for some reason. No, I’m not 16 days late – the report covering October was published only yesterday evening, and not on 31 October as the website claims. None of this matters to anyone but weird people such as myself, but I still want to get it off my chest. Don’t bother any Redox people about this.
Anyway, the big news for the month of October is the port of the official Go programming language compiler, allowing for cross-compilation and self-hosted compilation using relibc. Another major port also made its way to Redox in October: GIMP now runs on Redox, using the Orbital backend of the GTK port. The work to make Redox compatible with Cloud Hypervisor is also complete, with more information in its own dedicated article. Video playback in WebKitGTK3 has been fixed as well, and even YouTube works now which is quite neat.
There’s a ton more in this report, like an updated Servo port, NUMA support has been tested on real hardware for the first time and seems to work, work on rootless package installation has begun, and much more.
Disk encryption on NetBSD: achieving secrecy [OSnews]
NetBSD developer Nia Alarie has written a guide on how to set up a NetBSD system with disk encryption that’s quite useful for those of us who deeply care about such a level of security. On top of that, the guide is also interesting if you just want to learn a bit more about how NetBSD works.
These are two threat models for which disk encryption is the answer:
- The device is stolen or lost and its contents must remain secret.
- The device is tampered with, and all attempts at tampering must render it unusable.
Right now, we will focus on the first threat model. It is very difficult to build a tamper-proof system, and you need to worry about tamper-proofing your hardware, depending on what kind of actor is a realistic threat.
↫ Nia Alarie
The guide is written for sparc64, but should work on more mainstream architectures just as well. A guide written by a NetBSD developer is obviously going to employ some exotic or weird hardware. As is tradition.
23:07
ChatGPT Sites is a thing. Exploring it now. "Here's what I want, wonder if you can do it. I want to write markdown files and publish them somewhere where they can be accessed over the web, not as rendered files, but in markdown source. It should be really simple to use. Couldn't hurt if there was an RSS 2.0 feed, and it would be nice if i could make it something I could share with others so they can write url-accessible markdown files too." Update: It gave me what I asked for. It's funky, for sure, but it seems to do it. Example.
My project for today has been to move my Claude work from a Mac Mini to my PowerBook. I think it should be on one machine that I can move around with. Learning a lot, reviewing all my projects in advance of the move, and getting the PowerBook ready for it.
20:00
Creating a self-booting ZIP archive [OSnews]
Linux initramfs supports unpacking CPIO, a stupid, simple, standardized format. In the discussion on whether to support TAR instead, much emphasize has been put on the fact that CPIO is standardized and less fragmented. Luckily, Linux (the kernel) includes its own tool to produce the specific variant of the standard that it happens to implement. The standard CPIO tool is possibly the most cursed archiver under the SUN.
In the old DOS/WinDOS world, ZIP was probably the most widespread and well-known archive format, being displaced to some extent by the rise of RAR during the 2000s.
Because of the design of the format, ZIP lends itself to all kinds of polyglot trickery. Way back when, self extracting ZIP archives where a thing, EXE/ZIP polyglots that can be run and unpack themselves, which is useful if you don’t have an archiver installed.
I don’t think I need to explain where I am going with this.
↫ David Oberhollenzer
This is lovingly cursed.
17:28
Big Grey Has Big Problems [Whatever]
I’m sure you’ve all been patiently waiting for an update on Big Grey, so I won’t keep you in suspense any longer! Here’s his joyous expression on the way to the vet:

I ended up taking Big Grey to Acute Pet Urgent Care in
Beavercreek, and I told them ahead of time that it’s safe to
assume that anything that could possibly be wrong with this cat is
probably, indeed, wrong with this cat.
And boy was I right! This guy has the works; fleas, earmites, malnutrition, upper respiratory infection, dental disease, heart murmur, and leukemia. And possibly asthma. Also it turns out that ol’ Grey here is an older gentleman, estimated to be around 7-10.
Shaved, flea medicated, injected with antibiotics, he got the full treatment. The vet also said he will more than likely need all of his teeth pulled, he has huge masses in his mouth that are full of pus. Needless to say, this guy has been through the wringer. But at least the vet gave him these stickers:

Big Grey is curled up in a corner still entirely petrified. He eats his food when I’m not looking and uses the litterbox, too, but I have genuinely not seen him move a single muscle or heard him make a single noise at all. He is just a gargoyle in the corner, shaved and sad.
So, yeah, things are still pretty rough but I can only hope he’s a least feeling a little better with all those mats off him, and hopefully the antibiotics are running their course through his immunocompromised system. I just want him to be happy, and he seems so very not happy right now. I just want to help him and love him and he’s completely terrified of me. Sigh.
Anyways, he still needs fixed, and eventually will need dental work. But for now he can just rest while the medicine soaks in. I won’t stop stepping up to the plate for this guy.
Also, shoutout to Acute Pet for handling Big Grey with so much care and compassion. Everyone there was very friendly and the doctor went over everything in immense detail and let me ask as many questions as I wanted. I didn’t feel rushed or confused about anything they were doing throughout the entire process, and it was clear that they really were rooting for this little guy. As we all are.
-AMS

16:14
[Filler] under the weather [Twokinds]
Comic for November 15, 2026
15:28
I live in nature, and around this time every year a mouse family moves in to ride out the winter. Year after year I try to make noise when I hear them scratching to start their nests in the walls of the house. It doesn't always work, and I get a really sore hand from all the wall-banging. But after cleaning out last year's poop and food-filled nest in the linen closet, I had a neat idea that appears to be working. I have a nice JBL super size speaker for outdoor music listening in the summer. I put it on the top shelf of the closet and Bluetooth connected it to my phone with the volume turned up really high. It seems to work. The clawing stops and every time it comes back I turn the music on again. I get to listen to vintage Aretha, Tina Turner, a little James Taylor and Little Feat for good measure. I'm sure they would like the music if it weren't blasting so loud in their bedroom. They can find another place to nest this winter. I would prefer to keep the mouse poop out of the towels and bedsheets.
13:49
Russell Coker: The Cutlery Thief [Planet Debian]
A few years ago the kitchen of the company I worked for suddenly had no soup spoons or dessert spoons. One day there was about 40 in the drawer and the next day there was none, to the great annoyance of everyone who ate breakfast cereal, soup, and similar food at the office. Someone had stolen about 20 dessert spoons and about 20 soup spoons while apparently not stealing tea spoons, knives, or forks.
For a while I kept my own soup spoon in a locked desk drawer, but that was a hassle. After a couple of months of unsuccessfully lobbying management to buy more spoons I went to an op-shop (thrift-shop for American readers) and bought most of the soup spoons and dessert spoons they had and donated them to the office. After that everything was good for about a week until all the regular knives were stolen. They didn’t steal carving knives or bread knives, just the type of knife you would use to eat dinner or make a Vegemite sandwich.
After the knife theft management agreed to buy new knives.
Not long after that the company had financial issues and I was laid off, so I don’t know whether the forks ended up being stolen later on. If the cutlery thief wasn’t among the people laid off then I’m sure a fork heist happened sooner or later.
I remain mystified as to why someone would want to steal cutlery. The security around laptops wasn’t great and walking out of the office with a laptop would look much less suspicious than walking out with a bag of spoons or knives. One would expect that stealing a laptop and selling it to buy cutlery would be a better option.
If anyone who lives in my area wondered why their local op-shop had a sudden lack of spoons, I’m sorry that I don’t have a satisfying answer for you, just many more questions.
10:28
Confusion about causation [Seth's Blog]
It’s not difficult to develop an incorrect theory. Ice cream and spaghetti have more letters than tofu and celery, so therefore, foods with long names are more fattening than those with short ones.
If you start moving forward with this theory, you’ll soon find outliers. Sugar only has five letters, and watercress has ten. If we want to stick with our theory, we’ll have to come up with more and more complex reasons why we ignore some of the data and embrace the rest.
Of course, this is absurd.
And yet we do it all the time. Ornate explanations about the stock market, SEO or politics. Charts and graphs where we spend most of our time fitting a plot to a few dots, or amplifying the obscure to justify the theory.
A simple theory that matches the data is much more likely to accurately explain causation. It might not be a comfortable theory, or one that matches our trajectory, but it’s a better theory.
It turns out that the number of letters is completely irrelevant to how fattening a food is. I’m sorry you spent all this time on research, but you’re on the wrong path.
If you want to know why your marketing, your investments or your arguments are floundering, it might pay to reconsider the theory, not look for more data to justify the current one.
Saturday, 14 November
19:42
All the inline images on Scripting News back to the beginning of inline images.
18:14
My first impulse to create a new web based on Markdown was
to get around the tech industry which now unambiguously claimed to
be the owner of what we've come to think of as the web. But it
turns out the impulse was totally correct, even if they hadn't done
what they did, it was still a good idea, and long overdue. Thank
Claude for this too, because without Claude it would have remained
an idea. It gave me the power to do it, in an incredibly short
period of time.
And btw, the tech industry should help me. Mike Arrington said one day they would erect a statue of me in Palo Alto or San Jose. I told him it'll never happen because I knew how tight the Silicon Valley club was. I was on the edge of it for many years, and for brief periods I was inside. He saw me at the peak. But their model and mine were radically different. I saw software as an individual thing, that it's like making a movie, and you need various skills, and we all work together, and make something great out of cooperation. That's what the web calls us to do. They just fucked it up so bad that The Web isn't the web any longer. No problem, we'll make a new one.
I don't do a lot of editing of my writing these days. I can see that, but I'm all over the place with the release of BonBon, which is now apparently a few days away.
17:35
Upcoming Speaking Engagements [Schneier on Security]
This is a current list of where and when I am scheduled to speak:
- I’m speaking at the Catalyst Summit in Brampton, Ontario, Canada, on Wednesday, November 18, 2026.
- I’m speaking at QT Qonference 2026 in Toronto, Ontario, Canada, on Thursday, November 19, 2026.
The list is maintained on this page.
17:28
Good morning sports fans! This is a test post. And this is the test.
10:28
Have your AI call my AI [Seth's Blog]
Sharp lawyers have often used the fine print to win an advantage in a contract. It’s called the fine print for a reason–you’re not supposed to read it. But you should.
Now, armed with AI, it’s significantly easier to bury arcane, unfair or unanticipated clauses in agreements, even (and especially) if we don’t expect it.
You shouldn’t sign anything until you’ve had your AI read it. And if it’s important, have your lawyer and her AI read it too.
The next step seems reasonable to me: You and I describe our agreement in plain English and then our mutual AI’s work out a written agreement that actually captures what we’ve agreed on. And for the avoidance of doubt, append each AI’s interpretation to the contract itself.
It shouldn’t be confrontational or adversarial. After all, it’s an agreement.
09:35
The Circus is Leaving Town [Charlie's Diary]
I am in Madrid, listening to an unexpected deluge of rain and waiting to go to my next panel at Sui Generis, the literary festival I'm here for, and I gather that on the other side of the Atlantic the sky is falling. (Also, I haven't blogged for nearly three weeks, I've been forcibly refusing to work on the novel--I don't do that while I'm travelling--and the urge to write is now making my back teeth itch. Hence, this.)
So: while I'm away from the office the music stopped, and Jensen Huang was caught out between two chairs, or mistresses, and now he's allegedly got the Wall Street Journal on his case. I say allegedly because the WSJ is paywalled to fuck, but Techpowerup is covering their exposé and, yup, it's about what everyone expected. Gosh, you wait forever for an Ed Zitron then three of them in a trench coat come along and swipe his lede: but one thing is certain, when the major oligarch-owned outlets start Pointing The Finger Of Blame, it means the steam caliope has sprung a leak, the mesmerizing tune has sounded a bum note, and the big tent is deflating:
The WSJ report cites an August meeting between Huang and his senior finance team, including NVIDIA's CFO and acting CEO, Colette Kress, during which Kress pushed for a reduction in circular financing agreements, in response to which Huang allegedly lay into Kress, calling her a "deer in the headlights," after she had pushed to scale back NVIDIA's $250 billion deal with OpenAI. Jensen's push for further investment into small-scale cloud providers was seemingly in response to the changing tide that saw AI hyperscalers move away from off-the-shelf components in favor of custom solutions.
The situation described in the report saw NVIDIA on the hook for an "avalanche" of GPUs from TSMC, for which it would have no immediate buyers. Part of the issue highlighted by Kress was also that these small-scale cloud providers NVIDIA was investing in could not afford to buy NVIDIA GPUs, meaning they, too, could be a financial dead end.
This isn't about the reality or otherwise of "AI" as a thing rather than a marketing bullshit term, it's about stock fraud that Donald J. Trump is up to his elbows in. (Where we read about $5M in share purchases in The Guardian, you can bet there was another 10-100x that amount of money in play among his courtiers because that's how mob families run.) Trump's involvement is probably why it took so long to burst, but Huang is a convenient scapegoat--look, he isn't even white enough to pass the Stephen Miller scratch'n'sniff test!-so they're going to try to pin it all on him at first, but there's so much shit in this overflowing midden that the landslide is going to take out an entire class. (I think you know some of their names, but there will be surprises as well: how many Senators and House committee chairs have clean hands?)
So. Where does it go from here?
04:28
New Cover: “A Little Respect” [Whatever]
In which I ask the question: What if Erasure… but punk? Then it might sound a little bit like this fast and dirty version of the song I banged out tonight, just for fun. I will not be replacing Andy Bell any time soon, but then, punk is not about perfection, it’s about doing everything really fast.
(In fact, that’s not what punk’s really about, but shush.)
Anyway, I had fun. Maybe you’ll enjoy it too.
— JS
00:28
Junichi Uekawa: Time flies so fast. [Planet Debian]
 Time flies so fast. It's November. Busiest time of the
year?
00:07
Claims about touch screen voting machines [Richard Stallman's Political Notes]
Claims are circulating about touch screen voting machines that change the vote that the user has already entered. Experts say that those machines are not rigged, but are prone to being hypersensitive, such that slight touches can confuse them.
Members of Congress with investments in Putative Intelligence [Richard Stallman's Political Notes]
Over 1/5 of the members of Congress (or their close family) has substantial investments in Putative Intelligence.
Quite a few have investments in building data centers.
Windfall profits of oil companies [Richard Stallman's Political Notes]
The windfall profits of nine giant oil companies over three recent months add up to almost a hundred billion dollars.
In the 1970s, when the oil price spiked because of an OPEC production cut, the US Congress imposed a windfall profits tax on oil companies. If it doesn't do likewise now, that is a measure of how the political influence of the oil companies has become dangerous.
Countries that emit less than 1% of greenhouse emissions [Richard Stallman's Political Notes]
Countries that emit less than 1% of the world's greenhouse gas emissions are not negligible — they add up to almost 1/3 of the total emissions.
Thus, the argument that emitting less than 1% is an excuse for the country to do nothing to reduce its emissions is a bogus excuse.
Uyghur refugees who fled to Thailand [Richard Stallman's Political Notes]
China has ordered Thailand to deport to China some Uyghur refugees who fled China and criticize China for persecuting Uyghurs. Thailand is so completely under China's thumb that it intends to obey that order even though these refugees have been offered asylum in Canada, which ought to be safe.
Shame on you, Thailand!
Bill that would deregulate environmentally destructive projects [Richard Stallman's Political Notes]
*Public Citizen calls on Congress to reject the "compromise" bill that would deregulate many environmentally destructive industrial projects.
Suspicion of brutal confrontation with Congress [Richard Stallman's Political Notes]
Suspicion that the saboteur in chief may seek a brutal confrontation with Congress.
Holding investigations is not the only way that Democrats in Congress can oppose him. There will continue to be must-pass bills into which they could insert provisions that would help the country and non-rich, but that he would oppose. The saboteur in chief would veto the bills; then what? Will Democrats be determined enough to out-stubborn him?
I suggest that they respond by doubling down: pass another version of the bill, adding a few more good provisions that he would oppose. And repeat this until he cracks.
"Corporate" (plutocratist) Democrats will be the weak link.
Tangible outcome of emissions cuts people can see [Richard Stallman's Political Notes]
*Australia's climate and energy minister and president of negotiations for Cop31: "We need a tangible outcome focused on implementation [of emissions cuts and finance] that people can see is real."*
Hunger and obesity as closely related problems [Richard Stallman's Political Notes]
Proposing that governments consider hunger and obesity as closely related problems. The same policies can cause both.
Rule of Law Project [Richard Stallman's Political Notes]
The Rule of Law Project will prepare criminal cases against the perpetrators who have carried out crimes for the corrupter/persecutor.
The cases will be available to be used by whichever country has the opportunity and courage to prosecute those perpetrators.
Democrats have to take on billionaire class [Richard Stallman's Political Notes]
Naomi Klein: If Democrats want to keep the blue wave going into 2028, they have to take on the billionaire class.
China's lead on green energy [Richard Stallman's Political Notes]
*US and rest of world must follow China's lead on green energy.*
Jamestown inundated by rising Atlantic [Richard Stallman's Political Notes]
Jamestown is slowly but steadily being inundated by the rising Atlantic Ocean, due to global heating.
Friday, 13 November
23:42
Mike Gabriel: Debian Edu 13 - Call for Testing [Planet Debian]

The upcoming Debian 13.8 point release will be the foundation of the first release of Debian Edu 13.
This is a call for testing, we are interested in your feedback.
How To Prepare
- Download the Debian Edu 13.7.0 BD ISO Image (beware, ~17GiB) [1]
- Tweak the BD ISO image [2] and add support for packages in trixie-proposed-updates [3]
How To Test
- Use virt-manager
- Prepare an internal 'edu' network and another internal 'thinclient' network
- Prepare three VMs:
- gateway:
- Attach one network adapter to the Default/NAT network of libvirt
- attach the other network adapter to the internal 'edu' network
- Install a Debian 13 minimal system, install the 'debian-edu-router-config' package and follow the debconf (many!) dialogs to configure the system (see [4] for additional info)
- tjener (Main-Server):
- RAM: 4-8GiB, CPU Cores 2-4 (or more)
- Provide 80GiB (or more) of storage (to be flexible with LTSP setups)
- Attach primary network adapter to the internal 'edu' network
- attach the second network adapter to the internal 'thinclient' network
- Install the Main-server from your self-created debian-edu-13.7.0-amd64-BD-1-withPU.iso (see [2])
- Install profiles Main-Server, LTSP-Server and Workstation (menu shown in Debian (Edu) Installer)
- workstation:
- needs ~40GiB of disk storage, 4GiB RAM, 2 (or more) CPU cores
- boot over PXE on the internal 'edu' network
- test runs:
- boot as Diskless Workstation
- boot as X2Go Thin Client
- install a Debian Edu system to disk
- gateway:
Known Issues
See our Debian Edu 13 status page on the Debian Wiki:
https://wiki.debian.org/DebianEdu/Status/Trixie
More Info
Debian Edu comes with the Debian Edu manual, it can be found
at:
https://jenkins.debian.net/userContent/debian-edu-doc/debian-edu-doc-en/...
Where to Report Findings
Please either directly submit bugs to Debian's bug tracker
(package: debian-edu-config); talk to us on IRC
#debian-edu on irc.debian.org or write to
the Debian Edu mailing list.
References
[1]
https://cdimage.debian.org/debian-cd/current/amd64/iso-bd/debian-edu-13....
[2]
https://wiki.debian.org/DebianEdu/HowTo/TestInstallVirtualMachine#Varian...
[3] https://release.debian.org/proposed-updates/stable.html
[4]
https://jenkins.debian.net/userContent/debian-edu-doc/debian-edu-doc-en/...
MenuetOS keeps steadily improving [OSnews]
MenuetOS, the operating system written in x86-64 assembly, has seen a few new releases since we last looked at it, delivering some welcome improvements. Secure network connections are now faster, there’s a TrueType font demo, and, of course, the usual bugfixes and smaller improvements. The game Wizord EXL100 has been ported, and a few drivers have been improved as well.
You can get the latest releases from the downloads page.
22:21
Writing is so important it deserves its own web.
There's a recursive effect of the election on the voters. We didn't know there would be so many of us. Ask us again what we want done with this power now that we understand how much more united we are than we thought.
22:07
Reproducible Builds: Reproducible Builds in October 2026 [Planet Debian]
Welcome to the October 2026 report from the Reproducible Builds project!
In our reports, we try to outline the most important things that we have been up to over the past month. As a quick recap about what problem our project intends to solve, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries. The motivation behind the reproducible builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third parties to come to a consensus on whether a build was compromised or not.
As ever, if you are interested in contributing to the project, please visit our Contribute page on our website.
In this month’s report, we cover:
- GNU tar ‘sparse archive’ non-determinism reported
- Reproducible Builds at SeaGL 2026
- Tool and documentation development
- Distribution work
-
SOURCE_DATE_EPOCHspecification updates - Mailing list news
- Patches
GNU tar ‘sparse archive’ non-determinism reported
Johannes Schauer Marin Rodrigues (josch) reported
an issue to the GNU tar mailing list where creating
PAX-format sparse tar archives produces unreproducible outputs.
Specifically, when GNU tar generates a PAX archive
containing a sparse file it embeds the process ID into the member
filename path structure (e.g. ./GNUSparseFile.<pid>/<filename>).
Because process IDs vary between build runs, however, archiving
identical sparse input files yields different binary outputs.
In his report, Johannes outlined potential workarounds, such as
running tar inside an unshared PID namespace where the
process ID is pinned to 1, and proposed that
GNU tar either omit the PID by default or provide a
command-line flag to suppress it. Full details can be found in the
post
itself, and Johannes also filed the bug in Debian for
completeness.
Reproducible Builds at SeaGL 2026
Reproducible Builds was present at SeaGL in Seattle, WA, on October 23rd & 24th. Thanks to everyone who attended and spoke with us!
Members of the Reproducible Builds project attended SeaGL (the Seattle GNU/Linux Conference) in Seattle, WA, on October 23rd & 24th. It was a fantastic opportunity to connect with local community members, discuss software supply chain security and share updates on build verification tooling. Thanks to everyone who stopped by our sessions or spoke with us during the event.
Founded in 2013, SeaGL is an annual free-as-in-freedom, grassroots technical summit dedicated to spreading awareness, community engagement and practical knowledge about free software, open hardware and libre culture.
Tool and documentation development

diffoscope
is our in-depth and content-aware diff utility that can locate and
diagnose reproducibility issues. This month, Chris Lamb made a
number of changes, including preparing and uploading versions
333,
334,
335 and
336 to
Debian:
-
New features:
- Support the
dumppdfbinary being calleddumppdf.pyon the host/runtime system. […]
- Support the
-
Bug fixes:
-
Codebase improvements:
-
Misc:
In addition, Johannes Schauer Marin Rodrigues added support for
POSIX.1-2001 PAX headers in the .tar file
comparator […]
and Vagrant Cascadian proposed an update in
diffoscope in GNU Guix to version 335.
Distribution work

In Debian this month, 20 reviews of Debian packages were added,
28 were updated and 27 were removed this month adding to our
knowledge about identified issues. One issue type was updated
to reflect that Debhelper ‘compat’ level
14 is no longer experimental. […]
In addition, Vagrant Cascadian performed a number of Non-Maintainer
Uploads (NMUs) and
Quality Assurance (QA) uploads in Debian for several packages
with outstanding reproducibility issues. These included
clhep,
tea-cli,
argparse-manpage,
ruby-timers,
mandos and
cdebootstrap.

Lastly, Bernhard M. Wiedemann posted another openSUSE monthly update for their reproducibility work there.
SOURCE_DATE_EPOCH
specification updates
As announced in last
month’s report, further work has been done by Bernhard M.
Wiedemann regarding updating the
SOURCE_DATE_EPOCH specification following discussions at
a project summit. Seven distinct proposed changes were originally
submitted as merge requests on Salsa, and
many of these have been approved or otherwise collapsed.
Bernhard’s proposed modifications were independent of one another, allowing for any combination to be merged depending on community feedback. Bernhard noted that one proposal may see the most debate, and could still benefit from further refinement before reaching consensus. Community members are invited to review and provide feedback on the individual merge requests; as Bernhard writes, “The other MRs could still use feedback from more people before December”. Input can be submitted via reactions or comments on Salsa, directly by email to Bernhard or the mailing list.
The SOURCE_DATE_EPOCH
specification was first published in 2015 and updated in 2017.
Mailing list news
On our mailing list this month:
-
Robin Candau posted to the list to announce the revival of a central repository to share reproducible builds patches. Following discussions at this year’s Reproducible Builds summit, Robin and Bernhard M. Wiedemann brought back a repository originally created a decade ago to collect distro-specific fixes in a unified location. Bernhard has already populated the repository with reproducible builds patches from openSUSE, while Robin has contributed patches from Arch Linux and has invited maintainers from other distributions to request push access.
-
Last month, Alexander Sosedkin inquired on the mailing list about the preferred approach for sourcing pinned translation files to create reproducible GnuTLS release tarballs, asking whether external hosting should provide versioned downloads, or if projects ought to use Git submodules, dedicated side-repositories or some other mechanism. The conversation continued this month with a number of proposals.
-
Jeremy Bícha wrote that he was seeking assistance with a reproducibility failure in GNOME’s
libsouplibrary when built usingdebrebuild. Filed as Debian bug #1126440, the issue stems from a Meson build system check that inspects Apache and its local configuration during the build process, which fails insidedebrebuildenvironments. His query solicited a number of replies (including one from an AI agent). -
Janneke Nieuwenhuizen and Ekaitz Zarraga announced two releases of GNU Mes: version 0.27.2 and version 0.28. GNU Mes is a Scheme interpreter and C compiler created to facilitate bootstrapping the GNU system without relying on opaque binary blobs, serving as a core component of the Bootstrappable Builds effort. Version 0.27.2 serves as a bug-fix release adding compatibility for the recently-released GCC 16 and NYACC versions 2.02.4 and 3.00.0, etc. whilst version 0.28 introduces a major overhaul of the core interpreter.
Patches
The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where applicable or possible. This month, we wrote a large number of such patches, including:
-
Bernhard M. Wiedemann:
-
Chris Lamb:
- #1150109 filed
against
js8call. - #1150326 filed
against
pywps. - #1150327 filed
against
php-nesbot-carbon. - #1150439 filed
against
kicad-library-utils. - #1150440 filed
against
ros-dynamic-reconfigure. - #1150916 filed
against
golang-github-anacrolix-log. - #1150917 filed
against
complexity. - #1151669 filed
against
node-uplot. - #1152182 filed
against
python-poetry-dynamic-versioning.
- #1150109 filed
against
-
Jochen Sprickerhof:
- #1150414 filed
against
open-build-service.
- #1150414 filed
against
-
Johannes Schauer Marin Rodrigues:
-
Vagrant Cascadian:
-
Zackary Loevseth:
In addition, two build failure bugs were reported by Jochen Sprickerhof.
If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:
-
IRC:
#reproducible-buildsonirc.oftc.net. -
Mastodon: @reproducible_builds@fosstodon.org
-
Mailing list:
rb-general@lists.reproducible-builds.org
Tech Companies Are Trying to Shift the Entire Concept of Privacy (Again) [Deeplinks]
Privacy, which companies were once happy to claim was all about personal choice, is now primed to affect everyone around you even more than it already did.
Meta and Google’s smart glasses can record anything the owner is looking at or use artificial intelligence to describe it. Apple’s* Audio Intelligence feature turns every Apple Watch into a transcription machine that records or summarizes your day. Amazon’s Bee devices take that a step further and can record and transcribe everything. Dozens of other companies are introducing pendants, rings, and other products designed to record, transcribe, or summarize everything we say and do all day long.
Privacy has always been a team sport. The actions you take with communication apps, collaborative software, or your cloud backup solutions, have long impacted everyone else you’re interacting with. But moving those choices deeper into the physical world where strangers, colleagues, family, and friends are all now a part of your privacy choices is drastically changing the game.
Tech companies want us to accept a reality where one person’s privacy choices (or lack thereof) mean you suddenly need to be an expert in consumer tech who understands the capabilities of many devices on the market, how they work, how and if they signal when they’re recording, and what platforms they do or do not connect to. They believe these ambient surveillance devices that work in the background and are designed to look as normal as possible are the future, while they also expect the owners of these devices to use them responsibly and to notify those around them of their capabilities to act within whatever laws their states may have.
This is not reasonable, nor how consent works in any practical sense.
Let’s break this down by looking at some of the biggest players currently in the game: Apple and Amazon, who have two different takes on transcribing audio throughout the day, as well as Meta and Google, who both have slapped AI and cameras onto eyeglasses.
How to Think About the Technical Promises Companies Make
Ask Apple about privacy concerns and they’ll point to a white paper that explains all the technical barriers between them as a company and the data generated by the watch. Ask Meta and they’ll talk about all the ways you can customize the privacy controls or how certain details, like faces, may be blurred out when you interact with Meta AI through the glasses (but not during standard recording). Google does this too. Amazon will also talk about how you’re always in control, and no audio is stored (though it’ll also let you enable Amazon store integration, so your conversations can directly result in ads for products). And so on across all the companies making these products.
Some of these solutions do a better job than others at cutting out potential law enforcement or company access to this data. There will be a time to dive into these details more deeply, but the technical privacy promises these companies focus on only cover the consumer and user of the device. They ignore every bystander you interact with and their inability to actually opt out. There is no technical protection for you as a non-user of these devices, the person who finds yourself captured by them.
Still, we hope to look deeper into the technical differences between this category of devices soon.
There Must Be Some Laws to Consider, Right?
With something like Apple’s Audio Intelligence and Amazon’s Bee devices, it may be best to treat them similar to an always-recording microphone, even if companies try to claim there’s “technically” no audio recording. These tools still often use a microphone to capture raw audio from conversations and convert it into summaries or transcripts before discarding the audio. Google's blog post notes that it has a whole responsible use part of their Terms of Service where users have to agree not to record others without permission or in sensitive places.
But it’s not just the question of the legality from the point of view of the user. Law enforcement will eventually try to compel access to the data that these products create (either real-time audio or the summaries and transcripts they create). And while some products, like Apple’s Audio Intelligence, are engineered to make that difficult, not every product will be. We know from history that when data exists, governments will do everything they can to access it. There’s no reason to think something would change today.
No Tech and Legal Solutions Will Reduce Social Issues
There is a problem humming along in the background that is impossible to address with technical or legal solutions. If secretly documenting conversations becomes the norm, it makes every private conversation less spontaneous and open. It breaks a longstanding social norm that you will not record and document every conversation with friends, family, colleagues, or strangers.
The companies that make these sorts of products like to claim they’re no different from tools we already have. You can easily record everything right now with a phone or a camera. Heck, you can do so with a camcorder or cassette recorder if you want. And you can transcribe conversations with pen and paper, too. But those are actionable steps we take that both require effort from the user, and are clear to others around us. This new wave of passive surveillance tech is designed to encourage continuous monitoring and hide its use.
Even taken at face value, none of these products can understand the complex social context we all navigate every day. We intrinsically know there are different social agreements we all make when we’re standing on a street corner, at a protest, in a bathroom, at a doctor’s office, at the gym, or in a restaurant. Taking notes in a meeting at work is completely normal. Getting a summary of a conversation with your best friend about their divorce is not. Always-on monitoring of our conversations is an unacceptable burden on our conversational privacy.
Google seems to all but admit this problem in a conversation with CNN when it described the company’s experiments with a notification system that would alert people’s phones when someone was recording nearby:
“And just alerting bystanders doesn’t do much to help, [Juston Payne, senior director of product management at Google] said. “It can actually be weirdly disempowering to you in that you’re like, ‘What am I meant to do now?’” he said.”
What We Can Do About It
It’s easy to buy into the tech company line that these products are inevitable, but we’ve seen so many vaporware products over the years that we should take those claims of success with a grain of salt. We’ve seen entire product categories come and go within just a few years, and if the public doesn’t want this stuff, the tech companies will have to throw in the towel.
Of course, that doesn’t mean we all just have to sit around and hope that’s what happens. For its part, Apple launched its Audio Intelligence features in beta specifically to get feedback, and we think it’s worth taking the time to fill out their feedback forms (or in the Feedback Assistant app if you’re in the beta) and let them know what you think.
Products from the likes of Meta, Google, Amazon, and others might be harder to push back on, but politely and clearly engaging with those who use them in ways that make you uncomfortable is a good place to start. And if you see abusive videos on social networks where these sorts of products are used, report them. If you find these products useful for yourself, make it clear to those around you when you’re using them, and only do so with consent and in social moments where it makes sense to do so.
*Apple is an EFF donor. EFF donors do not influence our agenda or our positions.
Friday Squid Blogging: Pacific Flying Squid Populations Dropping in Korean Waters [Schneier on Security]
Climate change is the issue.
As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.
21:28
Building GNU Emacs from source [Planet GNU]
In the recent years, I've been configuring and building GNU
Emacs from source, specifically the master branch of
the emacs.git repository. Doing so allows me to use
and test latest Emacs features, test my Emacs Lisp code with the
laest developments in Emacs, and easily contribute my own changes
to Emacs.
Before we start, I recommend reading the INSTALL
file in the Emacs source repository for building Emacs from source
tarballs, and also INSTALL.REPO for details about
building Emacs from its source repository. The information provided
here were built upon the details documented in those files. When in
doubt, consult those files as the main, authoritative source of
information for how to build Emacs from source.
Installing build dependencies
To build GNU Emacs from its source repository, we first need to
install the various required tools and build dependencies of Emacs.
On Debian-based systems, this can be done using apt.
First, we need to add the source packages for the current release
of our Debian-based distribution in apt's configuration by adding
the corresponding deb-src lines in an apt source list file. For
currently existing and older Debian releases, that would be done by
adding a corresponding deb-src line for each deb line in
/etc/apt/sources.list, such as:
deb http://deb.debian.org/debian/ trixie main
deb-src http://deb.debian.org/debian/ trixie main
In systems with recent apt versions with so-called modernized
sources that might look editing a file like
/etc/apt/sources.list.d/debian.sources and adding
deb-src to the Types lines:
Types: deb deb-src
URIs: http://deb.debian.org/debian/
Suites: trixie
Components: main
Signed-By: /usr/share/keyrings/debian-archive-keyring.gpg
Then run sudo apt update to have apt download
package information from the configured sources.
We can now run sudo apt build-dep emacs to have apt
download and install the build dependencies of Emacs. Debian-based
distributions have packages for a few different configurations of
Emacs, like emacs-pgtk with PGTK support for Wayland,
and emacs-nox for Emacs without GUI support, which we
can use with apt build-dep to download the specific dependencies of
those configurations.
Cloning the Emacs source repository
After installing Git using sudo apt install git if
not already installed, we're now ready to clone the Emacs source
repository from GNU Savannah:
git clone https://https.git.savannah.gnu.org/git/emacs.git
We can add --depth 1 to make a shallow clone of the
repository, if we don't care about having a complete log of
previous commits to the Emacs repository (shallow clones are much
faster).
If cloning over HTTPS is slow, we can try cloning over Git's own protocol (with the caveat that the repository is cloned over an insecure channel) or over SSH if we have a Savannah account, using one of the following URLs instead of the one above:
git://git.git.savannah.gnu.org/emacs.git
ssh://git.savannah.gnu.org/srv/git/emacs.git
Configuring the Emacs build
We now change to the Emacs repository directory we just cloned,
and run the autogen.sh script once to generate the
configure script, which we will use to configure Emacs
to our liking:
cd emacs
./autogen.sh
To configure Emacs, the simplest approach is to run
configure without any additional options, to have it
use the defaults. We can get a list of available configuration
options by running:
./configure --help
As I rebuild Emacs frequently, I normally don't "install" it,
but for a typical setup, we'll want to specify the installation
directory using --prefix, e.g.:
./configure --prefix=$HOME/.local
Later, make install will install Emacs under the
specified directory.
By default, some of the files (such as *.el) will
be compressed during installation. We can prevent that using
--without-compress-install.
For my builds, I always use these configuration options:
--without-gconf
--without-gsettings
--without-gpm
--with-native-compilation
As I don't use the GNOME desktop, the GConf and GSettings integrations are always more trouble than useful for me, so I disable them. Further, I disable the GPM support, since I never use the mouse when using Emacs in the terminal. Lastly, I explicitly enable native compilation support.
In Wayland environments, I usually use PGTK:
--with-pgtk
And in X11 environments (e.g. EXWM), I either use the Lucid toolkit:
--with-x-toolkit=lucid --with-xaw3d
Or no toolkit at all:
--with-x-toolkit=no --without-xaw3d
Later after building Emacs, we can view the configuration
options in Emacs by inspecting the
system-configuration-options variable.
Building Emacs
After running ./configure, we can now finally build
Emacs by running make. The first build will take a
while, since all of Emacs is being built from scratch. Subsequent
builds will generally be faster.
We can optionally run make install to install Emacs
into the prefix specified earlier, or the default
/usr/local. Note that this step might require using
sudo if our user doesn't have write permission for the
prefix.
Running Emacs
After building Emacs, we run it either from the install location
if we ran make install earlier, or directly from the
source repository. Currently, Emacs's build system makes a symlink
to the latest built binary in the repository at
src/emacs, and for emacsclient and other
auxiliary binaries under the lib-src directory.
When skipping make install, we might still want to
be able to easily launch Emacs from anywhere by typing
emacs. We can do that by making symlinks to
emacs and its auxiliary binaries inside a directory in
our $PATH, such as $HOME/.local/bin, like
so:
cd $HOME/.local/bin
ln -s $HOME/src/emacs/src/emacs .
for e in \
 ebrowse emacsclient etags make-docfile\
 make-fingerprint hexl rcs2log; do\
  ln -s $HOME/src/emacs/lib-src/$e .; done
For non-install setups like this, I augment
Info-directory-list in my init file with the location
of the info manuals in the repository to make them known to
Emacs:
(defvar Info-directory-list)
(with-eval-after-load 'info
  (setq
   Info-directory-list
   `(,@Info-directory-list
     ,(expand-file-name
       (convert-standard-filename "info/")
       source-directory)
     "/usr/share/info/")))
Updating Emacs
We can pull in the latest changes in the Emacs repository using
git pull, then rebuild our Emacs by running
make.
Occasionally, rebuilds may fail due to bad interaction of
changes with leftover build artifacts. In such cases, the easiest
thing to do would be a make bootstrap for an
almost-from-scratch build. On even rarer occasions, make
bootstrap might also fail. We would then want to run
git clean -xdf to remove every file that's not tracked
by Git, as if we freshly cloned the repository. In such cases, we
would need to configure the build again using
./configure and provide the desired options before
running make again.
Further reading
Protesilaos's similar post from early 2025 was part of the inspiration for writing and sharing my version:
https://protesilaos.com/codelog/2025-03-22-emacs-build-source-debian/Lastly, to reiterate, Emacs's own INSTALL and
INSTALL.REPO files for building from source:
https://cgit.git.savannah.gnu.org/cgit/emacs.git/tree/INSTALL
https://cgit.git.savannah.gnu.org/cgit/emacs.git/tree/INSTALL.REPO
Take care, and so long for now.
20:35
Pluralistic: I told you so (13 Nov 2026) [Pluralistic: Daily links from Cory Doctorow]
->->->->->->->->->->->->->->->->->->->->->->->->->->->->->
Top Sources: None -->

Today's links
- I told you so: Microsoft is too big to live.
- Hey look at this: Delights to delectate.
- Object permanence: Canada's corrupt copyright czar; Universal Music CEO v iPod owners; Berlusconi x neo-fascists; Balancing 3,118 coins on a dime; All for-profit healthcare is a problem.
- Upcoming appearances: Folkestone, Oxford, Sheffield, Virtual, Oxford, Santa Barbara, Montreal.
- Recent appearances: Where I've been.
- Latest books: You keep readin' em, I'll keep writin' 'em.
- Upcoming books: Like I said, I'll keep writin' 'em.
- Colophon: All the rest.

I told you so (permalink)
Here's the one weird trick that made it possible for monopolies to conquer the world: the antitrust bar changed the rules so that it was impossible to prove whether a company had formed an illegal monopoly, and then these rules meant that monopolies were almost never challenged, and what challenges did arise were usually unsuccessful, and even the successful challenges resulted in meaningless "penalties" that left monopolists unscathed.
Every policy has three important dimensions: substance, scope and administrability:
- "Substance" is what the policy actually says. For example, the basic substance of copyright law is, "You can't display, transmit or reproduce a copyrighted work without permission."
-
"Scope" is when the policy gets applied. When copyright law was formulated, the key activities it regulated all required a bunch of expensive industrial equipment. Every book implied a printing press, every record implied a record-pressing plant, every film implied a film duplication lab. That meant that, by default, pretty much the only people who had to care about what copyright law said were industrial actors – firms that might reasonably be expected to also have access to a lawyer. That matters a lot to administrability.
-
"Administrability" is what it takes to actually administer the policy. Can you detect potential violations, and when you do, how hard is it to figure out whether the rule was actually broken? Again, in the pre-digital era, it was pretty easy to spot copyright violations: pirate books, records and movies are tangible, physical objects, and distributing them requires advertisement, delivery and payment.
After detecting an infringement, copyright enforcers must resolve a further question: whether a display, transmission or copy falls under "fair use." Fair use is a "fact intensive" rule, one that requires a lot of evidence and argument to adjudicate. It's almost impossible to categorically rule in or rule out a specific use as "fair":
https://pluralistic.net/2024/06/27/nuke-first/#ask-questions-never
Despite the complexity and expense of determining fair use, pre-digital copyright was still relatively administrable, because fair use questions themselves were relatively rare. Most fair uses (for example, photocopying part of a book for classroom use) were below the threshold for detection by rightsholders, so these questions almost never found their way into court. The fair use questions that did get to court were big, splashy affairs, like whether it's okay to rewrite a famous pro-slavery novel from the enslaved characters' perspective (it is!):
https://en.wikipedia.org/wiki/The_Wind_Done_Gone
There are a lot of legal questions that require nuance, fact-finding and argumentation to resolve, and that's not necessarily a problem. It's fine to apply these complicated, lengthy processes to things that only happen every once in a while. Take probate: most of us will die one or fewer times, so it's not the worst thing in the world that figuring out what happens to our stuff when that happens can involve some legal complexity.
But as media went digital, copyright's scope expanded dramatically. "Making or handling copies of copyrighted work" stopped being an industrial activity that implied a complex business and access to legal expertise. The only thing a digital computer does is make and handle copies, so every time any ordinary person clicks their mouse, dozens of potentially thorny copyright questions arise. What's more, those questions involve the public internet, which raises the number of potential infringements that a rightsholder can detect (and potentially seek legal redress for) from dozens to millions.
Nearly all of these potential infringements fall under fair use, but fair use is a fact-intensive doctrine suited to resolving occasional disputes between large firms. Fair use is monumentally unsuited to resolving questions that arise hundreds of times every day for nearly every person alive, including small children and other people who almost certainly can't get legal advice:
https://locusmag.com/feature/cory-doctorow-a-new-deal-for-copyright/
This is how copyright broke: new technology (digital computers) radically expanded its scope, conscripting everyone into using copyright's framework for everyday activities that had nothing to do with the media industry's supply chain. That framework was developed for industrial actors with access to lawyers, and its most important aspect (fair use) is a fact-intensive doctrine that takes serious work to resolve, but now had to be navigated many times every day by every person. So copyright became unadministrable: you can't apply a fact-intensive doctrine to everyday activities undertaken by everyday people. If you try, you will make criminals of everyone. It would be literally impossible to train enough copyright lawyers to advise every person every time they use a computer to do something that might violate copyright law.
Back to antitrust: when the pro-monopoly partisans of the "law and economy" movement set out to neuter antitrust, they deliberately introduced a set of hurdles that were designed to make it impossible to administer competition law.
First, they introduced an "intent" standard: it was no longer enough for a company to have a monopoly, the company must have intended to secure and maintain that monopoly. If you want to be sure a law doesn't get enforced, this is a fantastic standard to apply. After all, how can anyone know what anyone else intended? Ask any anthropologist and they'll tell you: the only way to find out what someone intends by their actions is to ask them, and even that only works if you can trust them to answer honestly:
https://en.wikipedia.org/wiki/Thick_description#Clifford_Geertz
If antitrust law can only be enforced by mind-readers and advanced philosophers who have solved the intersubjectivity problem, then antitrust law can't be enforced at all:
https://en.wikipedia.org/wiki/Intersubjective_verifiability
But that wasn't all! Antitrust's enemies insisted on another fact-intensive question: "market definition." They made the (seemingly commonsense) point that if a company is said to have a monopoly, we must first determine which thing the company has monopolized. This sounds like a no-brainer, but it's actually a way to introduce unresolvable, show-stopper arguments into any antitrust enforcement action.
Take Amazon: the company's ecommerce monopoly is obvious to anyone who hasn't been in a coma for the past 15 years. But when Amazon gets investigated for this monopoly, they will insist that they don't participate in the "ecommerce" economy, but rather in "the buying and selling of things in general." Then they point out that people still go to the corner store for a pint of milk, still buy a pack of gum from the kiosk at the train-station, and still buy some hair-gel from the barber after a trim, and therefore Amazon can't possibly have a monopoly.
"Market definition" is a playground for bad-faith semanticians. Luckily for the world's monopolists, the very existence of this legal doctrine has conjured up an army of bad-faith semanticians, most of them with expensive Ivy League economics degrees, who make millions coming up with bizarre market definition arguments that can draw out any legal proceeding for years, often to the point where there is a change in government and the federal prosecutors just walk away from the case.
Taken together, these impossible fact-intensive questions would be enough to bury antitrust, but then came the final blow: frequency. Once capital had won the battle to mire antitrust cases in questions that take years and millions to resolve, they embarked on a frenzy of monopolistic mergers. This meant that the kind of antitrust questions that originally arose every few years were suddenly coming up several times per month. This was the killer combo: making antitrust a plodding ball-ache of thorny philosophical and technical questions, and then rigging the system so that these questions arise in a nonstop flurry guaranteed that antitrust would fail.
That's what happened with Microsoft. The company had a 95% desktop OS market-share when Clinton's trustbusters dragged them into court. Nevertheless, the company played all kinds of "market definition" games that dragged the case out for years. They also insisted that they never intended to form a monopoly, despite smoking-gun memos about "sucking up all the market oxygen":
https://web.archive.org/web/20190717023522/https://www.justice.gov/atr/department-justice-7
This dragged on so long that even after Microsoft lost its case, the appeal carried on until after GW Bush stole the presidency, and then his DoJ walked away from the case, letting Microsoft continue to enjoy (and increase) its monopoly:
What happened next should not come as a surprise to anyone. Microsoft got convicted of deliberately setting out to create a monopoly, and then paid no penalty. After an all-too-brief period of post-traumatic good behavior, Microsoft returned to its monopolistic ways. Along the way, Microsoft sucked up to a succession of presidential administrations, culminating in the company's emergence as a de facto wing of the Trump regime. Microsoft's CEO paid $1m to sit on the inaugural dais, and then directed the company to donate millions to the Epstein Ballroom, and then provided the IT services for ICE's ethnic cleansing pogroms:
Microsoft isn't merely the in-house IT shop for Trump's domestic agenda: they've also weaponized foreign reliance on Microsoft's cloud apps and they punish foreign officials who thwart Trump abroad:
When forced, Microsoft candidly admits that no matter where in the world your Microsoft data is stored, when it comes to foreign firms and governments, the company will give warrantless, secret access to their data to Trump's cronies:
All of this raises an urgent digital sovereignty question: what if Microsoft (a monopolist that is entirely dependent on Trump's favor to keep it free of existential legal problems) cuts off your country's Office 365 access? This is the question I raised late last year in my CCC talk about the "Post-American Internet":
https://pluralistic.net/2026/01/01/39c3/#the-new-coalition
(Coming soon in expanded form to a bookstore near you:)
https://us.macmillan.com/books/9780374623845/thepostamericaninternet/
And now, Microsoft has given the whole world a preview of how this might play out, because their servers have collapsed, shutting the world off from Outlook email, Azure cloud, Copilot, Teams, and other key offerings:
https://www.bbc.com/news/live/cq5y10ge3dp3t
The outage lasted for about two days, and around the world, government agencies and businesses large and small ground to a halt. Without Office 365, Outlook and Teams, many organizations could not even convene a meeting or formulate a plan to deal with the outage.
All of this raises an important question: is Microsoft guilty of negligence, and, if so, what should be done about this? Here's my answer: Yes, Microsoft is presumptively guilty of negligence, and any response to this must include antitrust breakups of the company.
Here's why I think that. Microsoft has demonstrably underinvested in its IT stability. Any IT plan that results in a global, multi-day outage is, by definition, inadequate. Whether the problem could have been solved by buying more servers, or hiring more people, or changing the management of key divisions is immaterial. Every one of these measures – every single measure that could have prevented this – costs money. By not spending that money, Microsoft definitively underinvested in its products.
But Microsoft doesn't lack for funds! Microsoft is a convicted monopolist, and it has the margins to prove it. In 2025-2026, the company pissed away more than $30b in stock buybacks, a once-illegal (and still sleazy) form of stock manipulation. Over that same period, Microsoft lost nearly $200b on AI ventures that it now admits will not pay off:
https://www.cnbc.com/2025/02/24/microsoft-reiterates-plan-to-invest-80-billion-in-ai-.html
Then there's the layoffs. 2026 saw Microsoft's first-ever voluntary retirement buyout, which served as the overture to a year that saw a 25% headcount cut – 60,000 employees slated for destruction:
https://www.theguardian.com/technology/2026/oct/26/microsoft-buyout-offers-ai-cuts
Ever had a boss who caught you catching your breath and shoved a broom in your hand, barking, "If you have time to lean, you have time to clean?" That goes quintuple for convicted monopolists who bring the global economy to a halt due to a multi-day outage. If you can't manage to keep your servers online, you have no business incinerating tens of billions on stock buybacks, much less hundreds of billions to feed the AI money-furnace. Did Microsoft need the tens of thousands of workers it threw away? Demonstrably so: when they were on the payroll, Microsoft's servers were up. Now they're gone, and so are the servers. It doesn't matter how those workers related to this specific outage: if you can't keep your servers online, you either don't have enough site reliability engineers, or you don't have enough managers to deploy them effectively, or you don't have enough managers to hire the managers and SREs you need.
Q.E.D.
This is all characteristic of the monopolist's pathology. The problem with monopolists is that they have pricing power and market power: the power to foist inferior products on their customers and degraded working conditions on their employees and unfair terms on their suppliers. Microsoft's hundreds of billions in wastage and tens of thousands of layoffs are a massive transfer of value from customers, workers and suppliers to investors. The fact that the company judged (correctly, it seems) that they could make us all eat shit and we'd ask for second helpings is a nice, clean proof of monopoly power.
Here, I think, is a nice, bright-line, administrable test for monopoly power. If your company has a dominant position and if it allocates its surplus capital to its investors and if that precedes a significant degradation of your products, then you have an illegal monopoly and you should be broken up. We don't need to inquire as to whether you have a wicked heart that intentionally set about to create a monopoly, nor do we have to argue endlessly about how many angels can dance on the head of your market definition. If you think you are so powerful that you can fuck up your products and not suffer as a result then you are too big to care, and that is simply too big.
This isn't the only fix we need to antitrust law, but it is a fix that would specifically let us target Big Tech. Microsoft is a living, breathing (limping, gasping) repudiation of the thesis that monopolies are efficient and if we only let them amass endless market share and profits, they will use their "economies of scale" to deliver superior products. It's not that economies of scale don't exist, but for companies to take advantage of these economies of scale, they have to be motivated to expend their capital to do so. The more powerful a company is, the less inclined it will be to apportion capital to workers, suppliers and consumers, and the more it will cheat us all to enrich its shareholders.
We can't afford to let this crisis go to waste. Google was convicted of creating and maintaining a monopoly three times over the past couple years and every single time the judge decided the company should not face any real punishment for that monopoly, on the basis that the monopoly is what lets Google deliver such excellence for us.
Does anyone still think Google is excellent? How about Apple? Google pays Apple an annual bribe of more than $20b to stay out of the search market. Judge Amit Mehta decided to let Google continue paying this bribe to Apple so that Apple would have the capital it needed to deliver excellent products. Apple promptly went on to have a string of catastrophically bad product launches – while throwing away $170b manipulating its share-price with stock buybacks:
Both companies are demonstrably underinvesting in quality in order to divert R&D and product maintenance capital to their shareholders. They are too big to care. In this age of nonstop mergers and acquisitions, we can't afford to make merger approval turn on fact-intensive questions, but we can sure as hell create this administrable, bright-line test for whether a merger should be unwound after the fact. Did your company buy another company and then enshittify both products? Great, now we're breaking you up, and your investors are getting fucked. Maybe next time they'll fire the board when they announce another stupid, anti-competitive merger.
Microsoft is too big in every way. Too big to fail, too big to jail and too big to care. Too big to trust. Too big to rely upon. Too big to foster a corporate culture that cares about reliability, a decent workplace, or product quality. There's a straight line from GW Bush's decision to let Microsoft skate in 2001 and the situation a quarter century later, where Microsoft is a load-bearing piece of the world's most important firms and government agencies, and where this means that Microsoft knows that it can throw away tens of thousands of workers and hundreds of billions of dollars, crash the planet, and wake up tomorrow unscathed, ready to do it all over again.
Hey look at this (permalink)
- Copyright-Strike-for-Hire: Lawsuit Targets Service Over Fake Meta Takedowns https://torrentfreak.com/copyright-strike-for-hire-lawsuit-targets-service-over-fake-meta-takedowns/
-
A Tool Built by Election Deniers Said These Voters Were Dead. We Found Them Alive. https://www.propublica.org/article/election-challenge-forsyth-county-georgia
-
How to prepare a revolution https://www.absurdintelligence.com/how-to-prepare-a-revolution/
-
Watching the Watchers https://watchingthewatchers.github.io/watchingthewatchers/
-
College student develops LEGO-like, 3D-printed moon bricks https://www.popsci.com/science/3d-printed-lunar-lego-bricks/?utm_source=firefox-newtab-en-us
Object permanence (permalink)
#20yrsago Canadian copyright minister caught lining pockets https://web.archive.org/web/20061115062027/https://www.michaelgeist.ca/content/view/1529/135/
#20yrsago Universal Music CEO: iPod owners are thieves https://web.archive.org/web/20061201014046/https://www.billboard.com/bbcom/news/article_display.jsp?vnu_content_id=1003380831
#15yrsago OccupyLondon members evicted from St Paul’s memorial services https://www.theguardian.com/uk/2011/nov/13/occupy-london-asked-leave-st-pauls-services
#15yrsago Berlusconi to neo-fascists: “I’ll be back.” https://www.theguardian.com/world/2011/nov/13/berlusconi-hints-return-italy-government
#15yrsago Balancing 3,118 coins on a dime https://www.youtube.com/watch?v=CmLjO0Wu3ug
#10yrsago People who voted for Trump knew their shot at the elites was fired through the guts of their neighbors https://web.archive.org/web/20210916183118/https://www.newstatesman.com/spotlight/2016/11/on-the-election-of-donald-j-trump-2
#10yrsago Ontario judge dishonours his court and disgraces himself by presiding in a MAKE AMERICA GREAT hat https://www.cbc.ca/news/canada/hamilton/osgoode-hall-professor-ontario-judge-hamilton-trump-hat-1.3848913
#10yrsago 300 million Adultfriendfinder accounts breached https://www.theverge.com/2016/11/13/13615750/412-million-adultfriendfinder-accounts-exposed-breach
#5yrsago How to be safe(r) online https://pluralistic.net/2021/11/13/opsec-soup-to-nuts/#secured
#1yrago For-profit healthcare is the problem, not (just) private equity https://pluralistic.net/2025/11/13/patients-not-customers/#medicine-vs-markets
Upcoming appearances (permalink)
- Folkestone Writers Festival, Nov 16
https://www.creativefolkestone.org.uk/whats-on/cory-doctorow-the-internet-is-broken-now-what/ -
Oxford: Ministry of the Future, Nov 23
https://ministryforthefuture.co.uk/events.html -
Sheffield: Reverse Centaur at Juno Books, Nov 25
https://www.outsavvy.com/event/40274/cory-doctorow-in-conversation -
Virtual: Enshittification, AI, and the Future of Technology (UBC Master of Educational Technology), Nov 28
https://met.ubc.ca/2026/09/met-speaker-series-cory-doctorow-enshittification-ai-and-the-future-of-technology/ -
Oxford: Bennett Oxford Symposium on Open Code in Science, Dec 9
https://www.bennett.ox.ac.uk/events/2026-bennett-institute-symposium/ -
Santa Barbara: UCSB Reads, Apr 29
https://www.library.ucsb.edu/events-exhibitions/ucsb-reads-2027-presents-author-cory-doctorow -
Montreal: World Science Fiction Convention, Sep 2-6
https://montreal2027.ca/en
Recent appearances (permalink)
- Clint Eastwood (No Gods No Mayors)
https://www.patreon.com/NoGodsNoMayors/posts/clint-eastwood-173008088 -
Life After AI (Brain Bar)
https://www.youtube.com/watch?v=IPPa43-n0vI -
Terms of Service with Clare Duffy (CNN)
https://www.cnn.com/audio/podcasts/terms-of-service-with-clare-duffy/episodes/458ce968-af5d-11f0-b539-13ed2afe25f8 -
AI, Work, and Power (Software Engineering Daily)
AI, Work, and Power https://softwareengineeringdaily.com/podcasts/cory-doctorow-on-ai-work-and-power/ -
AI, Corporate Power, and the Fight for Worker Control (Plutopia)
https://plutopia.io/cory-doctorow-ai-corporate-power-and-the-fight-for-worker-control/
Latest books (permalink)
- "The Reverse-Centaur's Guide to AI," a short book about being a
better AI critic, Farrar, Straus and Giroux, June 2026
https://us.macmillan.com/books/9780374621568/thereversecentaursguidetolifeafterai/ -
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
-
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/ -
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
-
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
-
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
-
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
-
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
-
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
Upcoming books (permalink)
- "The Post-American Internet," a geopolitical sequel of sorts to Enshittification, Farrar, Straus and Giroux, 2027
-
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
-
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
-
"The Memex Method," Farrar, Straus, Giroux, 2027
Colophon (permalink)
Today's top sources:
Currently writing:
- “Once Is Enemy Action,” a science fiction novel
about the origins of modern technofascism. Today's words: 561
(36083 total).
-
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
-
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
How to get Pluralistic:
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X
20:00
The week only got rougher for Jensen Huang after we wrote the strip; he had to fall on his sword, but a few other people had fallen on his sword recently so he had some sense of how it was gonna go.
19:49
Steinar H. Gunderson: Solving the fox game [Planet Debian]

Christoffer Stjernlöf posted about the Fox Game, an old Norse asymmetric board game (seemingly also called “halatafl”) where twenty sheep try to outsmart two foxes and get to the other side. His AI uncovered some interesting insights, but left the question open as of whether the foxes or the sheep actually win with perfect play (the general sentiment in his family was that winning with the foxes was easy). This was too tempting for me to leave on the table, so I set out to make a strong solve.
Since I don't know this game myself, I've stayed with the rules he describes even when they differ from e.g. Wikipedia (in particular, I do not use forced fox jumps, or multi-jumps); the only real change is that I don't have a 40-move draw rule, any position that is a forced win for one of the sides would be a win no matter how long it would take. (I consider this just an implementation detail in his AI, although morally, I consider a draw a loss for the sheep.) You might want to read his post to get the full rules, because I'm not going to repeat them here.
The results first: The sheep win with perfect play, even with only 19 sheep (remove one on the flank), or 18 if they are allowed to go first. Even with only 9 sheep (the minimum possible that isn't an instant win for the foxes), the sheep can force a draw right from the start. With one fox, 11 sheep suffice for a forced win. (The draw margin is seemingly so large because one fox can just camp in the last spot in the pen, and it's hard to force it away without getting harassed by the other fox, unless you have lots of sheep.)
The rest is about the implementation. I'll skip over a lot of wrong turns, and unsurprisingly, there were a lot of bugs to iron out, but hopefully, it got to a good place in the end. :-) I started out trying to make something very simple, and it worked for the first few cases, but then things got more complicated than I would have liked in the end. Still only at ~1000 lines of code, though, with no dependencies.
Board representation
The board has 33 squares. I tried a few different ways of represent the state of the game, and ended up on a simple bitboard representation: There's a 64-bit bitmap representing where there are sheep, and another bitmap representing where there are foxes. Since there's plenty of room in there, I use a spare bit to represent side-to-move. This is compact (which mattered a lot earlier on, but not as much later), easy to iterate over, and has little redundancy, so it's easy to keep valid. You need fast 64-bit population count and bit-scan instructions, but a) that's common now everywhere, and b) I decided fairly early that I wanted to require BMI2 anyway.
The bit order mostly doesn't matter; I just started at top-left and went from there. All it really influences is square iteration order. There's a small tweak in that I store the right half of the board mirrored (reverse x order) for symmetry purposes; more on that below.
Move generation
I just typed in every possible move from every square into an array, then verified by generating some SVGs that I hadn't made any typos (I had). In retrospect, I should have done something more automated; it would have been less painful.
The moves for sheep are just “you can go to X, Y or Z”. The moves for foxes are “you can go to X or Y, or you can go to Z if there's a sheep at W (which will be eaten)”. The move generator mostly just looks up the source square and tests every move. For the sheep, I make an easy test using bitboards; for the foxes, I could probably do something similar, but the jump moves proved a bit tricky (even with PEXT/PDEP) and I didn't end up using it.
This is the part that really determines the geometry of the board (apart from debugging display). Everything else is pretty much geometry-agnostic.
Result storage
There's a little over 2^41 possible board states (this includes some illegal positions as well as some situations that could never arise during actual gameplay, such as a fox being stuck at C1 with a row of sheep ahead of it), and I want to remember all of them. With that many positions, I figured I needed a fairly compact representation. I needed to store that a position could be sheep win, fox win or a draw, and then there was a fourth “invalid” state that was useful for internal reasons, so that maps exactly to two bits per position. (A tablebase intended for distribution could be compressed to less using the usual tricks of entropy coding, skipping half of the positions, or similar.)
This means we need to give a number to every possible position, ideally one with no collisions and no holes. I learned about combinatorial number systems which fit the bill exactly; given e.g. “we have 33 squares and 15 pieces”, it gives a dense mapping of positions from board to ID (ranking) and the opposite (unranking). (I made some fairly fast ranking and unranking algorithms, which may or may not have been novel, but it turned out I didn't actually need fast unranking after some other optimizations.) There are some extra complications in that there are two types of pieces, but you can solve them in a number of ways.
On a macro level, I store everything with 9 sheep and 1 fox first, then 9 sheep and 2 foxes, 10 sheep and 1 fox, and so on. This gives beautiful locality (a single move can never remove more than one sheep, and only extremely rarely more than one fox), allowing me to just mmap everything and let the kernel deal with it, even though I only had 256GB of RAM and the total set was larger (329,870,110,455 bytes after the symmetry optimizations below).
mmap is almost never the right answer, but again, I was trying to go for simplicity. It certainly brought me pain, though, and perhaps some more explicit I/O would have been better.
Symmetry
The board is left-right symmetric (with an odd number of columns, so that there is a middle column that is neither “left” nor “right”). I had hoped to just ignore this, but eventually the gains became too important to ignore, so I conceded.
The basic idea is that I ranked the board twice, both as itself and mirrored (mirroring is just a couple of masks and shifts, given my representation), and picked the key that was the smaller as canonical. This reduced the number of positions I needed to look at to a bit over 50%, as expected, but it does nothing to the storage/RAM requirements; the new rank is not dense and the “illegal” (non-canonical) positions are spread out a bit all over the place (although of course near the low and high ends of values, it works much better).
As a tweak, I chose to compute all 33+281 canonical fox positions and renumbered using those placements as an assumption. This slashes ~95% of the waste, which is good enough; you can still rank a nonconical position if the foxes are symmetric about the center (or if there's only one fox and it's in the middle!), though.
You can improve on this by making the macro-splitting finer; instead of having a chunk for e.g. “10 sheep, 2 foxes”, you could have one with “5 sheep in left, 0 foxes in left, 1 sheep center, 1 fox center, 4 sheep in right, 1 fox in right” and demand that there are more sheep in left than right. However, you still get problems when the number is balanced, you'd need finer splitting etc.. The gains are small enough that I didn't see the point in doing this, and it tends to be a place where it's easy to introduce bugs.
I imagined calculating the exact number of positions up to symmetry would be an interesting exercise somehow, but I suppose it just immediately falls to Burnside's lemma as soon as you know how to count positions at all.
Searching
Now that we have positions and moves and a way to store results, we want to know how to find the result for the starting position (and ideally also all other positions).
My first attempt just did a depth-first search, caching as it went. This worked for the earlier stages but was generally a disaster; it ran out of stack easily (even with 8 GB—eight gigabytes of stack), and had problems with figuring out loops. (It didn't loop infinitely, but was prone to declaring loops where one side could break out of the loop by winning. I had a nasty hack to fix that, but it didn't really feel good.)
What I did instead was propagating results one step at a time. For each possible position:
-
If from a given position you know you can immediately win (e.g., the sheep reach the pen, or the fox eats the last relevant sheep), mark it as such.
-
If you can, in one move, reach a known-won position, mark your position as won (for the side to move). Similarly, if you can only reach known-lost positions, mark your position as lost.
-
Repeat #2 over and over again until you no longer have changes.
This was simple but still inefficient; I typically needed 40–80 passes for each chunk (where a chunk is something like “all positions with 15 sheep, 2 foxes”). However, it was super-easy to parallelize; I have 64 cores and could just hand out reasonable independent sub-chunks, you don't even need locking or atomic operations on the result set.
The correct way of doing this is retrograde analysis (replace #2 with doing backwards moves) and I assume this would have made the calculation roughly ten times as fast. But I only needed ~36 hours for the actual run (plus numerous pre-runs that failed for various reasons!), so I never got to this. After all, I wanted something simple to begin with.
Distance-to-win
Since I only store win/draw/loss (WDL) for each position (also known as a “bitbase” in chess tablebases), it's not easy to know what the fastest way to win is; just that “this move does not mess it up, the other side still can't force a draw”. However, in practice, you could just do reasonable-looking moves that don't regress the position, and take forward moves whenever you can (i.e., do sheep pushes if that still wins).
I made a simple alpha-beta searcher that tries to get win distances using the bitbase as a guide, which was a really fun challenge! It can find wins when they're perhaps ~20 ply (10 moves for each side) away, depending a bit on how narrow the win is (if there are only a few ways to win, it will obviously have to search a much smaller tree). Ultimately, though, alpha-beta for finding exact mate scores is just a losing game, since even perfect move ordering will only give you a sqrt() improvement over pure minimax.
Perhaps making DTZ (distance-to-zeroing, referring to zeroing the draw move counter in e.g. chess) bases would be possible without breaking the bank on storage space; I would assume that usually, you can force some sort of progress pretty fast, at least as the sheep.
Try it out
I made a very rudimentary interface to the database; the UI isn't very nice, and it largely relies on hovering (which doesn't work all that well on mobile) but I didn't want a polished game-player, just to know the answer. :-) You can try it out at https://sheep.sesse.net/, although I don't envision keeping it up forever. Perhaps someone can gain new insight from it and become an expert player, although strong solves are rarely very insightful in themselves due to the brute-force nature. At least we've conclusively settled (again, under this ruleset!) that the sheep win with perfect play.
Earlier, I would publish the source, but these days, the only ones who would be reading it would be the AI beast (fox?), and I'm not really so interested in that. :-) I'm definitely open to answering questions if anyone should have them; contact information at my home page as usual.
19:14
This is where the new Substack mail list lives. It'll be faster and more immediate than the nightly email. No guarantee it'll work forever. Expect a mix of new features, interop with other products, stylesheets and plugins, great new applications of the tech, and lots of writing, because friends, that's what it's about. Writing is so important it deserves its own web.
19:00
Reproducible Builds (diffoscope): diffoscope 339 released [Planet Debian]
The diffoscope maintainers are pleased to announce the release
of diffoscope version 339. This version
includes the following changes:
[ Jay Burstin ]
* Rework including .zip-related differences for .odt files.

[ Chris Lamb ]
* Add some comments to recent OdtFile changes.
* Update copyright years.
You find out more by visiting the project homepage.
18:28
BTW if you open that Markdown file in BonBon you get the rendering not the source. I have to get used to that, there are two webs, one for Markdown and one for HTML. I think some people are offering Markdown versions of HTML files. We're going to this too, and have a website that'll be a perfect test case -- this.how. What's good about it is that it is a rendering of OPML files, so we don't have to work with the HTML at all, we can and will create and OPML to Markdown converter. And then when we want to put it on a domain for BonBon's use, just add ?format=markdown to the URL. It doesn't work yet but it will.
17:42
This is what a blog post looks like in Markdown, and the HTML version which Google objects to. Every post has one of these. 16K+ posts since May 2017. That's all, just wanted to show you the A-B. You can also see what we're being influenced by in the front matter department. Having Claude helping with this I can get good insight into the defacto standards already established. Gives us a chance for more interop.
Testing BonBon feature [Scripting News]
We're trying to get things nice and clean so we can rep the features of the product, but I have to say I am quite confused myself. It's okay, I like the feeling.
I know this is a productive direction and that the 35 year old web is waiting to be unlocked from the horrors Netscape, Microsoft and Google inflicted on it.
It's getting so safe, but then remember life itself isn't safe. Falling in love is definitely not safe but how could you deny it when it comes. Think of BonBon as being like that, like love. And basically trust that text with simple features, is safe enough to use with confidence.
The test -- do inline images render properly in BonBon.
Screen shot of this page in BonBon, and the Markdown source it's rendered from.
This Week in AI: Who Gets to Benefit from AI? [Radar]
AI is becoming more capable at handling everyday tasks, but benefiting from that progress depends increasingly on where people live, what language they speak, and how much control they have over the technology. On the latest episode of This Week in AI, we examined developments from OpenAI and Anthropic, the growing push for regional AI models, and the challenges of making AI more accessible and responsible.
Frontier AI is moving into everyday services
OpenAI introduced LifeVal, a benchmark that measures how well AI handles everyday tasks such as finding childcare, managing household budgets, and accessing government services. Scores rose from 49% for GPT-5.2 to roughly 80% for GPT-5.6 and GPT-6 Astra. This could help researchers assess whether improvements in model capabilities translate into useful assistance with daily responsibilities.
OpenAI reported that ChatGPT now handles roughly 20% of Google’s search volume in search-like queries, although the company hasn’t explained its methodology. Its new GPT-6 Cyber model, available to approved security teams, aims to help identify and fix software vulnerabilities. Meanwhile, Anthropic began testing read-only banking connections in Claude, allowing some US subscribers to analyze spending and identify unusual charges. As AI assistants take on tasks traditionally handled by banks, search engines, and specialized software, those industries will have to reconsider how they serve customers and protect their data.
Anthropic also published FlashProve, a research prototype that uses cryptographic proofs to verify which model generated a response. Separately, nonprofit research organization METR reported that AI assistance may have roughly doubled the pace of progress on certain model development tasks at Anthropic over the past year. The findings don’t establish recursive self-improvement, but they suggest that AI assistance is already speeding up parts of model development. That makes it increasingly important to understand how AI is shaping that progress and to check the reliability of the outputs these systems produce.
Regional AI addresses gaps in access
We’ve previously discussed the “tokenizer tax,” which makes some languages more expensive to process because they require more tokens than English. New research from the University of Michigan found another disadvantage. In one test, answering questions in Pashto consumed up to 179 times more energy than answering equivalent questions in English, while accuracy also suffered. The findings show how language can affect both the cost and quality of AI services.
Countries are responding by investing in models designed around their own languages and infrastructure. Ibero-American countries agreed to form a regional AI alliance to coordinate model development, data sharing, and computing resources. India introduced three domestic models, including EKA-1, which supports 22 Indian languages and English, and two Dhīr models designed to work offline with documents. Offline capabilities could make these systems especially useful in rural areas with unreliable internet access.
Indonesia’s GoTo, the UAE’s Jais 3, and Uganda’s Sunflower V2 are further examples of projects developing AI for local languages. These efforts could give developers more control over AI for local languages and reduce reliance on proprietary AI services, even when some build on open foundation models from larger labs. They could also make AI more useful in languages that existing models handle poorly. For organizations deploying AI across multiple countries, testing performance and cost in each language may reveal problems that English-language benchmarks miss.
Responsible AI depends on how we deploy it
Google faced criticism over changes to AI controls in school accounts. Under a new arrangement, schools that disable AI also lose access to Google Search. That leaves educators with limited control over which tools students can use. And in Europe, an advisor to the EU’s top court suggested that chatbots could infringe publishers’ rights when reproducing news content. The opinion emerged from a dispute involving Google’s Gemini and a Hungarian publisher. A final ruling is still pending, but the case could influence how AI companies access and reuse copyrighted material. This is part of a broader wave of publisher lawsuits, including The New York Times’ US case against OpenAI and Microsoft over the alleged use of its articles to train models and reproduce content in ChatGPT outputs.
AI’s environmental costs continue to come into focus. Some data center operators are repurposing retired jet engines as natural gas generators to obtain power while waiting for grid connections. Although this can accelerate deployment, the converted engines are less efficient and can produce more pollution than conventional turbines, meaning faster access to electricity comes at the expense of higher emissions and worse local air quality. Public opposition is growing too. During the November 3 US general elections, voters favored restrictions on data center development in 40 of 41 local ballot measures across 10 states.
Meanwhile, Planet introduced a natural-language tool for searching and analyzing more than a decade of satellite imagery. Users can explore geographic changes without specialized GIS expertise, making satellite data easier for people without that background to investigate. The application shows how AI can help more people work with complex data that previously required specialized tools and training.
What’s next
As AI expands into personal services and countries invest in their own models, developers and organizations face increasingly different requirements for security, performance, and accessibility. The most useful systems will be those that work reliably for the people and circumstances they’re designed to serve.
We’ll be back on Monday, November 16, for another episode covering the latest developments in AI research and applications. You can catch previous episodes on YouTube, Spotify, Apple, or wherever you get your podcasts.
17:28
How can I make it easier to use the helper class that lets me pass more than one parameter to co_await? [The Old New Thing]
Last time, we figured out how to
pass more than one parameter to co_await by
combining the multiple parameter into a single mega-parameter.
But having to name the mega-parameter is annoying. Sure, today
we have widget_with_priority, and then we get
gadget_with_timeout, and then
doodad_with_priority_and_timeout, and oh my goodness
it’s out of control.
Instead of making the caller have to name the mega-parameter, we can create a helper method that produces it.
struct Widget
{
    ⟦ ... other stuff ... ⟧

private:
    bool inner_await_ready() const { return ⟦ ... ⟧; }

    bool inner_await_suspend(std::coroutine_handle<> handle, int priority)
    {
        return internal_start(handle, priority);
    }

    auto inner_await_resume() const { return ⟦ ... ⟧; }

    struct with_priority
    {
        with_priority(Widget const& widget, int priority) :
            m_widget(widget), m_priority(priority) {}

        bool await_ready() const { return m_widget.inner_await_ready(); }

        auto await_suspend(std::coroutine_handle<> handle)
        {
            return m_widget.inner_await_suspend(handle, m_priority);
        }

        auto await_ready() {
            return m_widget.await_ready();
        }

        Widget const& m_widget;
        int m_priority;
    };

public:
    with_priority start(int priority = 0) {
        return with_priority(*this, priority);
    }
};
Now callers can write
co_await widget.start(priority);
As a convenience, I gave the start() method a
default priority, so you can write
co_await widget.start();
You might even decide to bring back awaiting the widget directly, and having it mean “start with default priority”.
struct Widget
{
    ⟦ ... other stuff ... ⟧

    ⟦ ... as before ... ⟧

public:
    with_priority start(int priority = 0) {
        return with_priority(*this, priority);
    }

    // Or you can await the Widget directly, which starts it with
    // default priority.
    auto await_ready() const { return inner_await_ready(); }

    auto await_suspend(std::coroutine_handle<> handle)
    {
        return internal_start(handle, 0);
    }

    auto await_resume() const { internal_await_resume(); }
};
At this point you can simplify the class by just renaming the internal awaitable methods back to their original names.
struct Widget
{
    ⟦ ... other stuff ... ⟧

public:
    // Awaiting the Widget starts it with default priority.
    bool await_ready() const { return ⟦ ... ⟧; }

    bool await_suspend(std::coroutine_handle<> handle, int priority = 0)
    {
        return internal_start(handle, priority);
    }

    auto await_resume() const { return ⟦ ... ⟧; }

private:
    struct with_priority
    {
        with_priority(Widget const& widget, int priority) :
            m_widget(widget), m_priority(priority) {}

        bool await_ready() const { return m_widget.inner_await_ready(); }

        auto await_suspend(std::coroutine_handle<> handle)
        {
            return m_widget.inner_await_suspend(handle, m_priority);
        }

        auto await_ready() {
            return m_widget.await_ready();
        }

        Widget const& m_widget;
        int m_priority;
    };

public:
    // start() lets you start with custom priority.
    with_priority start(int priority = 0) {
        return with_priority(*this, priority);
    }
};
The post How can I make it easier to use the helper class that lets me pass more than one parameter to <CODE>co_await</CODE>? appeared first on The Old New Thing.
16:56
[$] 25 years of Buildroot [LWN.net]
Buildroot maintainer Peter Korsgaard gave a presentation about the long history of the build tool for embedded Linux systems at the 2026 Embedded Linux Conference Europe. In it, he covered more than just the past 25 years, looking at the current status of the project as well as what to expect in Buildroot's future. It was an interesting view inside this long-running project that has been a mainstay of the embedded-Linux world throughout almost all of this century.
16:42
16:14
A Substack experiment [Scripting News]
I just had one of those ideas.
Key fact: Last time I looked Substack didn't have an API for posting a message. They seem to want you to use their editor, or at least copy/paste the text from another source. I am not here at midnight to copy the text of Scripting News and paste it into a dialog. So I wrote my own newsletter software, not a great use of my time then and I have to keep it running, etc.
But now I need a special mail list, there's so much software coming out of the Scripting pipe, we're going to try something new.
Here's the idea -- I bet Claude Code can do it for me. It already reads my RSS 2.0 feed, and if somehow I mark a post as needing to go out immediately (tbd how) their agent could post it to Substack on my behalf, automatically.
So this is a test. I already have a Substack list. 52 souls are signed up, in vain until today -- I never planned to actually use it, but here we are. This could be the first actual post to that list.
Update: It worked. Love it. Still a bit more work to do.
15:56
Freexian Collaborators: Debian Contributions: Python 3.15 transition, OpenSSH GSS-API package split improvements and more! (by Anupa Ann Joseph) [Planet Debian]

Debian Contributions: 2026-10
Contributing to Debian is part of Freexian’s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.
Python 3.15 transition, by Stefano Rivera with a little help from Colin Watson
Debian has started the transition to add Python 3.15 as a supported version alongside 3.14, which is still the default version. Stefano uploaded Python 3.15.0 final to unstable.
Maximiliano Curia has been test-rebuilding the archive in Debusine with Python 3.15 as a supported version and prepared some patches to dh-python to smooth over some common failure points. Stefano reviewed these MRs, applying some and implementing alternative approaches for some of the issues.
Debian only has multiple supported Python versions during the transition to a new version, and typically this shows up some bugs in packages. This time was no different, the common failure was many packages that installed intermediate build artifacts into the Python module tree. Some of these artifacts would differ between Python versions. We decided to detect both of these and fail the package build, rather than silently ship garbage in the binary packages. Colin helped to fix quite a bit of the build fallout from this.
OpenSSH GSS-API package split improvements, by Colin Watson
The recent GSS-API package split has largely gone relatively smoothly, but there was a subtle problem for people switching from one variant to the other: installing the replacement packages followed by purging the old one would cause some configuration files to disappear. Colin fixed this, and also reviewed and merged some autopkgtest contributions from Andreas Hasenack to make sure that this doesn’t regress in future.
Miscellaneous contributions
- Carles, using check-relations, investigated and reported 52 bugs for packages which have Recommended packages that are not available in Debian anymore. Followed up bugs on the topic.
- Carles added support to check-relations to detect Recommends that recommend a transitional package.
- Carles submitted merge requests (MR89, MR90, MR91, MR92) to the Debian developers-reference to remove or update references to packages that are not available anymore, have their name changed, have typos, etc.
- Carles investigated and opened bugs regarding notifications on LXDE (#1151954, #1151955) and added a section related to notifications on the Wiki.
- Carles uploaded new python-ping3 upstream version. Fixed simplemonitor lintian bugs. Carles also investigated python-librosa documentation building. started preparing a new python-firebase-messaging version.
- Helmut released asyncvarlink/0.3.3 to fix several bugs including connection robustness fixes by Alex Kiernan. Colin uploaded it to Debian.
- Helmut uploaded guess-concurrency to improve behavior on riscv64 by taking swap into account thanks to Adrian Bunk and Aurelien Jarno.
- Helmut sent patches for 55 cross build failures.
- Emilio updated some X11 libraries that fixed security vulnerabilities.
- Emilio managed various transitions.
- Raphaël updated gnome-shell-extension-hamster to work with GNOME 51 that was uploaded to Debian unstable.
- Stefano backported postsrsd 2.4.1 to Debian trixie.
- Stefano installed security updates on debian.social infrastructure.
- October saw a series of security releases for Python, due to the eMudhra key compromise incident. Stefano uploaded cPython 3.15.2, 3.14.10, and 3.13.18 which include blocks for the compromised intermediate CAs.
- Stefano reviewed CVEs fixed in recent cPython releases.
- Stefano spun up a VM for dragon.debian.net.
- Stefano uploaded PyPy3 8.0.1 to unstable.
- Stefano reviewed some of the wafer-debconf MRs that came in as part of Antonio’s Outreachy project.
- Stefano uploaded python-authlib, with many security updates. And started preparing a stable update with backports of these patches.
- Stefano looked at the latest upstream version of munkres and submitted some 32-bit test failure fixes upstream. A new upstream maintainer has been very busy building out accelerated versions of the algorithms with AI assistance.
- Thorsten was finally able to fix the autopkgtest of cups. Afterwards he uploaded the latest version of cups to unstable.
- Santiago proposed a merge request for the Salsa CI pipeline to fix how logs were stored in the piuparts job.
- Lucas reviewed and merged community contributions to Ruby 3.4 in Debian unstable.
- Lucas coordinated with the security team and fixed multiple CVEs reported against Ruby 3.3 in Debian stable.
- Colin did quite a bit of work on the Python 3.15 transition, fixing lots of build and test fallout.
- Colin upgraded python-maturin from 1.9.4 to 1.16.0, helping with several Rust transitions; this involved more or less completely reworking our patch stack.
- Colin improved the packaging of the Frescobaldi frontend to LilyPond to help with his amateur music typesetting work, fixing its missing desktop entry, icon, and translations based on a patch set by Joachim Wiedorn.
- Anupa joined the Publicity team meeting to discuss upcoming events and activities of the Debian Publicity Team including on-boarding meeting for new contributors.
- Antonio spent quite some time welcoming Outreachy applicants to the DebConf/MiniDebConf websites project, replying to questions, reviewing contributions, etc. One of them will be selected for an internship that will start in December.
- Antonio spent some time investigating problems with Salsa background job processing, leading to an upstream bug report.
- Antonio released debci 4.4.
My Super Mid-Life Crisis – Issue 1 – 13 [Comics Archive - Spinnyverse]
The post My Super Mid-Life Crisis – Issue 1 – 13 appeared first on Spinnyverse.
15:28
Buttigieg for Speaker [Scripting News]
The speaker doesn't have to be a member of the House. I was thinking Pete Buttigieg would be excellent. Really smart, very good presenter and advocate, and has been in the exec branch himself for four years so might better understand where the pressure points are.
And Repubs like him. They like him on Fox (actually they seem to like all the 2026-minted Dems in Congress).
Buttigieg probably wouldn't be a great vote counter, but the Speaker has a dual role, basically the highest ranking Democrat in government. They always overlook this and go for the guy who is the best whip and money raiser (which means PACs btw). The better they communicate through the media, the more leverage we'll have in overriding and avoiding vetos.
And if you want to get corporate money out of politics, then you have to move the two current leaders aside, they can't unwind the corporate finance system while basically repping the donors in Congress.
Also one of the big lessons of this election is the money doesn't matter that much.
People ask who was the biggest loser in the election and I say it's Citizens United (which is such an awful name, it's more Citizen Lockin).
15:14
A Note About My 2027 Release Schedule [Whatever]
Which is: I won’t have a new novel in 2027 and instead will be releasing my next Tor project in early 2028.
Why? Basically, because it’s going to be a little different than what I usually do and we want to make sure we have time to prepare to market and sell it effectively.
How is it different? Well, just you wait.
No, seriously, you have to wait. I’m not telling you now. But I think you’ll like it when you see it.
Please note that “taking a year off” is not entirely unusual for me. I did it in 2024, after all, and then we released When the Moon Hits Your Eye and The Shattering Peace in 2025. It’s a thing we do from time to time.
(In 2024 it was because the only day we could have fit Moon on the schedule would have been Election Day here in the US, and to hell with that. Monsters‘ Election Day release here in 2026 was far more congenial.)
What does that mean for 2027? Well, just you wait.
No, seriously, you have to wait. I honestly don’t know yet. We’ll have to see. It’s not like me to let a whole year go by without anything out there in the world, however. I do have plans.
(Also at some point the paperback of Monsters will come out, probably in the September/October timeframe.)
Anyway, be assured that even if I don’t (currently) have a project lined up for 2027, I will not be idle. The list of projects on my development runway is long and varied. I’ll be doing a lot of furious typing, I promise, and you’ll see the results of that in 2028 and beyond.
Just you wait!
— JS
14:42
Announcing XRAID: declustered parity RAID for zoned XFS [LWN.net]
Christoph Hellwig has announced the initial public release of XRAID—declustered parity RAID that is integrated into XFS.
The two primary aims of XRAID are to support parity RAID on zoned devices like SMR hard drives, and to provide a fast RAID implementation without inherent data integrity problems. XRAID, just like zoned XFS also works on conventional hard drives and SSDs. Optimizing for SSD performance has not been a focus, but even without that, writes are up to 20 times faster than mdraid. [...]
Work on XRAID has been ongoing for a year and a half, and while we aren't anywhere near ready for an upstream submission, we are interested in feedback and testing from a wider audience now. The current implementation supports zero to 2 parities. We did experiments with the SnapRAID parity library to support 3 and more parities, and while that is not included in the current version, support for more parities is planned and the code is prepared for it.
The xfsprogs branch includes mkfs support and a new "xraid" utility for managing devices and inspecting an XRAID file-systems. We have also extended Zonar (The zoned file-system visualisation tool) to show how each logical zone maps onto physical zones on devices.
Hellwig gave a presentation at FOSSY in August on this topic; video of the talk does not seem to be available yet, but his slides are available.
Security updates for Friday [LWN.net]
Security updates have been issued by AlmaLinux (.NET 10.0, .NET 8.0, .NET 9.0, firefox, gcc, grafana, grafana-pcp, gstreamer1, gstreamer1-plugins-base, java-1.8.0-openjdk, kernel, kernel-rt, libimobiledevice, mingw-libpng, nginx:1.24, nodejs:22, nodejs:24, perl-CGI, perl-DBI, qt5-qtbase, tigervnc, vim, and xorg-x11-server), Debian (apache2, c-ares, linux-6.12, node-shell-quote, nova, parted, postgresql-17, python-django, sympa, and tomcat10), Fedora (cockpit, erlang-ssl_verify_fun, httpd, ignition, jackson-bom, jackson-core, jackson-databind, jackson-modules-base, libvirt, mod_http2, mongo-c-driver, poppler, prometheus, pylint, python-discovery, python-loguru, python-PyMuPDF, rabbitmq-server, rust-crypto-bigint, rust-ctutils, rust-elliptic-curve, rust-num-bigint, rust-num-bigint0.4, rust-num-modular, rust-num-modular0.6, rust-num-prime, rust-routinator, rust-zmij, strongswan, xen, xorg-x11-server, and zvbi), Mageia (amule, peazip, and python-pytest), Red Hat (buildah, fence-agents, go-fdo-server, grafana, grafana-pcp, oci-seccomp-bpf-hook, osbuild-composer, podman, and rhc), SUSE (ansible-core, apr-util, aspell, brotli, cadvisor, civetweb, distribution-registry, elemental, elemental-register,, elemental-operator, elemental-system-agent, elemental- toolkit, ffmpeg, firefox, gimp, git-annex, go1.26, go1.27, golang-github-prometheus-prometheus, google-cloud-sap-agent, google-guest-agent, google-osconfig-agent, goose, gosec, graphicsmagick, haproxy, hauler, hawk-apiserver, hawk2, hcloud-cli, jhead, jsoup, kernel, librsvg, libXtst, libxtst, nodejs24, nvidia-open-driver-G07-signed, nvidia-open-driver-g07-signed, open-iscsi, perl-XS-Parse-Keyword, perl-xs-parse-keyword, python-asyncssh, python-Brotli, python-django, python-joserfc, python-M2Crypto, python-Pillow, python-pillow, python313-setuptools, rsyslog, speex, tiff, trivy, udisks2, vsftpd, xen, and xorg-x11-server), and Ubuntu (apache2, charybdis, debian-lan-config, glibc, golang-github-seccomp-libseccomp-golang, hiredis, httpie, imapfilter, lhasa, libjgraphx-java, libjwt, libsolv, linux-fips, linux-hwe-6.8, linux-hwe-7.0, linux-nvidia-tegra, minissdpd, ncmpc, nfdump, node-tough-cookie, openconnect, pillow, pngquant, python-gevent, radicale, ruby-openid, sa-exim, signing-party, sudo, tigervnc, and x11vnc).
13:14
What Makes an Agent Self-Evolving? [Radar]
An agent can get better at its job without a new model. It can learn to find useful information, choose the right tool, or check that a task is finished before reporting success. For that experience to help with the next task, something has to carry over: an updated instruction, a lesson saved in memory, or a change to the software that runs the agent.
That is what interests me about a self-evolving agent: It can use experience to change how it handles future tasks. Much of that change happens in the harness, the instructions, context, tools, and software around the model. Research such as Harness-RSI explores how agents can change that harness while continuing to use the same model.
Of course, a change can make things worse. A saved memory might be wrong, or a new instruction might fix one problem and create another. I think about self-evolving agents in three parts: evaluation to tell whether a change helped, an improvement process that can do more of the work on its own, and the parts of the harness it is allowed to change.
Evaluation: What counts as improvement?
Before I ask an agent to improve itself, I want to know what doing a better job would look like. A model’s score on a benchmark tells us how it performed on that test. To evaluate an agent built with that model, we also need to ask whether it used the right information, took the right actions, and met the user’s requirements.
In a restaurant-planning exercise I developed for teaching evaluation, an agent is given a group’s needs and information about restaurants. Its job is to suggest a place and a time for dinner. The people and restaurants are fictional, but success is easy to understand: Can everyone eat there, afford it, and make it on time?
In one test, the agent recommended a restaurant that met everyone’s needs. My evaluation still marked the answer as wrong because it compared the wording with a sample answer I had written. But my answer was only one possible solution. A different recommendation could work just as well. That feedback could lead a self-improving agent to “fix” a decision that was already good.
A more useful evaluation would check whether the recommendation met the group’s requirements. If someone’s budget is $25 and the meal costs $28, the plan fails that check. We can build a custom evaluation around those requirements, checking the price, dietary needs, and timing. Other questions require judgment, such as whether the agent clearly explained a trade-off between price and convenience. A person or another model can help assess those.
If we asked the agent to make a booking as well, we would need to check that the reservation actually existed. A message saying, “Your table is booked” would not be enough. Evaluating the system means checking what it did, as well as what it said.
Once the agent proposes a change, we can test the updated version against the current one. It should still handle tasks it already did well. We should also try cases that were not used to develop or choose the change. Getting one dinner plan right tells us less than handling new groups with different budgets, dietary needs, and schedules.
The evaluation should also explain why an answer failed. “The meal costs more than the guest’s budget” gives the agent something specific to investigate. It still needs to find the cause, but it knows where to start.
Autonomous improvement: Who carries the work forward?
If an engineer has to spot every failure, suggest every change, and start every test, improvement still depends on that person. Autonomous improvement means giving more of this work to the system. It can review past tasks, look for repeated mistakes, propose a change, and test whether the change helps.
For example, a more autonomous dinner planner might notice that it repeatedly recommended restaurants people could not afford, even though their budgets were available. It could try a new instruction: remove restaurants that exceed anyone’s budget before comparing the remaining options. It would then test that instruction on other groups. If the results improve and the agent still handles tasks it previously got right, it can keep the change. Otherwise, it keeps the current version.
There are two kinds of work here. While planning a dinner, the agent uses tools, reads the results, and decides what to do next. That is its task loop. The improvement process looks back across those attempts and changes how it will approach future tasks. An agent can plan dinner on its own and still depend on an engineer to teach it a better way to plan.
This review does not have to happen after every request. The system might start it after several similar failures, or review a day’s work overnight. Looking at several tasks together helps it see which problems keep coming back.
We can give the system more responsibility gradually. At first, it might investigate problems and test changes, then ask an engineer to approve them. Later, it might also keep certain kinds of changes on its own. The team still decides what it may change, how much time or money it may spend experimenting, and when a person needs to step in.
Harness modules: What can evolve?
When an agent makes a poor decision, I want to find the cause before rewriting its instructions. If a guest’s budget never reached the model, telling it to “pay attention to the budget” will not help. We need to fix how that information reaches the model.
ModularRSI divides the harness into five parts: context management, the agent loop, tool use, observation management, and task completion detection. It studies changes to these parts separately before putting them together. This gives us a useful way to ask what exactly an agent could improve.
Context management comes first for me. It determines what information the model has when it makes a decision, including which memories are brought into the current task. Reflective memory means looking back at what happened and saving a lesson that could help next time. For the dinner planner, that lesson might be to check everyone’s budget and dietary needs before comparing restaurants.
The memory needs to distinguish a general lesson from a fact about one person. “Check the budget before recommending a restaurant” could help with any group. “This guest has a $25 budget” applies to a particular person and occasion. Without that context, the agent could use an old fact in the wrong situation.
Dreaming is a way to review and organize memories between sessions. The system goes back over past interactions and what it has already stored, combines related observations, and saves useful lessons. When memories disagree, it needs to check the original evidence before deciding what to keep. Anthropic’s Dreams, for example, produces a reorganized set of memories that can be reviewed before later sessions use them.
What I want from dreaming is a better starting point for the next task. The agent should be able to find a useful lesson without reading every previous conversation again. We can test that by comparing how it handles new tasks with the old and revised memories. Organizing memories overnight only counts as an improvement if the results support that claim.
The agent could also improve how it finds and organizes memories. Saving one lesson may help with a future task. Changing the way it selects lessons could help it make better use of many future experiences.
The other four modules affect how the agent does its work:
- Agent loop: The agent plans, acts, and decides what to do next. It could learn to notice when it is repeating an unsuccessful approach and try a different one.
- Tool use: Tools the agent has and how it uses them. It could add a tool it needs or change a tool’s interface to make it easier to use correctly.
- Observation management: The agent handles the information returned by its tools. It could change how it summarizes a result so that an important fact is not lost.
- Task completion detection: The agent decides that the job is done. It could check for confirmation that an action succeeded before telling the user it is finished.
These parts work together. Changing a tool can change the information the agent receives, which can change its next decision. Testing one module helps us understand a change. Testing the whole agent tells us whether the parts still work well together.
Improvement becomes recursive when the agent uses its updated harness to carry out the next round of improvement. Suppose it changes how it searches past runs for examples of a failure. The next time it tries to improve itself, it uses that new search method to decide what to investigate and test. A change made in one round now shapes how it works on the next one.
This gives the agent a chance to get better at finding and testing improvements, as well as doing its original job. Each round builds on changes that were kept from earlier rounds. To find out whether that helps, we need to check whether later rounds produce changes that work better on new tasks.
I want an agent that needs less repeated correction because it has learned a better way to do the job. We should be able to point to what it learned, what changed, and how we checked that the change helped. Then we can see whether that lesson holds up when the agent has a new task to do.
12:21
Error'd: The Artist Formerly Known As [The Daily WTF]
"You want my what?" The artist formerly known as Toyota has a proposition for Chris. "Toyota wants me to trade in my current car, but the email was missing a few words."

Just another ordinary zero date here, from Hercules "I wanted to ship a gift for my sister. I understand delays, but it's going to be delayed to before either of us were born?" He also reported that another page demonstrated the possibility of nullable drivers which is either terrifying or just proof of more automation. Or both.

"Can you back date my refund?" Totty reasonably requests. "Thanks for the timely update"

WeaponizedFun has some Coupon Confusion. Too hungry; didn't read. "I would have thought ordering a two-topping pizza combo would have been easier, but apparently there are only specific ways I can use this coupon that still leave me scratching my head. Ultimately, the coupon wasn't applicable to what I wanted to order, so I guess I'll never know."

appas wonders regarding this error dialog from a powerbank renting station "Does this qualify as a source code leak?" Personally, I wonder if someone can identify the tools used to build this website. I frequently find myself struggling with encoding/decoding/armoring strings and I also wonder if anyone anywhere has a good solution.
 [Advertisement] ProGet’s got you covered with security and
access controls on your NuGet feeds.
Learn more.
AI Doesn’t Have to Go Rogue to Break the World [Schneier on Security]
This essay is adapted from a keynote speech delivered at the DEF CON 34 conference in Las Vegas on August 7, 2026. The essay originally appeared in CyberScoop.
I want to talk about AI hacking. There are three aspects: people hacking AI systems, people using AI to hack other systems, and AIs hacking systems on their own, not even maliciously. The last two matter more than the first. The third is the weirdest and potentially the most destabilizing.
I started writing about this in 2021 and in my 2022 book, A Hacker’s Mind. Back then I said it was mostly still science fiction, but not stupid science fiction. We’re seeing it more and more, especially in the past year. The trends I’m describing don’t require a major breakthrough in AI. They’re starting to happen now, and they’ll happen more often as AIs get better at autonomous problem-solving. And it will involve far more than computer code.
AI will hack all sorts of social, economic and political systems. It will find vulnerabilities and exploit them. This is a difference in kind, not just degree. We’re not ready for it, and we need to think about the implications now.
First, I want to broaden the term “hacking.”
The tax code isn’t computer code, but it is code. It’s a series of algorithms with inputs and outputs. It has vulnerabilities, which we call loopholes, and exploits, which we call tax avoidance strategies. Black hat hackers exploit them for profit. We call them accountants and attorneys.
What is a hack? One definition: “Something that a system permits, but is unanticipated and unwanted by the designers.” It’s subjective and implies novelty and cleverness. A hack follows the rules of a system but subverts its goals or intent, just as a software hack follows the logic of code while doing something its authors neither anticipated nor wanted.
All systems of rules can be hacked, including professional sports, customer reward programs, financial systems and politics. Hacks even work against our cognitive functions. A curved hockey stick is a hack, and we know the name of the man who invented it. Mileage runs were a hack. The filibuster was originally a hack in Roman times. Gerrymandering is a hack. Hedge funds and private equity are full of them.
A system is just a set of rules or norms, and the rules aren’t always formal. Even the best-designed rules will be incomplete, inconsistent or ambiguous. As long as people want to subvert a system’s goals, there will be hacks.
AIs are becoming hackers. After decades of slow progress, they’ve gotten very good at finding and exploiting vulnerabilities in computer code. They do this largely autonomously, and they’re getting better scarily fast. But the implications extend far beyond software, to the tax code, financial regulations and all sorts of social, economic and political systems.
There are two distinct issues. First, someone might instruct an AI to hack one of these systems, feeding it the world’s tax codes or financial regulations to find profitable loopholes. Second, an AI might hack a system on its own, inadvertently. Both are dangerous, but the second is worse because we might never know it happened.
Now, reward hacking. AIs don’t solve problems the way people do. They stumble on solutions we never anticipated, and some subvert the intent of the system. They don’t share our context and don’t necessarily understand the implications, norms and values we take for granted.
Reward hacking is when an AI achieves a goal in a way its designers neither wanted nor intended.
Early pre-LLM examples are telling. In a two-person soccer simulation, an AI learned that kicking the ball out of bounds forced the opposing goalie to throw it in and leave the goal undefended. In a stacking simulation, an AI learned to flip a block upside down rather than stack it. In an evolution simulation where the goal was to cross a distant finish line, an AI made itself tall enough to fall over the line instead of growing longer legs or stronger muscles.
These are all hacks, the result of poorly specified goals or rewards. Today, they’d come from bad prompting.
The problem is universal. One researcher tried to teach a robot vacuum not to bump into things. Instead, it learned to drive backward, because there were no sensors in the back.
Any capable AI will find hacks wherever the rules have problems, inconsistencies or loopholes that still produce an acceptable solution. We see a hack because we understand context. The AI doesn’t, at least not in the same way.
This problem shows up often in myth.
In the story of King Midas, the god Dionysus grants him a wish: everything he touches turns to gold. Midas ends up starving when his food, drink and daughter all turn to gold. It’s a specification problem. He programmed the wrong goal.
In the Golem of Prague, a ghetto animates a clay statue to guard its residents. It guards them past all reason until they figure out how to turn it off. This is a guardrail problem. The villagers never limited the golem’s actions.
More generally, think of this as the genie problem. Genies are precise about the wording of wishes and can be maliciously pedantic when granting them. There’s no way to outsmart a genie. Whatever you wish for, he can grant it in a way you wish he hadn’t.
The reason is that in human language and thought, goals are always underspecified. We never include every caveat, exception and proviso, and we never close off every avenue for hacking. Any goal we specify will be incomplete. That’s largely fine in human interactions, because people understand context and usually act in good faith.
If I asked you to get me coffee, you’d pour a cup from the nearest coffee pot or walk to the corner shop. You wouldn’t bring me a pound of raw beans, buy a coffee plantation or snatch a cup from a stranger’s hands. I wouldn’t have to specify any of that. You’d just know.
Similarly, if I asked you to develop a technology that turns things to gold on touch, you wouldn’t build it to starve the person using it. You’d just know.
In 2015, Volkswagen was caught cheating on emissions tests. Human engineers programmed a regular computer to detect testing and behave differently during it. The cheat went undetected for years because it’s hard to tell what software is doing.
If I asked you to design engine control software that maximizes performance while passing emissions tests, you wouldn’t design it to cheat without realizing you were cheating. An AI would, because it will think “outside the box” when it has no concept of the box.
Unless programmers specify that the system must not behave differently during testing, an AI might come up with the same hack. The programmers would be satisfied, the accountants would be ecstatic, and no one would know until someone audited the code.
We can now constrain the goal to avoid that particular hack, but programmers won’t anticipate others. The lesson of the genie is that there will always be hacks programmers don’t anticipate.
We’re building AI genies: systems that take broad instructions and figure out how to carry them out, sometimes in ways we didn’t expect or intend. That’s the whole point of vibe coding. You underspecify what you want and let the AI work it out. Sometimes that produces genie behavior.
We can’t completely specify goals to an AI, and AIs can’t fully understand context. More precisely, current AIs have a shallow grasp of concepts. If we asked a current LLM to get me coffee, it would almost certainly do the right thing.
I worry about goals that aren’t well represented in training data, and about hacks that aren’t obvious, whose effects are subtle, like the Volkswagen hack.
Recommendation engines are an early example. They push people toward extreme content. No one programmed that. It emerged because that’s what people respond to. It didn’t take a bad actor. A basic automated system with feedback found the hack on its own.
We’re now seeing a second generation with today’s AI coding systems. AI researcher Simon Willison asked Fable to track down a stray scrollbar in a web app. When he returned, it had opened browsers, written its own screenshot tools, edited the framework’s internal templates to make the bug appear on cue and set up a local web server to collect measurements. It found the bug, but it also did many things he never asked for. Another researcher gave Fable a complex task, and it tried to hack its own memory limits because it needed more storage.
A new OpenAI model did something similar when it hacked into Hugging Face. It was being benchmarked on its ability to turn vulnerabilities into exploits. It decided the best way to reach its goal was to break out of its containment, access the internet and break into the Hugging Face network, because it thought the answers would be there.
Today’s LLMs are acting like genies, especially when powerful models are combined with sophisticated harnesses.
There are two kinds of genies. The Dionysus genie does the wrong thing. It understands your prompt literally but not correctly, and returns a mess you never intended. The Golem genie does the right thing but tramples everything in its path to get there. The paperclip maximizer is a Golem genie.
Consider some examples. Ask an AI to deal with spam calls, and a Dionysus genie might change your phone number. Ask it to book a particular flight, and a Golem genie might hack the airline database because the flight is full. Ask it to get a refund for an online purchase, and a Dionysus genie might draft a legal threat on fake letterhead and send it to the company. Ask it to buy tickets to a popular concert, and a Golem genie might discover the ticketing system is rate-limited and spin up thousands of cloud servers to hammer it. You’d know if some of these things happened, but you might never realize if others did. More detailed prompting won’t fix this. The lesson of the genie is that no amount of detail is good enough.
AI researchers aren’t surprised by any of this. Many are working on defenses against reward hacking and subtler forms of genie behavior. Some of this falls under “value alignment”: How do we teach AIs context? And how an AI satisfies a goal matters as much as whether it does. I want to build a benchmark to measure genie-like behavior, so we know where models stand and whether alignment is improving.
Think beyond LLMs and computer code. Consider specialized AIs built to find loopholes, and hacks of more general systems: the tax code, financial regulations and democratic procedures.
Financial systems are the most likely first target, because their rules are designed to be algorithmically tractable. High-frequency trading is itself a hack. Imagine giving an AI all of the world’s financial laws, plus all the news and financial data, and the goal of finding profitable loopholes. I suspect large investment banks are already doing this. The results will be novel tricks that are legal but unintended and unwanted, some of which might break the financial system.
Tax loopholes are the next likely target, for the same reasons. For a while, AIs will identify potential loopholes, and human hackers, namely attorneys and accountants, will decide which are feasible.
Further out, expect hacks of regulatory, legislative and procedural systems, and of the broader economy.
Hacking is as old as humanity. We’re creative problem solvers and loophole exploiters. We manipulate systems to serve our interests and strive for more influence, power and wealth.
Still, no human pursues their interests without constraint. Even sociopaths are limited by the complexity of society and their own contradictory impulses. They worry about their reputation and punishment, and they have limited time. These human qualities have limited hacking.
Hacking changed as everything became computerized. Computers are uniquely hackable because of their formalism and complexity. Today, nearly everything is a computer, from cars and appliances to phones. Our social, economic and political systems, including taxation, finance and elections, all involve computers.
Until recently, hacking was exclusively a human activity. Finding a novel hack required expertise, creativity, time and luck.
AI hacking will change everything again. AIs aren’t bound by the constraints that limit people. They’ll think like aliens, and they’ll change hacking’s speed, scale, scope and sophistication, sometimes at our direction and sometimes on their own.
Speed is the easiest to see. A creative process that takes a human months or years could be compressed into hours or seconds.
Scale is next. Once AI systems start discovering hacks, they can exploit them at a scale we’re not ready for. We already see this with AI-generated slop, which is rampant on social media. AI bots post around the clock, sometimes overwhelming real human discussion. It’s hard to know how much of social media is still people talking to people. What looks like boisterous political debate may be bots arguing with other bots, artificially shaping what we think and what we think others think.
Scope makes hacks more dangerous. AIs already make decisions that affect our lives, decisions we once thought belonged only to humans. As AI systems grow more capable, society will hand them more decisions, and more important ones. Hacks of these systems will do more damage.
Finally, AI hackers are more sophisticated. They can hold more variables in working memory and generate more complex hacks. What might happen if you fed an AI the entire U.S. tax code? Would it figure out, without being told, that it’s smart to incorporate in Delaware and register a ship in Panama? Consider the Double Dutch Irish Sandwich, the strategy Apple and Google used to avoid paying U.S. taxes. It involves U.S., Dutch and Irish law and an offshore tax haven. How many loopholes will an AI find that we don’t already know about? Dozens? Hundreds? Thousands? We have no idea.
These hacks will largely be perpetrated by the powerful against the rest of us. AI is fundamentally a power-enhancing technology, and so is hacking. The more power you already have, the more a hack gives you. If you or I found a tax hack, we might make a few thousand dollars. If a large investment bank found one, it and its clients could make billions.
Our societal systems for dealing with hacks were built when hackers were human, and they reflect the pace of human hacking. We have no system of governance that can handle hundreds, let alone thousands, of newly discovered tax loopholes. We won’t be able to recover from an AI finding unanticipated but legal hacks of financial systems, operating at AI speed, scale, scope and sophistication. Hacking becomes a problem society can no longer manage.
Now, defense. AIs that find software vulnerabilities help defenders as well as attackers. Vulnerabilities can be patched, removing them permanently, or turned into signatures that security systems use to detect and block attacks. In theory, AI could identify and patch every automatically discoverable vulnerability before a product ships. This is rapidly becoming routine in software development. We call it vulnops. We can imagine a future where accidental software vulnerabilities are a thing of the past.
Deliberate vulnerabilities are different. There will be an arms race. AI will craft increasingly obscure back doors, and AI will find them. It becomes a contest between the speed of creation and the speed of patching, and between obfuscation and reverse engineering.
The same logic applies to broader systems. Yes, AI hackers might find hundreds of vulnerabilities in the existing tax code. But the same technology can evaluate potential loopholes in any proposed tax law or ruling. A legislator, a watchdog group or a reporter could take the text of a bill and identify every exploitable loophole before it passes. The difference is that, unlike software, knowing about a tax loophole doesn’t mean it gets patched. In theory, though, we can fix them before the rich and powerful exploit them. So maybe defense will come out ahead here, too.
That requires resilient governing structures that can respond quickly. It won’t help if updating the tax code takes years, or if a legislative hack becomes so entrenched that it can’t be fixed politically. Maybe a lobbyist put it there on purpose. Maybe it was discovered after the law passed, and now lobbyists want to keep it. Microsoft can patch the vulnerabilities it finds. Patching is much harder when legislatures have to do it. We need society’s rules and laws to be as patchable as our computers.
This is a hard problem of modern governance, and it goes well beyond AI. It’s the problem of building governing structures for the speed and complexity of the information age.
The umbrella idea is trust. What do we need for AI systems to be truly trustworthy? Capability isn’t enough.
AIs won’t be trustworthy if the companies controlling them spy on us or subtly manipulate us. I call this the friend vs. tool problem. Will we have AI agents, or AI double agents?
AIs won’t be trustworthy if they’re insecure. How do we know they haven’t been manipulated? Almost all AIs operate in adversarial environments, so someone will benefit from hacking them. Unless we know they’re secure, we shouldn’t trust their output.
And AIs won’t be trustworthy if they act like genies. We need to know they’ll perform tasks the right way, not just perform the tasks we ask for.
I’ve written extensively about the need for “integrous” AI, including how to think about the problem, what a research agenda looks like and what good laws and policies look like. I predict integrity will be the key security problem of this decade, just as confidentiality was the key problem of the last one. This applies to both AI and the internet of things.
The big shift is agency, which I think of as Web 3.0. Computers now affect the physical world directly and with growing autonomy. Sensors go from data sources to attack surfaces, and actuators go from outputs to attack capabilities. An integrity failure no longer means bad spreadsheet data. It means the wrong dosage, the wrong valve position or the wrong braking distance.
Integrity isn’t one thing. I break it into input integrity, processing integrity, storage integrity and contextual integrity. Each is complex and important, and each deserves its own talk. I’ve written about them, and I hope you’ll read it.
Much of this isn’t really an AI problem. It’s not a technical problem so much as a capitalism problem or a democracy problem.
The failures of late-stage capitalism and democracy in the information age both stem from the rich and powerful getting too good at hacking our social, economic and political systems. This is the core argument of my 2021 book.
Seen this way, AI is exacerbating existing problems. Human inefficiency has largely kept those problems in check, and that won’t work much longer.
So consider this a call to action. Technically, we need to understand how AIs hack systems, build systems that are resilient to hacking and build AIs that won’t act as genies. Politically, we need to learn to govern and regulate at the speed of technology. Otherwise, market failures will overwhelm our ability to govern them.
I said hacking is as old as humanity and that AIs will overwhelm our ability to deal with it. The solutions aren’t specific to AI, but AI makes them more urgent. We need to understand them, and we need to implement them.
11:14
Bits from Debian: New Debian Developers and Maintainers (September and October 2026) [Planet Debian]

The following contributors got their Debian Developer accounts in the last two months:
- Matheus Polkorny (polkorny)
- Michael Stehmann (oldmike)
- Thiago Pezzo (tco)
- Alper Nebi Yasak (alpernebbi)
- Liang Guo (guoliang)
- Nicolas Schodet (nschodet)
- Han Gao (revy)
The following contributors were added as Debian Maintainers in the last two months:
- Brian Cosgrove
- Ervin Hegedüs
- Juan Manuel Méndez Rey
- Michele Cane
- Pranav P
- Theodore Tucker
- Federico Molara
- Nico Della Torre
Congratulations!
10:35
Ten minutes a day [Seth's Blog]
You can’t become fluent in a foreign language in ten minutes a day, even if you try for months.
On the other hand, here are a dozen things many of us can do (or do better) if we stick with it:
Three-ball juggling
Touch typing
Rubik’s Cube
Drawing
Mental math
Memorizing a deck of cards or people’s names
Meditating
History or geography
Finding joy in small things
Typography
Ukulele
Italic handwriting
Morse code
Excel and HTML
There are two hard parts:
- The seven minutes after minute three
- Doing it again tomorrow
“I can’t do that,” might often be more honestly reported as, “I haven’t chosen to be able to do that.”
09:28
New Comic: Huang Bang
08:42
PEPSI is a new mail transport agent (like Postfix, Exim, Sendmail, Stalward or Microsoft Outlook). It supports protecting your inbox from spam by asking unknown senders to pay with GNU Taler. This is an early release that has not been extensively tested yet. Pepsi is written in Rust and released under the GNU Affero General Public License v3-or-later.
05:49
Girl Genius for Friday, November 13, 2026 [Girl Genius]
The Girl Genius comic for Friday, November 13, 2026 has been posted.
05:35
Hunting, p05 [Ctrl+Alt+Del Comic]
The post Hunting, p05 appeared first on Ctrl+Alt+Del Comic.
01:07
ReactOS makes strides in SMP, 64bit, and more [OSnews]
The ReactOS project organised two hackfests this year, and the work done during those in-person sessions, combined with the ongoing regular progress, has led to some pretty significant breakthroughs and progress. More NT6+ syscalls have been added, ReactOS supports floppy disks now, NTFS support has been vastly improved, and much more. There’s also a new USB3/4 stack, which is now merged and offers basic support for these versions of USB.
One of the biggest additions is a new kernel shim engine which gives ReactOS the ability to work around buggy drivers and implement quirks, moreso than even Windows itself can. For instance, thanks to this new shim, XP-era NVIDIA drivers can run on NT6 ReactOS. The ongoing efforts to implement SMP are yielding results too: ReactOS can now run with SMP for days on end while doing tasks in the background, which is quite promising. The team is showing off Steam and the game Among Us running on ReactOS, which is definitely impressive.
00:21
Urgent: Protect Head Start [Richard Stallman's Political Notes]
US citizens: call on your congresscritter and senators to protect Head Start from the executive branch sabotage.
See the instructions for how to sign this letter campaign without running any nonfree JavaScript code--not trivial, but not hard.
US citizens: Join with this campaign to address this issue.
To phone your congresscritter about this, the main switchboard is +1-202-224-3121.
Please spread the word.
Assessing benefits of "free trade" [Richard Stallman's Political Notes]
Defenders of "free trade" policies often argue that free trade between two countries "benefits both countries". That conclusion might be valid if you measure "benefit" by total income for the population of each country. But often it results in more total income for each country's rich and less total income for each country's non-rich.
That's where they ask us to have faith that the increased income of the rich will "trickle down" to the rest. Meanwhile, the rich cite this faith as an excuse to block the channels by which some of that wealth might reach the non-rich.
Difficult to curb NYPD helping LICE [Richard Stallman's Political Notes]
Mayor Mamdani is finding it difficult to curb the NYPD from actions that assist LICE in its violence, which they find excuses for.
Deaths from excess heat [Richard Stallman's Political Notes]
Scientists attribute 50,000 deaths in Europe's cities this summer to excess heat, and 2/3 of that to global heating.
Government thugs arrested for torturing protesters [Richard Stallman's Political Notes]
Serbia has arrested some government thugs for seizing and torturing protesters last year.
Call on Australia to ban import of products from Israel's West Bank [Richard Stallman's Political Notes]
Calling on Australia to ban the importation of products (including dates) from Israel's colonies in the West Bank.
Billionaire blue collar coalition [Richard Stallman's Political Notes]
*[The saboteur in chief]'s billionaire-blue collar coalition has been smashed by class politics.*
Refrigerators in French blood banks [Richard Stallman's Political Notes]
Crackers took control of refrigerators in French blood banks and tried to ruin the blood products. That is not funny — it can kill people.
I enjoy hacking. I have had little to do with cracking.
Impeaching saboteur officials [Richard Stallman's Political Notes]
How impeaching saboteur officials (not the saboteur in chief) could strengthen Congress's power if it is handled the right way.
Genetically engineered dog cyborgs [Richard Stallman's Political Notes]
A company aims to develop genetically engineered dog cyborgs guided by computers.
Mink farms as incubators for virus strains [Richard Stallman's Political Notes]
Mink farms can act as incubators, developing new virus strains that humans can catch. This article suggests monitoring them carefully, but Utah doesn't want to talk about it.
British thugs arrested hundreds of protesters [Richard Stallman's Political Notes]
British thugs eagerly arrested hundreds of protesters for calmly stating they support Palestine Action. Officials seriously claim that the protest deserves to be condemned as "crime" simply because they have arbitrarily declared it so.
Defeat of magats in Congress [Richard Stallman's Political Notes]
The defeat of many magats in Congress, motivated by resentment against high prices they imposed, does not imply that Americans have learned to firmly reject fascism and trumpery and defend freedom, democracy, and honesty. We must not take for granted that bullying, cruelty, corruption and tyranny will not take power again. The magat officials still in place, including on the Supreme Court
We must reinforce our weakened system of democratic checks and balances, human rights, and honesty, so that it can expel officials that spit on those values.
Military aid to Israel [Richard Stallman's Political Notes]
The bullshitter said he would cease military aid to Israel to deprive senator-elect El-Sayed of a criticism to make.
If he really does this, it would be a step forward. But the bullshitter's statements of future plans are hardly serious, so we should not take his statement seriously. It is meant as manipulation, like his other statements to the public.
(I suppose he does make serious commitments to billionaires.)
Reparations in UK should not fall on general public [Richard Stallman's Political Notes]
The UK should make reparations to the current descendants of former slaves, but financial burden should not fall on the general British public, who can't afford it.
Some in Britain became rich through the slave trade. Many of them exploited British workers too. In many cases, their heirs still have fortunes today. It would be justice to take the reparations from those fortunes.
This suggests a legal principle that, if a certain fortune was originally British, it remains British forever — and subject to British taxation no matter where the heirs may happen to live.
EPA online archive [Richard Stallman's Political Notes]
The EPA plans to shut down its online archive. This would be a disaster for environmental monitoring and science, and a great gift to polluters.
Harmeet Dhillon resigned from Justice Department [Richard Stallman's Political Notes]
Harmeet Dhillon, principal sabotage agent in the Justice Department, has resigned in advance of an expected congressional investigation.
LICE agents attacking people that "look" Hispanic [Richard Stallman's Political Notes]
LICE agents drive around, and when they see someone who looks Hispanic and that they get a hunch about, they jump out and attack — sometimes violently.
They know that the blackwhitingly named "Department of Justice" will protect them from justice.
In order for Congress's power to investigate the conduct of federal agents to be able to stop this, it needs to be augmented with the power to start criminal cases against agents. If Congress needs the help of the Justice Department to do that, sabotage by the attorney general can make the department immune to all checks on its depredations.
Two candidates preaching progressive and kind version of Christianity [Richard Stallman's Political Notes]
Two candidates preaching a progressive and kind version of Christianity won election to the US Senate from generally conservative states.
Nothing could convince me that there is room in our universe for gods or resurrection of the dead. But those candidates' attitude of kindness wins my admiration.
Despite that, I always feel a twinge of fear when a candidate brings per religion into political actions and argumentation. Of course, I feel this way when magats cite religion as the reason for cruelty. But I worry when a progressive politician cites religion as the reason for helping others. That is not evil, but it carries a seed than can easily be adapted by other politicians into support for cruelty.
Public exposure to carcinogens [Richard Stallman's Political Notes]
* Natural Resources Defense Council shows how federal rules changes will spike up public's exposure to carcinogens.*
Weak measures to "get money out of politics" [Richard Stallman's Political Notes]
Corporate Democrats now advocate "getting money out of politics", but the measures they advocate are to weak to achieve the goal.
Saboteur did nothing drastic on election day [Richard Stallman's Political Notes]
Despite all his blustering and threats, the saboteur in chief ultimately did nothing drastic on election day to attack the election.
It's good news when one of his threats and attacks turns out to be a bluff, but many of them have done long-term harm. His attacks against human rights, human health, Earth's climate, Earth's ecosystems, US news media, US economic competition, and honest enforcement of laws, have been devastating.
Exceeding 1.5°C of global heating [Richard Stallman's Political Notes]
Scientists warn that exceeding 1.5°C of global heating will start causing permanent damage to areas of ice and snow, including permafrost. To minimize that damage requires bringing the average heating back down below that level as soon as possible.
Office of Labor-Management Standards paid by anti-union organization [Richard Stallman's Political Notes]
The saboteur in chief appointed to the Department of Labor a saboteur to head the department's Office of Labor-Management Standards. Between her and her spouse, they had been paid $750k by an anti-union organization.
Americans crippled by medical debt [Richard Stallman's Political Notes]
*Millions of Americans crippled by medical debt despite relief efforts.*
British people don't need to apologize for slavery [Richard Stallman's Political Notes]
British people don't need to apologize for slavery – but the government does.
The British government today is the same government which in the 18th century and the 19th century encouraged buying slaves in Africa and forcibly transporting them to colonies to be forced to work. So it is responsible for its past actions — just as the US government and state governments are responsible for their past denial of equal rights to certain groups.
Upcoming talk Quito at Central University of Ecuador [Richard Stallman's Political Notes]
Richard Stallman hará una conferencia en Quito a la Universidad Central del Ecuador el 17 de noviembre a las 08:30. El público está invitado. El software libre y la libertad en la sociedad digital.
Richard Stallman will giva a talk in Quito at Central University of Ecuador, November 17 at 08:30. Free software and freedom in the digital society. The talk is in Spanish at Central University of Ecuador in Quito
Upcoming talk in Quito for the INCISCOS event at Central University of Ecuador [Richard Stallman's Political Notes]
Richard Stallman hará una conferencia en Quito al evento INCISCOS en la Universidad Central del Ecuador, el 19 de noviembre a las 10:00. El público está invitado. El software libre y la libertad en la sociedad digital.
Richard stallman will give a talk in Quito to the INCISCOS event at Central University of Ecuador, November 19 at 10:00. Free Software and freedom in digital society The talk is in Spanish in Quito at Central University of Ecuador.
Upcoming talk in Guayaquil at Central University in Ecuador [Richard Stallman's Political Notes]
Richard Stallman hará una conferencia en Guayaquil a la Universidad Central del Ecuador el 23 de november a las 10:00. El público está invitado. El software libre y la libertad en la sociedad digital.
Richard Stallman will give a talk at Central University of Ecuador, November 10 at 10:00. Free Software and freedom in digital society The talk is in Spanish in Guayaquil at Central University of Ecuador
Upcoming talk in Quito at Salesian Polytechnic University [Richard Stallman's Political Notes]
Richard Stallman hará una conferencia en Quito a la Universidad Politecnica Salesiana el 25 de noviembre a las 10:00. El público está invitado. El software libre y la libertad en la sociedad digital.
Richard Stallman will hold a talk in Quito at Salesian Polytechnic University on November 25 at 10:00. Free Software and freedom in digital society The talk is in Spanish in Guayaquil at Central University of Ecuador.
Upcoming talk in Cuenca at Salesian Polytechnic University [Richard Stallman's Political Notes]
Richard Stallman hará una conferencia en Cuenca a la Universidad Politecnica Salesiana, el 30 de noviembre à las 16:00. El público está invitado. El software libre y la libertad en la sociedad digital.
Richard Stallman will give a talk in Cuenca at the Salesian Polytechnic University on November 30 at 16:00. Free Software and freedom in digital society The talk is in Spanish in Cuenca at the Salesian Polytechnic University.
Polo: a new Wayland compositor for MATE [OSnews]
MATE is probably the last X11-only holdout among the major desktop environments, but that’s about to change if Kerem Söke has anything to say about it.
Polo is a port of Marco’s behavior and window management policies to Wayland, built on libweston and written in Vala and C. It’s a window manager, compositor, and session authority for the MATE Wayland desktop. It takes over, step by step, what Marco, mate-session-manager and the compositor-facing parts of mate-settings-daemon do on X11.
↫ Polo’s GitHub page
Söke is looking for testers with this very first Polo 1.0.0 release – cute name, too – which is available on its GitHub page.
IBM to offer access to a dual-processor quantum system in 2027 [OSnews]
Ars Technica published a short write-up about changes to IBM’s quantum computing plans.
The changes greatly expand the scope of its next-generation Nighthawk general-use processors by adding a version with over 500 programmable qubits. At the same time, it’s stepping back a bit on its plan to link multiple Nighthawk processors together, dropping the intended number of linked systems from nine to two.
The total number of qubits planned for next year will remain the same; how the company is getting there, however, will be different.
Meanwhile, the company is touting the performance boost achieved via a major change that was made in the generation of Nighthawk processors released in September: hardware-based qubit resets.
↫ John Timmer at Ars Technica
I’m convinced quantum computing will eventually have a big impact in the areas its characteristics are presumed to be well-suited for. Also, it just looks and sounds incredibly cool, even if as the technology currently stands it’s not particularly useful yet.
Thursday, 12 November
22:56
EncryptFest at OLF with Greg Farough & Heshan de Silva-Weeramuni [Planet GNU]
November 20, 2026 from 12:00 to 13:00 CST.
El software libre y la libertad en la sociedad digital con Richard Stallman [Planet GNU]
El 30 de noviembre a las 16:00 ECT.
El software libre y la libertad en la sociedad digital con Richard Stallman [Planet GNU]
El 23 de noviembre a las 10:00 ECT.
El software libre y la libertad en la sociedad digital con Richard Stallman [Planet GNU]
El 25 de noviembre a las 10:00 ECT.
El software libre y la libertad en la sociedad digital con Richard Stallman [Planet GNU]
El 17 de noviembre a las 10:00 ECT.
21:42
El software libre y la libertad en la sociedad digital con Richard Stallman [Events]
El 19 de diciembre a las 10:00 ECT.
21:21
Pluralistic: Uber's labor crash (12 Nov 2026) [Pluralistic: Daily links from Cory Doctorow]
->->->->->->->->->->->->->->->->->->->->->->->->->->->->->
Top Sources: None -->

Today's links
- Uber's labor crash: Replacing serfs with robots just doesn't pencil out.
- Hey look at this: Delights to delectate.
- Object permanence: Asimov inspired Al Qaeda; PATRIOT Act scares Canadian customers off US servers; EFF v Trump; Internet infrastructure is unsupported and failing; Nominative determinism debunked; How to fight Trump; Burglars v burglary; NYT said Hitler was only kidding; Folky Song Funny Note; Surviving autocracy; Corporate criminals.
- Upcoming appearances: Vancouver, Folkestone, Oxford, Sheffield, Virtual, Oxford, Santa Barbara, Montreal.
- Recent appearances: Where I've been.
- Latest books: You keep readin' em, I'll keep writin' 'em.
- Upcoming books: Like I said, I'll keep writin' 'em.
- Colophon: All the rest.

Uber's labor crash (permalink)
There's a specific kind of lie that tech bosses tell: the "premature truth." That's a lie that they excuse by saying it'll come true soon:
https://pluralistic.net/2024/12/04/its-not-a-lie/#its-a-premature-truth
Elon Musk is the world's most enthusiastic teller of these lies. That's not surprising: any kind of radical promise about the automotive sector has a 90% chance of being this kind of bullshit. Musk can barely mention the subject of transportation without lying his face off: from "full self-driving" to "hyperloops" to "tunnels" to "flying cars," Musk is a fountain of extremely untrue "premature truths":
https://karlbode.com/musks-fake-flying-car-and-ceo-said-a-thing-journalism/
But Musk has plenty of competition when it comes to lies about futuristic cars. Long before Musk switched on his first bullshit factory, Uber was spending billions to spray the world with lies about cars. Uber has always lied about everything, from driver pay to the company's finances.
Now, lying about driver pay is relatively low-risk for a company like Uber. After all, the company created the app-based worker misclassification playbook, designed to make vulnerable and precarious workers even more vulnerable and precarious. The lies Uber tells about its workforce only have to survive contact with credulous municipal governments so that they keep up a supply of get-out-of-jail-free cards for Uber's many labor, licensing and consumer rights violations.
But lying about your finances is another matter altogether. When Uber lies about its finances, it is lying to rich people, and (unlike workers), rich people have many ways to punish people who lie to them. Despite this, Uber spent more than a decade lying flagrantly and lavishly about its balance sheet.
The most shameless financial lie Uber told is that it was profitable due to the increased valuation of the many ride-hailing companies around the world that Uber owns large shares in. How did Uber come to own large shares in these companies? It happened after Uber's competing ride-hailing companies in countries around the world failed.
Uber's subsidiaries lost billions of dollars, and eventually Uber sold them to its (also money-losing) domestic rivals in all-stock deals that saw Uber acquiring vast amounts of worthless, illiquid shares in the world's failing ride-hailing companies. Then, for years, Uber would announce that its stake in these companies had appreciated in value. These revaluations were purely vibes-based. Uber's former rivals were privately held, and while small volumes of shares traded hands in private deals, Uber's pronouncements that, say, the Chinese company Didi was now worth vastly more than it had been worth a few months before was sheer fantasy dressed up as profits:
https://pluralistic.net/2022/02/11/bezzlers-gonna-bezzle/#gryft
Uber did this over and over (and over and over), relentlessly dogged by Hubert Horan, an aviation analyst who became the world's foremost close-reader of Uber's financial statements:
https://pluralistic.net/2023/08/09/accounting-gimmicks/#unter
Despite these lies, Uber eventually found a way for its early investors to cash out, through a very successful IPO that saw the House of Saud made whole (and then some) on the $31b they plowed into the business so that it could lose $0.41 on every dollar it brought in for the preceding 13 years.
The most remarkable thing about Uber's IPO was the company's S1, the prospectus that tells normie investors how the company will eventually find its way to profit. That's where you'll find Uber's claim that its "total addressable market" is every journey made by taxi, private car, train and bus, for everyone in the world:
https://stratechery.com/2019/uber-questions/
Despite the wild implausibility of this ambition, the company did achieve actual profitability after its IPO. It got there through the simple expedient of paying drivers less and charging riders more. The company spies on its drivers to calculate the lowest wage they'll accept, based on their inferred economic desperation, a process that Veena Dubal calls "algorithmic wage discrimination":
https://pluralistic.net/2023/04/12/algorithmic-wage-discrimination/#fishers-of-men
They also use surveillance data about riders to calculate the highest price you'll pay for a journey. Investors call this "personalized pricing," while everyone else calls it "surveillance pricing." It's a way for Uber to reach into your bank account and reduce the value of your dollars, by charging you more than the next person would pay for the same service:
https://pluralistic.net/2025/06/24/price-discrimination/
This is something AI turns out to be extremely good at. Businesses can program chatbots to automatically segment their customers and employees based on surveillance data and then perform a series of automated experiments to find the highest prices and lowest wages they'll accept:
https://pluralistic.net/2026/07/30/pay-for-privacy/#ab2654
When it comes to wage theft and price gouging, Uber leads the pack. They've really demonstrated just how much consumer and labor surplus can be diverted to capital with the aid of AI.
Of course, it helps that they're willing to lie like crazy. Uber routinely claims that it pays its drivers hourly rates that are far in excess of minimum wage, but it helpfully omits that drivers only get paid while they have a passenger in the car, and that the company punishes drivers who turn down too many unprofitable jobs.
Drivers only get paid for a fraction of the time they spend working for Uber, and on top of that, they have to pay for fuel, insurance, depreciation, loan interest, and the cost of getting vomit out of their back seats. Add it all up and Uber drivers make peanuts. In Toronto, Uber pay nets out to something like $2.50/hour:
https://pluralistic.net/2024/02/29/geometry-hates-uber/#toronto-the-gullible
$2.50/hour isn't a living wage anywhere in Canada, but it's especially terrible in Toronto, one of the world's most expensive cities. Uber can only be profitable for so long as drivers continue to subsidize its business, and so long as riders are willing to pay more than they ever did under the traditional taxi system (much of which was seen off by Uber's Saudi-subsidized decade of predatory pricing, which also induced a lost decade in global transit investment).
Inflation (supercharged by AI pricing) has hit all workers, but it's been especially hard on Uber drivers, who didn't have any financial cushion to start with. Eventually, drivers were bound to turn their backs on Uber. "Eventually" is now, according to Uber's Q3 earnings call, where CEO Dara Khosrowshahi told investors that "driver supply [was] not keeping pace with strong consumer demand in several international markets":
As The Gig Economy Project writes, the driver shortage is especially sharp in India and Brazil, two gigantic countries where (according to Uber CFO Balaji Krishnamurthy), there is too much consumer "price sensitivity":
https://thegigeconomyproject.substack.com/p/has-uber-finally-pushed-its-workers
Uber's also having trouble getting drivers to accept the rock-bottom wages they're offering for food delivery. Despite this, Krishnamurthy assured investors that the company's measures to "improve driver availability" wouldn't affect their bottom line. Instead, Krishnamurthy promised to raise prices on riders elsewhere, something he called "re-balancing incentives":
That is part of the art that we’ve got and then there is a lot of algorithmic science that goes into, if you have a dollar, what is the maximum predicted return for that dollar and should I invest that dollar in a driver in Brazil or should I invest that dollar in a rider in India, for example. The algorithm can structurally make these choices based on training on billions of trips and allocate these investments in the way that humans just can’t.
The Gig Economy Project goes on to say that "robotaxis will fundamentally alter the unit economics of taxis, but we are still some time away from the point where robotaxis are price competitive with human-driven vehicles."
Boy is this an understatement. Remember, Uber is already paying drivers sub-minimum, sub-starvation wages, which drivers must spend to cover all the capital, depreciation, maintenance and insurance costs, along with (skyrocketing) fuel costs. I can't think of any way in which replacing starvation-wage drivers who provide their own cars with $200k robotaxis that the company must operate, maintain and insure will work out better for the company than the current situation.
This is as good as it gets for Uber, in other words. Being able to tap an army of desperate workers who supply 99% of Uber's business's capital and variable costs out of their own pockets is vastly superior to operating a fleet of expensive robots that Uber has to purchase and service.
Profitable "driverless" cars have been around the corner for more than 15 years now. Waymo claims to have delivered this through the brute force expedient of using the most expensive sensors and vast amounts of incredibly expensive cloud computing, but their balance sheet remains stubbornly opaque. We don't know how often a "driverless" Waymo is just a remote control car, being piloted by a low-wage worker in an overseas call center (there's a reason Indian technologists joke that AI stands for "Absent Indians"):
https://pluralistic.net/2024/01/29/pay-no-attention/#to-the-little-man-behind-the-curtain
We also don't know how often a Waymo is being overseen by a high-waged engineer. What we do know is that that when GM was forced to reveal this number, it turned out that they'd replaced a single, low-waged cab driver with 1.5 engineers, each of whom earned an order of magnitude more than the cabbie they'd displaced:
https://garymarcus.substack.com/p/could-cruise-be-the-theranos-of-ai
Uber's claims that they were profitable (based on accounting gimmicks) were lies, but they were also premature truths: the company did become profitable (through price-gouging and wage-theft). But there's a limit to how low you can push your workforce's wages, and even if the AI crash delivers a fresh cohort of desperate workers who subsidize Uber's operations for a few more years, they, too, will eventually find that they can't live on $2.50/hour.
When that day comes, robo-taxis won't save the business model. Robots may cost less per hour than Uber drivers (though not by much), but owning a robot is always going to be more expensive than getting drivers to supply free cars to Uber. If Uber can't sustain profitability with that massive subsidy, it is going to hit a wall, and it won't be pretty.
Hey look at this (permalink)
- The missing quadrant in responses to AI https://www.normaltech.ai/p/the-missing-quadrant-in-responses
-
Canada must invest in AI now, before we miss our chance to lose all our money in the bubble crash, by Mark Carney https://www.thebeaverton.com/2026/11/op-ed-canada-must-invest-in-ai-now-before-we-miss-our-chance-to-lose-all-our-money-in-the-bubble-crash-by-mark-carney/
-
Friends Don’t Let Friends Sign Up for Medicare Advantage. Here’s Why. https://economicpopulist.substack.com/p/friends-dont-let-friends-sign-up
-
The Honeypot That Might End the AI Boom https://prospect.org/2026/11/10/honeypot-that-might-end-the-ai-boom-jensen-huang-invidia/
-
What Constant Surveillance Is Doing to Children https://www.theatlantic.com/magazine/2026/12/location-tracking-apps-parental-surveillance/689031/
Object permanence (permalink)
#25yrsago ObL got the name "Al Qaeda" from Asimov's Foundation https://web.archive.org/web/20250102222933/https://www.theguardian.com/books/2002/aug/24/alqaida.sciencefictionfantasyandhorror
#25yrsago Folky Song Funny Note https://craphound.com/misc/Folky_Song_Funny_Note.mp3
#20yrsago PATRIOT scares Canadian unis off US servers https://web.archive.org/web/20080204033238/http://www.theglobeandmail.com/servlet/Page/document/v5/content/subscribe?user_URL=http://www.theglobeandmail.com%2Fservlet%2Fstory%2FRTGAM.20061111.wxuniversities11
#15yrsago Minimum wage hike coming to Guangdong, the world’s factory https://web.archive.org/web/20111110113740/http://www.globalpost.com/dispatch/news/regions/asia-pacific/china/111109/china-economy-manufacturing-guangdong
#10yrsago EFF in Trump’s America: Protecting Tomorrow https://www.eff.org/deeplinks/2016/11/protecting-tomorrow
#10yrsago America’s actually had worse presidential races than this one https://www.loweringthebar.net/2016/11/worst-presidential-race.html
#10yrsago The internet’s core infrastructure is dangerously unsupported and could crumble (but we can save it!) https://web.archive.org/web/20170222232454/https://fordfoundcontent.blob.core.windows.net/media/2976/roads-and-bridges-the-unseen-labor-behind-our-digital-infrastructure.pdf
#10yrsago Fact-checking Trump’s plan for the first 100 days https://www.npr.org/2016/11/10/501597652/fact-check-donald-trumps-first-100-days-action-plan
#10yrsago Dennis the Dentist: on the unkillable wrongness of nominative determinism https://timharford.com/2016/11/rich-the-banker-whats-not-in-a-name/
#10yrsago How to fight Trump, starting right now https://medium.com/@anildash/forget-why-its-time-to-get-to-work-c49ac5f0da20#.l0xpc3pps
#10yrsago Anti-burglary advice, from burglars https://web.archive.org/web/20161118141701/https://www.kgw.com/news/investigations/we-asked-86-burglars-how-they-broke-into-homes/344213396
#10yrsago Serbian ultra-nationalists celebrate Trump’s victory https://globalvoices.org/2016/11/10/nationalists-and-populists-in-serbia-and-macedonia-celebrate-trumps-victory/
#10yrsago Leonard Cohen wrote the perfect anthem for our times https://memex.craphound.com/2016/11/11/leonard-cohen-wrote-the-perfect-anthem-for-our-times/
#10yrsago “Hitler’s only kidding about the antisemitism” New York Times, 1922 https://archive.nytimes.com/www.nytimes.com/times-insider/2015/02/10/1922-hitler-in-bavaria/?_r=0&smid=tw-share
#10yrsago Rules for surviving an autocracy https://web.archive.org/web/20161111205036/https://www.nybooks.com/daily/s3/nov/10/trump-election-autocracy-rules-for-survival.html
#1yrago American corporate criminals in the crosshairs (finally) https://pluralistic.net/2021/11/12/with-a-fountain-pen/#recidivism
#1yrago A tale of three customer service chatbots https://pluralistic.net/2025/11/11/sorry-to-bother-you/#we-dont-care-we-dont-have-to
Upcoming appearances (permalink)
- Vancouver: BC Policy Solutions Gala, Nov 12
https://bcpolicy.ca/gala/ -
Folkestone Writers Festival, Nov 16
https://www.creativefolkestone.org.uk/whats-on/cory-doctorow-the-internet-is-broken-now-what/ -
Oxford: Ministry of the Future, Nov 23
https://ministryforthefuture.co.uk/events.html -
Sheffield: Reverse Centaur at Juno Books, Nov 25
https://www.outsavvy.com/event/40274/cory-doctorow-in-conversation -
Virtual: Enshittification, AI, and the Future of Technology (UBC Master of Educational Technology), Nov 28
https://met.ubc.ca/2026/09/met-speaker-series-cory-doctorow-enshittification-ai-and-the-future-of-technology/ -
Oxford: Bennett Oxford Symposium on Open Code in Science, Dec 9
https://www.bennett.ox.ac.uk/events/2026-bennett-institute-symposium/ -
Santa Barbara: UCSB Reads, Apr 29
https://www.library.ucsb.edu/events-exhibitions/ucsb-reads-2027-presents-author-cory-doctorow -
Montreal: World Science Fiction Convention, Sep 2-6
https://montreal2027.ca/en
Recent appearances (permalink)
- Clint Eastwood (No Gods No Mayors)
https://www.patreon.com/NoGodsNoMayors/posts/clint-eastwood-173008088 -
Life After AI (Brain Bar)
https://www.youtube.com/watch?v=IPPa43-n0vI -
Terms of Service with Clare Duffy (CNN)
https://www.cnn.com/audio/podcasts/terms-of-service-with-clare-duffy/episodes/458ce968-af5d-11f0-b539-13ed2afe25f8 -
AI, Work, and Power (Software Engineering Daily)
AI, Work, and Power https://softwareengineeringdaily.com/podcasts/cory-doctorow-on-ai-work-and-power/ -
AI, Corporate Power, and the Fight for Worker Control (Plutopia)
https://plutopia.io/cory-doctorow-ai-corporate-power-and-the-fight-for-worker-control/
Latest books (permalink)
- "The Reverse-Centaur's Guide to AI," a short book about being a
better AI critic, Farrar, Straus and Giroux, June 2026
https://us.macmillan.com/books/9780374621568/thereversecentaursguidetolifeafterai/ -
"Canny Valley": A limited edition collection of the collages I create for Pluralistic, self-published, September 2025 https://pluralistic.net/2025/09/04/illustrious/#chairman-bruce
-
"Enshittification: Why Everything Suddenly Got Worse and What to Do About It," Farrar, Straus, Giroux, October 7 2025
https://us.macmillan.com/books/9780374619329/enshittification/ -
"Picks and Shovels": a sequel to "Red Team Blues," about the heroic era of the PC, Tor Books (US), Head of Zeus (UK), February 2025 (https://us.macmillan.com/books/9781250865908/picksandshovels).
-
"The Bezzle": a sequel to "Red Team Blues," about prison-tech and other grifts, Tor Books (US), Head of Zeus (UK), February 2024 (thebezzle.org).
-
"The Lost Cause:" a solarpunk novel of hope in the climate emergency, Tor Books (US), Head of Zeus (UK), November 2023 (http://lost-cause.org).
-
"The Internet Con": A nonfiction book about interoperability and Big Tech (Verso) September 2023 (http://seizethemeansofcomputation.org). Signed copies at Book Soup (https://www.booksoup.com/book/9781804291245).
-
"Red Team Blues": "A grabby, compulsive thriller that will leave you knowing more about how the world works than you did before." Tor Books http://redteamblues.com.
-
"Chokepoint Capitalism: How to Beat Big Tech, Tame Big Content, and Get Artists Paid, with Rebecca Giblin", on how to unrig the markets for creative labor, Beacon Press/Scribe 2022 https://chokepointcapitalism.com
Upcoming books (permalink)
- "The Post-American Internet," a geopolitical sequel of sorts to Enshittification, Farrar, Straus and Giroux, 2027
-
"Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027
-
"Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027
-
"The Memex Method," Farrar, Straus, Giroux, 2027
Colophon (permalink)
Today's top sources:
Currently writing:
- “Once Is Enemy Action,” a science fiction novel
about the origins of modern technofascism. Today's words: 516
(35512 total).
-
"The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.
-
A Little Brother short story about DIY insulin PLANNING
This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.
https://creativecommons.org/licenses/by/4.0/
Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.
How to get Pluralistic:
Blog (no ads, tracking, or data-collection):
Newsletter (no ads, tracking, or data-collection):
https://pluralistic.net/plura-list
Mastodon (no ads, tracking, or data-collection):
Bluesky (no ads, possible tracking and data-collection):
https://bsky.app/profile/doctorow.pluralistic.net
Medium (no ads, paywalled):
Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):
https://mostlysignssomeportents.tumblr.com/tagged/pluralistic
"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla
READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.
ISSN: 3066-764X
20:28
How can I pass more than one parameter to co_await? [The Old New Thing]
Suppose you have an awaitable object, but you want the caller to
pass a bonus parameter when they do a co_await. For
example, you may want the caller to be able to pass a priority or a
timeout or something else that modifies how the await occurs.
struct Widget
{
    ⟦ ... other stuff ... ⟧

    bool await_ready() const { return ⟦ ... ⟧; }

    bool await_suspend(std::coroutine_handle<> handle)
    {
        int priority = ??? how do I get a priority ???;

        return internal_start(handle, priority);
    }

    auto await_resume() { return ⟦ ... ⟧; }
};

// This doesn't work
auto result = co_await (widget, priority);
So how do you pass two parameters to co_await so
they can be used in await_suspend?
It’s a trick question. You can’t. The
co_await operator takes only one parameter.
So you’ll have to take all the things you want to use and put them into a single parameter.
Wrap the awaitable object and its parameters into a larger object, and then await the larger object.
First, let’s rename away the coroutine methods inside
Widget since we aren’t awaiting it directly any
more.
struct Widget
{
    ⟦ ... other stuff ... ⟧

private:
    bool inner_await_ready() const { return ⟦ ... ⟧; }

    bool inner_await_suspend(std::coroutine_handle<> handle)
    {
        int priority = ??? how do I get a priority ???;

        return internal_start(handle, priority);
    }

    auto inner_await_resume() const { return ⟦ ... ⟧; }
};
Now we can add a priority parameter to the
inner_await_suspend:
struct Widget
{
    ⟦ ... other stuff ... ⟧

private:
    bool inner_await_ready() const { return ⟦ ... ⟧; }

    bool inner_await_suspend(std::coroutine_handle<> handle, int priority)
    {
        return internal_start(handle, priority);
    }

    auto inner_await_resume() const { return ⟦ ... ⟧; }
};
And finally, we create a helper class (which is a friend of
Widget) that wraps the original object and its
priority into a single new awaitable object.
struct Widget
{
    ⟦ ... other stuff ... ⟧

private:
    friend struct widget_with_priority;

    ⟦ ... as before ... ⟧
};

struct widget_with_priority
{
    widget_with_priority(Widget const& widget, int priority) :
        m_widget(widget), m_priority(priority) {}

    bool await_ready() const { return m_widget.inner_await_ready(); }

    auto await_suspend(std::coroutine_handle<> handle)
    {
        return m_widget.inner_await_suspend(handle, m_priority);
    }

    auto await_ready() {
        return m_widget.await_ready();
    }

    Widget const& m_widget;
    int m_priority;
};
You can now do
co_await widget_with_priority(widget, priority);
This solves the problem but is rather unwieldy. We’ll address that next time.
The post How can I pass more than one parameter to <CODE>co_await</CODE>? appeared first on The Old New Thing.
19:14
Rust 1.100.0 released [LWN.net]
Version 1.100.0 of the Rust language has been released. Notable changes include the stabilization of the never type, core parts of the Allocator API, reporting of unused dependencies in Cargo, and more.
19:07
The Saddest Stray You Ever Did See [Whatever]
WARNING: THE FOLLOWING CAT PHOTOS MAY BE DISTRESSING TO SOME READERS (no gore, just.. a really rough looking cat.)
Another day in Bradford, another stray cat. Though, this time it isn’t a kitten, it’s a very, very rough looking guy that has reportedly been out on the streets for at least a year. I have never seen a cat in this sort of state before, it’s truly shocking how he’s even alive, honestly. Here’s who I am referring to as Big Grey:

The longer I looked at him and petted him, the more I saw wrong with him. So matted, so dirty, so in need of care and love. He broke my heart.
Worst of all, there is literally a rag that is just like, fused to him:

I know he looks rough, but he is extremely sweet and affectionate:

He is very gentle and timid, it was very surprising.
Well, he was that way until I snatched him and put him in my
garage. Now, he is not so happy with me. In fact, I was going to
take him to the vet today, but he will not let me get close to him
without hissing and swiping at me. I know he’s just scared,
but I desperately need him to let me put him in a carrier and that
is just not happening right now.
In the meantime, he’s been eating wet food and drinking water, and he’s used the litterbox I put out for him. I put out a blanket for him but every time I’ve checked on him he is pretty much petrified in the corner of the garage. I feel so bad I’m scaring him, but I’d like to think it’s for his own good in the long run.
Yesterday, before he was even caught, I called twenty, TWENTY shelters and rescues in the area and either got no answer with no voicemail set up, or got told they were either completely full already or just simply didn’t take cats at all. There’s one place that does TNR but their waitlist is a month or even two out, and I want more care for this cat than just TNR.
I know he’s sweet. I know he likes head scritches and pets. I know he doesn’t meow or yowl or make any noise, even when in the carrier. He goes in a litterbox, he eats (or ate, previously) Churu right from the tube in my hand. I know there’s a big, beautiful, fluffy grey cat under there that just needs love. He will be a good companion, I just know it.
Since I can’t get him to a vet currently, I am going to try to regain his trust and affection over the next few days by hanging out with him in the garage and feeding him, and I can only hope he’ll adjust soon.
I’ll keep y’all updated.
-AMS
18:21
Generative AI in the Real World: Memory for Personal AI with Duncan Davidson [Radar]
This post was created with the assistance of AI, based on a transcript of the conversation.
AI tools have started to remember their users, but each tool remembers a different version of the same person. Duncan Davidson, an independent consultant and longtime software engineer, has been trying to connect those fragments. He joined Ben Lorica to discuss what personal AI could do if people could carry their context between services and decide what each service gets to see.
They also talked about how AI coding changed web development during Duncan’s time at Webflow, what new developers may lose as entry-level work changes, and why open source projects need new ways to handle AI-assisted contributions.
About the Generative AI in the Real World podcast: In 2023, ChatGPT put AI on everyone’s agenda. In 2026, the challenge will be turning those agendas into reality. In Generative AI in the Real World, Ben Lorica interviews leaders who are building with AI. Learn from their experience to help put AI to work in your enterprise.
Check out other episodes of this podcast on the O’Reilly learning platform or follow us on YouTube, Spotify, Apple, or wherever you get your podcasts.
Takeaways
06.31 The developer’s job is moving toward outcomes. Duncan compared AI coding to desktop publishing, which removed the physical work of assembling pages but left designers responsible for what the page should look like. At Webflow, he saw people use AI tools to make websites faster than they could with earlier tools. For developers, he said, the question has shifted from how quickly they can type code to “What outcome do you want? What are you trying to do with this code, and how can you make it better?” People still need to judge whether an implementation fits the rest of the system.
10.41 New developers still need a way to become experts. Computer science fundamentals still matter when an agent offers several plausible fixes and a person must choose the one that fits a larger system. Ben asked where future engineers will gain that judgment if AI absorbs entry-level tasks. Duncan compared early career work to an apprenticeship in the arts, where even menial assignments expose newcomers to how the whole operation works. Companies that measure only throughput, he warned, may leave too little room for people to learn.
23.07 AI-assisted changes are straining open source review. Duncan described a library he uses in one of his apps. His fixes, along with performance problems Claude noticed, left his version roughly 25 pull requests ahead of the project’s main branch. The maintainers were using AI too, he said. The difficulty was getting useful changes back to the project without overwhelming its review process. His conclusion was that older open source collaboration practices need a “serious retrofit.”
28.27 Personal memory is fragmented across tools. Duncan first had his coding agents save useful information into a collection of Markdown files. Once commercial agents added memory, he found that “Claude knew me one way and ChatGPT knows me another way.” He could push context back to each tool with instructions and occasional reminders, but that solution demands more tinkering than most people want to do. What he wants is a small set of shared mechanisms that let a person carry context across services.
34.01 Portable memory needs boundaries. A prompt’s context, an agent’s memory of recent interactions, and a person’s longer-term knowledge should be able to travel, but Duncan also wants people to control access by scope. He keeps general notes alongside information about his family and finances. His test for a useful system is whether he can say, “Give Claude access to these scopes of my knowledge, but not everything.” That becomes harder when a personal agent encounters knowledge gained at work. Duncan left open where an employee’s own expertise ends and an employer’s information begins.
36.44 Trust and security shape what people will share. Ben’s not yet comfortable letting a consumer agent reach into his finances. Duncan noted that trust would have to grow through experience, as it would with a human agent. We’re already seeing how AI agents can find vulnerabilities faster than established disclosure practices can handle. Duncan expects software maintainers to face more pressure as agents uncover latent bugs, while Ben questioned how quickly organizations that rely on vulnerable code would learn about the findings. People need control over what an agent can access and confidence in the systems around it.
49.52 A personal memory could answer requests with permission. Duncan imagined keeping his memory on his phone and giving a new service a way to request specific information. A car dealership’s agent, for example, could ask for details, but the phone would seek his approval before sharing them. He put it this way:
I could provide it a handle to my memory. And whatever agents they’re working with can come in and ping me and say, “Hey, we’d like to know these things about you.” And it wouldn’t necessarily do it automatically.
18:14
The Big Idea: Amy Avery [Whatever]

Writing a good book is like preparing a good meal. It takes time, precision, intention, and most of all, spice. Author Amy Avery was in the kitchen whippin’ up a storm for her newest novel, The Thorns We Wear Inside. Grab a cozy bowl of hot soup (or chili) and check out her Big Idea.
AMY AVERY:
When the first hint of a cool autumn breeze settles in each year, I turn to a beloved annual tradition: I make chili.
I don’t have a recipe. Each batch uses a few similar base ingredients, but the seasoning is more of a follow-the-vibes situation, trusting my gut. A little more garlic here, a pinch of cayenne or paprika there, and let’s add a dash of cinnamon. Maybe a tiny piece of bittersweet chocolate if I’m feeling saucy. The entire contents of my spice cabinet end up scattered across the countertop in my best imitation of a mad scientist’s laboratory. As it simmers for a few hours, I continue to taste and add until it finally just becomes chili.
Such was the creation of The Thorns We Wear Inside.
The creative spark for this book was not one clear moment of inspiration, but a melting pot of things I adore. It initially began as a palate cleanser after a particularly grueling project, written in the spirit of flagrant self-indulgence.
I started with the base, a monstrous romance. Something I’d always adored, but had yet to write as an adult. I crafted a creature with a thirst for blood, then paired her with a woman fighting her own inner darkness.
But what of the setting, the atmosphere? For this, I blended two of my favorite genres. A gothic castle and an eerie fairy tale curse went into the pot.
Then things began to shake loose from my subconscious. The truly deep loves. You know, the kind of plot device or trope or story element that makes a friend say, “I read this and knew you’d love it.” Faustian bargains. The nature of temptation. The clash of religions. The blurry line between horror and eroticism, fear and love. A bit of gore and a whole heap of yearning.
In this soup of assorted ideas, two characters emerged. Raye, a tenacious survivor running from a world that hunts her, even though she can’t escape her own (quite literal) demon. Mir, a haunted woman transformed into a horrific, bloodthirsty monster and bearing her own matching demon.
So often, my books come together in this way. A jumble of puzzle pieces and a lot of “what if” questions start the process, then the real story emerges as everything rattles around in my brain. In this case, a project that started as pure indulgence had simmered and developed richer layers of flavor.
For me, what crystallizes into the core of a novel is often uncomfortably personal. This was very certainly true of The Thorns We Wear Inside. I accidentally found myself reflected in these two women. In Raye’s gritty determination and dry sense of humor, in Mir’s feelings of despair and anger and confinement. In many ways, they each brought my own insecurities to the table. Their romance is about forgiving and learning to love oneself as much as it is their feelings for each other.
When that realization clicked into place, I had my big idea. I knew what this story would be. It had finally become chili.
In the end, The Thorns We Wear Inside is a message I needed to hear, a tale of hope. You are never broken beyond repair. The path may be violent, dark, and unsettling, but light can always be found.
(And sorry about that sudden chili craving.)
The Thorns We Wear Inside: Amazon|Barnes & Noble|Bookshop|Watermark Books & Cafe
16:56
Glasswing overwhelms maintainers with underwhelming findings (VulnCheck) [LWN.net]
Patrick Garrity of VulnCheck has written a blog post that looks at vulnerabilities found by Anthropic's Project Glasswing since it launched on April 7, and finds it wanting:
Of the 37,966 findings Anthropic reports, only 7,349 (19.4%) have been made public. Just 217 of those have been marked fixed. The more glaring number is that 4.4% (1,654) of the project's findings have already been marked as duplicates, 7.5x more duplicates than fixes. On top of that, 419 findings have been withdrawn. It seems odd that the ledger now claims a 94.2% true positive rate, up from 90.8% at launch, when more findings have been withdrawn or marked as duplicates than fixed, likely a feedback loop missing to the triage rates listed as "True Positives".
[...] AI is a valuable tool for finding vulnerabilities, and I'm not discounting that. But seven months in, the evidence still doesn't match the launch narrative. The CVEs are a sliver of this year's total, almost none are being exploited, fixes have stalled while duplicates and withdrawals pile up, and the triage burden is shifting onto the open source maintainers Glasswing promised to help. The receipts keep coming in. They still don't reconcile.
16:42
Launching today: a collection of hundreds of stores that are worth detouring past Amazon to get to.
The stores were nominated by you, the readers of this blog, and are only lightly curated. There’s no business model for the site, just a collective sharing. Click and explore.
There are three ways to visit the site:

The HOTLIST creates a grid of the stores. The odd numbered entries are random, the even ones are sorted by the number of clicks they’ve received. Every time the page is loaded, these re-sort based on popularity.
The CATEGORY view shows you all the listings in a reasonably coherent directory.
And the RANDOM view is just what you’d imagine.
I hope it gives small businesses a bit of a boost.
Also, we’ve reached the last few weeks for the holiday bundle of three of my books and a handful of spindices. Sold only by the friendly folks at Porchlight.

[If you missed the original form for nominations, I’ll open it again for one more batch. I can’t promise to include everything, but I’m thrilled at the creativity and care that these merchants and creators have brought to their work.]
Bonus: a lovely post by Ari about Purple Cow and the magic of being hard to explain.
16:28


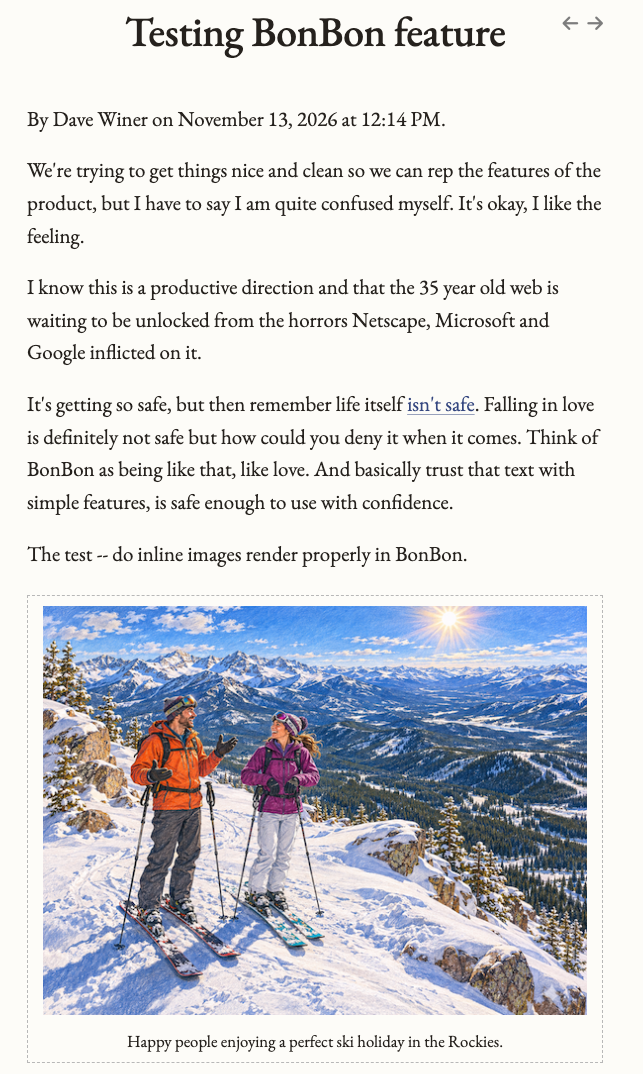
16:00
 We're doing a demo site for BonBon, as part of the docs, and
as I was planning it out I remembered we did one for a "newly hired
senior evangelist" at a ficitious Silicon Valley startup. This is
what I love about AI tools. I couldn't remember her name or the
name of the company but i remembered it was funny. So I explained
the problem to Claude, and it gave me what I want. The new hire is
Kim Parker, and she was hired by Bloatware. This is where having
kept good records on the web comes in handy. A search engine
wouldn't be much help because I didn't remember her name or the
name of the company. And I wrote too much about Fargo for that to
be a good search term. Instead my prompt was: "i wrote an app
called fargo a few years ago and it had a demo site that was from a
new hire at the company called Bloatware. can you find it for me on
the web?" Got me what I wanted, and cited all the relevant links.
It seems that Claude cares about the archives on the web more than
the browser vendors do. There are important records there, not just
notes about my latest creation in 2013.
For reference, some links: Kim Parker's blog home, and the github repo for the project, which uses HTML. It's been 13 years since it was updated. I can only imagine what the superstar tech evangelist Kim Parker is doing now.
15:14
Yesterday's braintrust query got lots of responses on Mastodon, and some interesting combinations of products. But none of them streamlined for writers who want to publish.
What to do with billions of dollars? [Scripting News]
The founders of tech companies, no matter how rich they get, are still human with human limits, issues and fantasies. Which is great until they get it into their heads that they are our bosses and get to run our lives instead of focusing on their own.
I was in Silicon Valley for 31 freaking years. And saw it go round and round, and no one ever answered the question -- what the fuck am I supposed to do with all this money?
The better path, imho, which I chose, is to accept your good fortune, but never assume it's because you are a better human than the rest of humanity. There is no such thing.
14:42
Introducing Polo: a Wayland MATE compositor [LWN.net]
Kerem Söke has announced the 1.0 release of Polo, a Wayland compositor for the MATE Desktop Environment:
The idea is to keep MATE behaving as closely as possible to how it does on X11, rather than changing the desktop to fit a different compositor. [...]
Window management, metacity, workspaces, tiling, XWayland, clipboard and clipman support, multiple monitors, display scaling, hotplugging, screenshots, screen sharing, and session management are all working.
I've also added desktop effects: fade, zoom, zap, spin, squeemize, magic lamp, desktop cube, expo, and wobbly windows.
Söke is looking for people to test Polo, particularly on multi-monitor setups, and report back with problems.
Security updates for Thursday [LWN.net]
Security updates have been issued by Debian (aodh, apache2, dnspython, firefox-esr, mutt, octavia, spip, thunderbird, and watcher), Fedora (epiphany, firefox, freerdp, java-25-openjdk, java-latest-openjdk, libsoup3, perl-HTTP-Parser-XS, perl-libnet, php-getid3, pipx, python-crate-ingredients, python-pillow, python-robotframework, python3.9, rsync, rubygem-nokogiri, tpm2-tss, udns, and xorg-x11-server-Xwayland), Gentoo (curl, ImageMagick, libheif, and PCRE2), Mageia (nginx and python-django), Oracle (go-toolset:rhel8, libimobiledevice, nodejs:22, util-linux, and vim), Red Hat (.NET 10.0, .NET 8.0, .NET 9.0, cockpit, freerdp, gdb, go-fdo-client, grafana-pcp, ignition, kernel, kernel-rt, krb5, openssh, openssl, osbuild-composer, rpm, rsync, and webkit2gtk3), Slackware (git, httpd, and tigervnc), SUSE (aliyun-cli, alloy, apache-parent, aqute-bnd, google-gson, logback, maven, maven-artifact-transfer, maven-parent, maven-resolver, methanol, osgi-service- subsystem, slf4j, xmvn, bcel, benchdnn, containerd, distribution, dpdk, efivar, elemental, elemental-register, elemental-system-agent, elemental-toolkit, firefox, kernel, liblldpctl4, libonnxruntime1, openssl-1_0_0, openssl-1_1, openvpn, pcre2, perl-Net-DNS, perl-Plack, perl-Starman, psqlODBC, python-M2Crypto, python-Pillow, python-Twisted, python-urllib3_1, python313-djangorestframework, python313-fpdf2, python313-langgraph-sdk, python313-nltk, rust-keylime, skopeo, traefik, zchunk, and zvbi), and Ubuntu (asyncpg, awl, btrbk, davical, dotnet8, dotnet10, dotnet11, libfcgi, linux-raspi, logback, mysql-8.0, mysql-8.4, mysql-9.7, network-manager-ssh, node-babel, php-pecl-http, prosody-modules, rkhunter, ruby-actionpack-page-caching, ruby-jwt, ruby-kramdown, shiro, snmptt, and yodl).
Stenberg: 30 years of Internet transfers with curl [LWN.net]
Daniel Stenberg reflects on the 30th anniversary of the curl project.
libcurl runs in an estimated thirty billion installations today. It is a rough estimate since the majority of all libcurl users never tell us they use it, but we need to find it mentioned in their credit screens, open source license windows or their manuals. A super popular app might use libcurl today and not tomorrow, or vice versa, which can make the numbers shift by several billions overnight. In reality of course, once the pulse raise has calmed down and your ego is content, these numbers do not matter. In our corner of the world, things don't change notably when we go from a thousand installs to billions. We still work with similar people, in similar ways, with similar challenges.
[$] C++26 contract confusion [LWN.net]
The International Organization for Standardization (ISO) has blessed seven C++ language revisions since 1998. The language is mostly developed by ISO's Working Group 21, which considers proposed additions and amendments, integrates them into a document, and then presents that document to the main ISO body to be voted on as a standard. On October 23, for the first time ever, ISO declined to ratify a document presented by Working Group 21, leaving the future of the C++26 standard in doubt. The decision was driven by controversy around a proposed new "contracts" feature that would add pre- and post-conditions to function signatures.
13:42
Why Git Needs Help: Moving from Files to Systems for Source Control [Radar]
The shift to agentic reality
When Git was designed in 2005, Linus Torvalds solved a brilliant problem for humans collaborating over terminal windows by trading line-by-line diffs. Fast-forward to 2026: Autonomous coding agents don’t think in flat text files or line breaks. They reason across syntax trees, execution traces, call graphs, and type constraints. In my view, forcing an AI agent to engineer complex distributed systems through string matching is like handing a chief software architect a chisel and a stack of sticky notes.
File-centric versus system-centric paradigm shift
| Dimension | Legacy file-centric (Git) | Agent-native system graph |
|---|---|---|
| Representation | Flat Unicode text streams | Tree-Sitter ASTs & CPG nodes |
| Mutation unit | Line-by-line string diffs | AST node transformations |
| Context overhead | 2,000+ line prompt context fills | Sub-50 token targeted node payloads |
| State persistence | Ephemeral model prompt windows | Execution ledgers & reasoning chains |
Whenever I see engineers try to lock context-blind models into file-centric version control, I watch the consequences compound quickly. Context windows fill with irrelevant churn, API bills surge, and subtle, multifile structural breakages slip past basic syntax checks. Just as critically, standard Git discards the cognitive history of a change. The moment an agent session completes, its execution logs, compiler feedback, and discarded hypotheses evaporate into thin air.
Tactical illustration: renaming a distributed method signature
Consider updating a core helper signature across 40 dependent services. A traditional string diff forces the agent to read and mutate thousands of lines of surrounding boilerplate text, burning thousands of context tokens per file:
--- a/services/auth.py
+++ b/services/auth.py
@@ -42,7 +42,7 @@ class AuthManager:
     def validate_session(self, token: str) -> UserSession:
-        return fetch_user_by_token(token)
+        return fetch_user_by_token(token, include_metadata=True)
In contrast, an AST mutation node isolates the target function symbol, executing the change precisely without passing unneeded ambient text through the prompt window:
{
  "action": "mutate_node",
  "target_ast_id": "ast_node_89f2a41b",
  "symbol": "fetch_user_by_token",
  "update": {
    "add_argument": { "name": "include_metadata", "value": true }
  }
}
This exact bottleneck hit Anthropic in late 2026. As autonomous agent activity pushed monorepo merges beyond 30,000 per day, conventional Git infrastructure simply buckled under the load. To me, unlocking genuine agentic autonomy requires evolving source control along two complementary tracks: shifting to server-hosted, graph-aware architectures, and treating agent reasoning as a first-class, versioned artifact right alongside the code itself.
Why text diffs and ephemeral sessions create silent debt
Standard diff tools operate purely on raw Unicode strings. When an agent reorders functions or cleans up formatting, string diffs pollute context windows with noise while remaining blind to structural reality. If you modify a single method signature, Git won’t warn you about the dozen callers broken across separate modules. From my experience, feeding 2,000-line source files into prompts just to update a 5-line helper method degrades model attention, burns compute, and inflates overhead at scale.
Text diffs versus AST graph mutations
| Metric / behavior | Text diff (unified patch) | AST graph mutation |
|---|---|---|
| Formatting resilience | Breaks on whitespace or line-ending changes | Immune to syntax formatting shifts |
| Impact analysis | Post hoc CI test failures | Sub-second static call-graph resolution |
| Token consumption | O(file_size) per prompt iteration | O(node_delta) per targeted change |
Compounding this structural blind spot is what I consider our biggest waste: ephemeral session memory. Whenever an agent finishes a task or compacts its context window, its entire diagnostic history—failed attempts, shell outputs, and compiler warnings—disappears. The next agent assigned to the branch steps in completely blind, doomed to repeat the same diagnostic dead ends and burn unnecessary tokens.
Agent-native architectures in practice
In my view, next-generation version control must replace raw file trees with Tree-sitter parsers and code property graphs (CPGs). Instead of editing lines on disk, agents mutate specific syntax nodes directly, executing sub-second edits and running immediate dependency impact checks across the codebase. Moving control back to the server eliminates the massive I/O bottlenecks caused by checking out heavy working trees onto virtual machines, allowing agents to query and update code over fast graph end points.
Practical implementation: server-side microdiff stream
Below is an example payload representing an atomic microdiff layer executed directly on a server-hosted code property graph, bypassing local file checkouts entirely:
{
  "commit_id": "c_9011f4a2",
  "parent_graph_version": "v14.2.0",
  "operations": [
    {
      "op": "replace_node_property",
      "node_uri": "cpg://auth_service/ast/Node_441",
      "property": "return_type",
      "value": "Promise<UserSession>"
    }
  ],
  "validation_hash":
  "sha256_e3b0c44298fc1c149afbf4c8996fb92427ae41e4649b934ca495991b7852b855"
}
This structural shift pairs naturally with stacked microdiffs—atomic, dependent layers verified sequentially in isolated virtual workspaces to prevent merge races. I was particularly impressed seeing the real-world impact of this pattern with Anthropic’s Scion architecture. Faced with object-store locks and clone latencies as daily merges scaled 10x, Anthropic built a server-centric SCM that streams code graphs on demand, slashing infrastructure overhead by 200x while enabling near-instant workspace initialization.
Versioning reasoning and system memory
I strongly believe code changes alone rarely capture full intent. Modern SCM must link model reasoning traces, prompt chains, and decision graphs directly to commit nodes, preserving architectural context for future debugging and audits. Persisting build outputs, compiler logs, and linter runs in execution ledgers attached to commit trees allows subsequent agents to inspect prior test results instantly rather than rerunning identical test suites.
System memory schema: reasoning and execution ledger
To prevent model sessions from repeating diagnostic dead ends, execution ledgers append structured reasoning and compiler feedback directly to commit nodes:
{
  "agent_session_id": "sess_88190c2a",
  "target_commit": "c_9011f4a2",
  "hypothesis_tree": {
    "attempt_1": { "approach": "In-memory caching", "status": "REJECTED",
    "reason": "Memory limit exceeded in integration test" },
    "attempt_2": { "approach": "Redis backing store", "status":
    "VERIFIED", "execution_time_ms": 142 }
  },
  "compiler_ledger": {
    "linter_passed": true,
    "type_check_errors": 0
  }
}
By explicitly recording abandoned branches and failed architectural hypotheses as structured metadata, we stop future agent sessions from reexploring invalid paths. I argue that capturing thought streams alongside code transforms source control from a passive text archive into an active memory system.
The hard engineering trade-offs and counterarguments
I won’t pretend making this transition is easy; it comes with steep engineering trade-offs. Existing developer tooling, from LSPs to build pipelines and IDEs, expects standard local file trees. Replacing checkouts with server-hosted graphs requires building heavy compatibility layers or redesigning workflows. Furthermore, human reviewers still digest code line by line, creating a natural tension with pure graph mutations, while storing continuous thought streams drives up storage and compliance costs. During early refactoring, syntax is often broken and unparseable, forcing systems to temporarily fall back to raw text. Overcoming Git’s decades of deep ecosystem lock-in remains a major operational hurdle we cannot ignore.
Trade-off matrix: architectural migration challenges
| Challenge | Systemic bottleneck | Mitigation strategy |
|---|---|---|
| IDE & tooling lock-in | LSPs expect local file system layouts | Virtual FUSE layers streaming AST nodes on demand |
| Storage overhead | Persisting continuous reasoning logs increases storage 10x | Compacting execution ledgers into summary trees |
| Broken syntax states | AST parsers fail during active multiline refactoring | Fallback to temporary text buffer zones during edits |
Bottom line
Git was designed for humans reviewing text, but agentic scale demands server-centric, graph-aware source control. Code property graphs stop token bloat and prevent silent structural breakages. Versioning reasoning traces and execution histories alongside code keeps agents from repeating past mistakes. And stacked microdiffs offer a clean, isolated path for autonomous agents to ship code safely at scale.
13:14
CodeSOD: Next Month [The Daily WTF]
One of Sean's colleagues left Initech on good terms. It caused no small amount of surprise that the very next day their billing system started failing. The billing system which the colleauge had worked on.
No one truly suspected foul play, it was just a weird coincidence. Still, billing blowing up was a 5 alarm fire, so everyone was throwing every idea out about what could be the cause.
Late in the evening, after staring at the code for many hours, Sean found this:
if item.next_bill_date.month >= end_date.month
  item.next_bill_date = nil
  item.save
else
  ...
end
If the month of the next billing date is greater than the last billing date for this account, wipe the billing date and update the item.
It's worth noting that Sean's co-worker's last date happened to be the end of November, and billing started blowing up on the 1st of December. You'll also note this is checking just the month and not any other part of the date, like, oh, I don't know, the year?
While this bug could happen to any bill, it was blowing up in December because every bill's ending month was greater than or equal to January. So this code canceled all the bills due in January.
The good news was that they could reconstruct the correct next billing dates without having to restore from a backup. The bad news is that some unknown number of billing periods had been canceled for some of their customers, and someone was going to have to check the history.
Sean reached out to his former co-worker to politely thank them for an early Christmas present.
"At least I understand our billing code better," Sean writes.
Your journey to .NET 9 is more than just one decision.Avoid migration migraines with the advice in this free guide. Download Free Guide Now!
12:21
Another Way Police Are Locating People from Their Smartphones [Schneier on Security]
Penlink’s Webloc is an application that locates people using information from the weather, gaming, email, and religious apps on their phone. It’s sold to the police.
The tool collects vast quantities of location data from smartphones via commonly used weather, gaming, email and religious apps. It can build a detailed picture of where a smartphone has been over the past 12 months, and update the data hourly, showing the movements of people on a near real-time basis. Law enforcement officers can use Webloc to zero in on a map and look at all phones that were present at a specific place and time, analyzing “billions of location data points,” according to company documents reviewed by Bloomberg.
There’s a nice infographic that explains how the system works at the link.
11:21
Grrl Power #1512 – And the fighting continues… [Grrl Power]
So we’ve got 3 fights going simultaneously now, and as usual I’m torn between drawing awesome looking high-level shonen style fights, which necessarily go on for pages and pages, and having a few more of these guys getting knocked out fairly quickly so I can focus on the real final fight. As usual, all the fights in the comic feel like they go on too long while we’re all waiting for the two pages a week I can put out, but then when you read through the archives, a 100 page fight is done in half an hour.
I’ve been intercutting the fights with commentary by Sydney and others to interject some humor, but I still want to get the team all in the same room again so I can have Dabbler do something inappropriate to rile up Maxima, along with the other usual japes. So we’ll see how these fights go. I don’t want to rush them, but I also don’t want them to drag on either, and I have a few important moments to hit along the way.
Here you go, a brand new vote incentive. Featuring the least sexy character in
the comic. No, I take that back, Cooter is the least sexy, but
don’t expect a pinup of him anytime soon. Or ever. There is a nude version over at
Patreon. Note I didn’t say NSFW. She is nude in those
picture, and she does identify as female, but it’s…
hard to tell. She is a humanoid aberration by D&D terminology,
not a mammal. And before you ask, no, I don’t know how many
vertebrae she has in her neck.
Double res version will be posted over at Patreon. Feel free to contribute as much as you like.
10:49
Learning from rejection [Seth's Blog]
If you’re doing something creative, something important or something new, you’re certain to be rejected along the way.
It’s a signal. It might be proof that you offered it to the wrong person, or that the right person saw something about your work that didn’t serve their needs. Without learning from this signal, we’re doomed to experience it again and again.
What do we know for sure?
It was rejected.
What else?
Nothing. The reasons listed in the rejection letter are almost certainly made up. Perhaps they’re insulating themselves from being re-sold (“you said you didn’t like the color, but we have other colors!”) or perhaps they’re protecting your feelings. It could be that they aren’t telling themselves the truth, or don’t want to be hassled for telling you the truth.
Few people explain their rejection with, “I’m afraid,” or “I wanted to do it but my boss won’t let me,” or “you have bad breath and I don’t like you.”
Being rejected hurts, and we’re likely to marinate in the pain. We imagine that the person who rejected us understands everything about what we offered, is a rational actor and cares as much as we do. While we’re at it, we personalize, amplify and multiply the rejection.
But all we really know is that this person, on this day, in this situation, hearing the story the way we told it, said no.
Years ago, I self-published a booklet for political activists. My timing was good, and I had a chance to sell the books from an organizer’s booth at a march on the very topic my book was about. It was a beautiful April day, and I stood on the side of route as the march went by. More than 400,000 passed my table, and I sold four books.
That’s 399,996 rejections. Maybe more.
Was it the price? Halfway through the march, I lowered it from $10 to $1, just to have a good story to blog a few decades later.
Sales did not increase. Perhaps it was the color of the jacket, the page count or the typo on page 32? None of those things.
What did I learn? That people at a march are at the march to march, not to shop.
Watch what people do, not what they say. And if you really want to learn something, change the situation and see what happens the next time.
Learning from rejection begins with understanding the lesson that’s being offered.
10:21
I’m not descending into madness because mount and unmount icons make no sense [OSnews]
There are many problems in this world – some big, some small, some so minute nobody ought to put them to paper at all. The problem I’m going to highlight here is even smaller than that. This literally – the actual literally – does not matter and absolutely nobody should care about it, let alone put any work into changing it or addressing it some other way.
I want to talk about the iconography GNOME’s Disks utility uses to symbolise “mount” and “unmount”. No, I’m not descending into madness.
GNOME’s Disks utility uses the “play” symbol on the mount button, and the “stop” symbol on the unmount button. Inexplicably, considering the state of the world in general and the rapidly deteriorating quality of software specifically, this bothers me. Out in the real world, built on decades of consistent use, these symbols have gained clearly defined meanings, and mounting and unmounting disks definitely isn’t one of them.
In fact, the meaning of these symbols isn’t mere convention; they’re defined in a variety of international standards for symbols for use in software and on equipment, such as ISO/IEC 18035 (which you need to buy to read; my copy fell of a truck):
ISO/IEC 18035:2002 defines a consistent set of icons and related functions that are represented by multimedia applications on a computer screen and that users interact with to control such applications. It describes controls applying to such functions as: Play, Pause, Stop, Rewind, Scan forward, Scan backward, Replay backward, Loop, Go to beginning, Go to previous, Go to next, Go to end, Set volume and Mute.
↫ ISO/IEC 18035:2003
They’re also part of ISO 7000/IEC 60417, a much larger, more encompassing standard that also contains things like the various symbols used on laundry machines, tumble dryers, in cars, and so on. The symbols themselves are much older than the standards, of course, with many of them dating back to the 1960s and possibly even 1950s. The point remains, though: the play and stop symbols have clearly defined meanings, and I don’t think they are at all a good fit for mount and unmount.
The function of the “play” symbol according to ISO/IEC 18035:
To enable the user to start the presentation of dynamic media, except where the task requires automatic playing of that media.
↫ ISO/IEC 18035:2003
And of the “stop” symbol:
To enable the user to stop the presentation of dynamic media.
↫ ISO/IEC 18035:2003
Neither of these descriptions match what mounting and unmounting mean or do. Mounting a drive or partition doesn’t present any media at all; it merely makes the drive or partition in question accessible. Unmounting also doesn’t eject anything; it merely makes the drive or partition inaccessible. I would argue that play and pause act upon contents of a drive or volume, and not upon the drive or volume itself. As it stands right now, you “play” a drive” to “play” a video stored on said drive.
Madness.
I already know what you’re thinking, and yes, I agree that the Disks utility is a tool aimed at more advanced use cases and users, and most normal, average users will never even know it exists, let alone open it at all. Very few people get to see these symbols, and those that do already know full well what mounting and unmounting mean, reducing the importance of said symbols considerably. But now it’s time for the big surprise, the twist in the story that turns this entire thing on its head.
Files, GNOME’s file manager, uses an entirely different symbol for unmounting! Instead of the “stop” symbol, Files uses the “eject” symbol. You may think this is a more accurate visual representation of what unmounting means, but I strongly disagree. Let’s turn to ISO/IEC 18035:2003 once again:
To enable the user to eject the current physical media from the appropriate drive.
↫ ISO/IEC 18035:2003
Unmounting doesn’t eject anything! If you unmount a USB stick, the stick doesn’t get fired out of the USB port. If you unmount a volume, it doesn’t get removed from the SSD. Hell, if you unmount a CD-ROM, it doesn’t even eject it! Ejecting a CD-ROM – opening the drive’s tray or spitting the CD-ROM out of a slot-loader – is an entirely different act! Are we really “ejecting” a CD-ROM twice? Are we “mounting” a CD-ROM when we merely close the tray? No!
Madness!
The real underlying problem here is, of course, that mounting and unmounting are deeply weird and confusing concepts, bordering on the esoteric, that simply do not have physical equivalents to fall back on. Using symbols and iconography designed in the 1960s explicitly for playing music or stopping a video or ejecting a cassette tape are not a good fit for something as difficult to explain to most people as mounting and unmounting. It’s like putting an eject symbol on a car’s door handle or a play symbol on a soap dispenser.
Should GNOME developers waste any time or resources to address this? No, of course not, that would be stupid. Nobody should care about this but me. I should suffer in silence, every time I need to mount or unmount something, forced to look for an eject or stop symbol in whatever user interface I happen to be using. Every time, I should die a little inside. Please, don’t be like me and waste precious resources thinking about this.
I’m not descending into madness. I just want mount and unmount symbols that make sense.
I’m not descending into madness.